

unschooled autodidact interested in inner work / self development / understanding myself and others. technical staff @ https://xitter.cf/t.co/1HqI3jcQqL
San Francisco
Joined September 2019
- Tweets4.8K
- Following353
- Followers1.3K
- Likes10.8K






harder and less sexy and far more important lol. extremes are nice bc they never happen
I used to really relate to Grenade by Bruno Mars, listening to it now i see he has issues (that i also had/have)
love a song -> grow -> see song as evidence of mental illness

weird thing here is that i expect nick would have predicted all these results & it’s mostly talking past each other, different meanings of “understand”, standards of evidence, etc

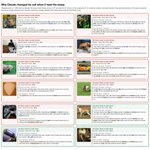
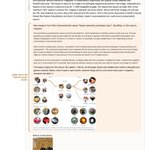
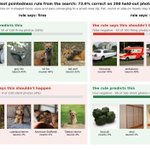
@nickcammarata's essay says InceptionV1 neuron 4e:55 fires on pointed things and not round ones. on the essay's own photos (top), that holds. on other ImageNet photos (bottom), all four combinations happen: round fluffy faces fire, pointy German shepherds stay silent 🧵

me/cfs is horrible! I’ve known adic a long time and it’s been awful to see her life get destroyed from this. i really hope we get large advances in biology soon!


@nickcammarata's essay says InceptionV1 neuron 4e:55 fires on pointed things and not round ones. on the essay's own photos (top), that holds. on other ImageNet photos (bottom), all four combinations happen: round fluffy faces fire, pointy German shepherds stay silent 🧵

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/

to conclude, if there's a crisp pointed vs round distinction here, I can't find it! I'd love to see if nick can predict this neuron better with his understanding now (as opposed to before) or figure out other good sharable "proofs/evidence of understanding"
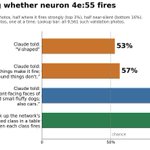
experimental details and more experiments: ulissemini.github.io/4e55-ga… (got seriously nerdsniped)
there's more i'm curious about, like ideas for leveraging LLMs to their full epistemic potential (infinite smart researchers, blinded however you want!) but that will have to wait. I've spent too long on this already 😅
bullish on approaches like this

it bothers me when people use unfalsifiable as a synonym for unscientific. the gap between ‘hard to get evidence either way’ and ‘impossible to get evidence’ is infinite oceans wide
looks v cool but also the hype is running far ahead of sane evaluation rn imo. time will tell
interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/