

Assistant professor of computer science at @univmiami. My research is at the intersection of multimodal machine learning and linguistics.
🌎
Joined May 2017
- Tweets588
- Following980
- Followers480
- Likes2K



Pinned Tweet
The number of languages in the world just got a lot higher! At least constructed ones.
Meet ConlangCrafter - a pipeline for creating novel languages with LLMs.
A Japanese-Esperanto creole? An alien cephalopod color-based language?
Enter your idea and see a conlang emerge. 🧵👇

Very interesting taxonomy of LLM writing tics!
I'm not sure how exhaustive this is but it definitely includes some points that rub me the wrong way in LLM slop writing...


🎉 Accepted to #ArabicNLP2026! Led by @BenThereDonDhat.
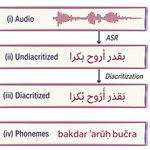
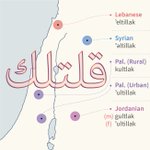
Levantine Arabic (LA) is diverse and under-resourced for speech technology. Our new benchmark SHAMS is designed to spur progress in tech for LA across its regional varieties! Details below. @_ArabicNLP

Key findings:
• Levantine-aware systems beat MSA-trained ones, regardless of size
• Even the best ASR model gets ~1 in 4 words wrong (>27% WER)
• Pronunciation is hardest: audio-to-phoneme is >20% CER
These results results highlight recent progress in LLMs and dialect-aware models as well as remaining gaps in LA speech tech. More details:
📄 Paper: arxiv.org/abs/2610.01427
🌐 Project page: shams-nlp.github.io
📁 Dataset: huggingface.co/datasets/sham…

Morris Alper retweeted

2 sentences in 20 Mayan languages.
youtu.be/urBa56k_uDo?si=BXlr…

Thrilled that we were selected among this year's @schmidtsciences Humanities and AI Virtual Institute (HAVI) grantees! 🎉🥳
"Tracing the Signs: Multimodal Foundation Models for Ancient Writing"
Looking forward to developing AI for ancient writing systems!
schmidtsciences.org/havi-202…

Check out our new paper! Speech models struggle to mix sounds from different languages -- we discover mechinterp reasons for this and find a fix!

Morris Alper retweeted

Sadly this continues to be relevant:
kalzumeus.com/2010/06/17/fal…
Great summary that mostly aligns with my own thoughts on this.
It's too bad that AI slop writing is eroding our trust in good-faith communication.

My inbox is being flooded with fully AI-generated emails from prospective students. I tried to work out why I can't bring myself to read them, and ended up with some thoughts and advice for writing cold emails in the age of AI.
My new post:
blekhman.substack.com/p/why-…
Awesome to get a warm welcome at UM!
as.miami.edu/news-and-events…

Just arrived in Sydney! Happy to connect with anyone working on speech-language tech for low-resource languages or beyond. Hit me up if you’d like to get coffee.


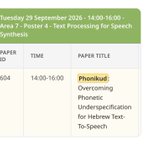
Heading to Sydney for Interspeech 2026 to present our work Phonikud on Hebrew G2P and TTS! 🇦🇺
If you are attending, come say hi! I will present on Tuesday - Area 7, Poster 4, paper 604.


Update: CWoMP was just accepted as an oral presentation at #EMNLP2026! 🚀
Check out our work on using morpheme representations to gloss endangered languages! I also think this could have interesting extensions to other domains with sequence data.

Accepted to #EMNLP2026 main! 🎉
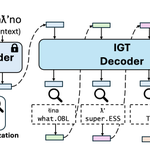
Interlinear glossed text (IGT) is standard for documenting endangered languages, but it is laborious to produce by hand.
CWoMP uses contrastively learned morpheme representations for interpretable, efficient, retrieval-based glossing!
🧵👇

This is a good description of the problem with LLM slop proliferation in general. It feels like we're losing track of language's primary goal as being a means of communication...

This is precisely right. As a track chair at Neurips, I am seeing cases where the papers were written by LLMs, reports likewise, rebuttals too, even in some cases Area Chairs joining the flood. It becomes a potemkin village where nobody is actually accountable for anything that they are saying, and neither individual understanding nor our collective epistemic projects make *any* progress at all.

I did a video interview on ConlangCrafter!
(Adding a bit of nuance: I don't think it itself preserves languages, more that there is promise in adapting some of its techniques in the future for low-resource NLP.)
nbcmiami.com/news/local/want…

Accepted to #EMNLP2026 main! 🎉
Interlinear glossed text (IGT) is standard for documenting endangered languages, but it is laborious to produce by hand.
CWoMP uses contrastively learned morpheme representations for interpretable, efficient, retrieval-based glossing!
🧵👇
Our results show strong performance across typologically diverse languages, particularly in the most extreme low-resource settings (e.g., Gitksan with only 31 training examples).

Check out our project page, paper, and open code repo for more:
Page: cwomp.github.io
Paper: arxiv.org/abs/2603.18184
Code: github.com/morrisalp/CWoMP