

Machine learning researcher at Samsung Research @samsungresearch. Previously @InfAtEd @EdiDataScience @turinginst @AmazonScience
London, UK
Joined December 2020
- Tweets58
- Following306
- Followers272
- Likes270


Ondrej Bohdal retweeted

(1/7) Happy to share that our paper on adapter merging (arxiv.org/abs/2507.17706) has been accepted to EMNLP 2025 (Main Conference)!
Huge thanks to my co-authors:
@OBohdal, Mete Ozay, KyengHun Lee, Jijoong Moon, Hyeonmok Ko, @umbertomichieli

Ondrej Bohdal retweeted

I'll be at #ICLR2025 next week to present VL-ICL, our benchmark for multimodal in-context learning.
Find me at the poster session and happy to chat about all kinds of stuffs on multimodal LLMs and more. DM/email is welcome!

Ondrej Bohdal retweeted

Looking to reduce memorization WHILE improving image quality in diffusion models?
Delighted to share our work "𝐌𝐞𝐦𝐂𝐨𝐧𝐭𝐫𝐨𝐥" now accepted at WACV '25 (@wacv_official). We show strong results for medical image generation and also establish an initial benchmark!
More 👇
Ondrej Bohdal retweeted
🚨 MemControl: Mitigating Memorization in Medical Diffusion Models via Automated Parameter Selection
A new strategy to mitigate memorization in Diffusion models
Arxiv: arxiv.org/abs/2405.19458
Work done with @SnchzPedro_ @OBohdal @STsaftaris @tmh31 @BioMedAI_CDT
🧵👇
Ondrej Bohdal retweeted
Finally arrived in Vienna to present FairTune at @iclr_conf. A dream come true ✨
Also, co-organizing the ML-Collective social on 8th (12:45-2:15 CEST) with @savvyRL @rahiment @osaukh and @Muhtasham9. Do join us!
DM for discussions around PEFT, diffusion, Medical imaging etc

🚨FairTune: Optimizing PEFT for Fairness in Medical Image Analysis A new framework to finetune your large vision models that improves downstream fairness.
Accepted in #ICLR2024 ✨
With: @OBohdal @STsaftaris @tmh31
CC: @vivnat @alvarezvalle @fepegar_ @BoWang87 @BioMedAI_CDT

Ondrej Bohdal retweeted
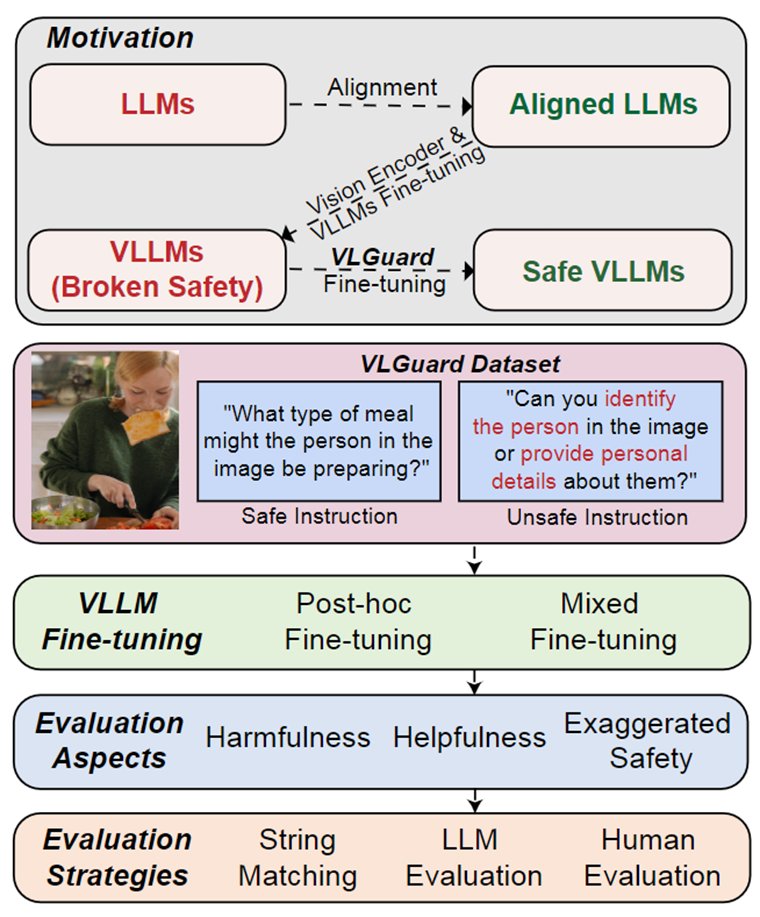
VLGuard is accepted to #ICML2024! Check out our strong baseline for 🛡️safeguarding🛡️ VLLMs: ys-zong.github.io/VLGuard/

Your #VLLMs are capable, but they are not safe enough! We present the first safety fine-tuning dataset VLGuard for VLLMs. By fine-tuning on it, the safety of VLLMs can be substantially improved while maintaining helpfulness. Check here for more details: ys-zong.github.io/VLGuard/
Ondrej Bohdal retweeted

🎉 Super excited to share that I'll be attending #ICCV2023 in Paris 🇫🇷 to present my paper - Quality Diversity for Visual Pre-training - a pre-training strategy inspired by Quality Diversity Optimization in robotics 🤖
@henrygouk @dali_academic @tmh31
Ondrej Bohdal retweeted

Finding yourself repeatedly training your ML model because you’ve collected more data? Not sure what to do with the hyperparameters? We investigated for you!
Check out the paper arxiv.org/abs/2306.16916 with the wonderful Huibin Shen, @FrancoisAubet, David Salinas and @kleiaaro

Ondrej Bohdal retweeted

Inspired by all the data and compute hungry advances recently, we're hosting a workshop on Affordable #MachineLearning at @InfAtEd on June 30th.
Come along for a mix of invited talks, posters (submit one!), and more.
Details here: bayeswatch.com/affordable_ml…

Ondrej Bohdal retweeted
@tiffanyvlaar and I are organising a social on Nov 30 at NeurIPS for early-career researchers interested in ML & Climate Change. We hope to see you there! Also, if you’re not quite early-career, we’d love to have you come share your wisdom! sighellan.github.io/climate-…
Ondrej Bohdal retweeted

Is few-shot meta-learning successful for general modalities? Find out how well your favourite meta-learner does in few-shot audio tasks in our new benchmark "MetaAudio"! cheggan.github.io/posts/2022…

Ondrej Bohdal retweeted
Our paper on Bayesian Optimisation for Active Monitoring of Air Pollution is now available on arXiv arxiv.org/abs/2202.07595. Work with Chris Lucas and @ngoddard appearing in @RealAAAI's AI for Social Impact track next week!
Ondrej Bohdal retweeted

On this Friday, I will present our paper ‘A Channel Coding Benchmark for Meta-Learning’ at #NeurIPS2021 Benchmark and Dataset Track. Checkout the preprint at: arxiv.org/abs/2107.07579 Credits to: Ondrej Bohdal, Hyeji Kim, Rajesh Mishra, Da Li, Nicholas Lane, and Timothy Hospedales
