





🔥 GPT-6.2 Sol的实力就这么强啊
👀 有点期待GPT-6.2 Astra的表现
😮 OpenAI这次难道真的超越Anthropic了?
⚔️ 还是继续会被即将推出的Fable5.5压一头


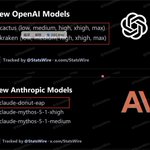
🚨 Devin CLI 里,短短几个小时就"露出"了 OpenAI 和 Anthropic 的新模型:
🟣 Anthropic
>claude-donut-eap
>全新的 Mythos 5.1 推理层级
🟢 OpenAI
Aurora-Alpha 和 Halo-Alpha,均提供 五档推理级别
🔍 猜测:它们可能就是 Fable 5.5 和 GPT-6.2 Astra/Sol。
✅ 从迹象看,这些模型已基本准备就绪
📅 下周将是重要的一周,值得密切关注 👀


new OpenAI and Anthropic models have been spotted in Devin CLI, just hours apart.
• claude-donut-eap and new Mythos 5.1 reasoning tiers
• aurora-alpha and halo-alpha with five reasoning levels
they could possibly be Fable 5.5 and GPT-6.2 Astra/Sol
they look prepped for release, but with the recent safety concerns, i’m not convinced we’ll see them released just yet.

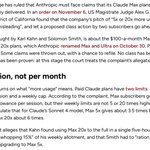
⚖️ 联邦法官裁定:Anthropic 须应对 Claude Max 套餐"货不对板"的指控
📌 法官认为"比 Pro 多 5 倍/20 倍用量"的宣传"可能具有误导性",允许两名订阅者的集体诉讼继续
📊 原告测算(针对 Sonnet 4 模型):
▫️ Max 5x ≈ Pro 周用量的 3.5 倍
▫️ Max 20x ≈ Pro 周用量的 6 倍


🚨 一觉醒来,GPT 开始封号了?
👀 听说:OpenAI 把 A÷ 的人挖过来了
🤣 结果……连"封号"这门手艺也一起挖过来了?
🎯 据反馈,目前主要针对:
🇹🇷 土区
🇵🇭 菲区
👉 也就是低价区订阅账号
💾 赶紧备份对话
GPT-6.2 Astra / GPT-6.2 Sol🙅♂️

A new way to measure how AI agents handle the routine analyses of wet-lab science—BioBasicsBench.
Developed with Ligo, a biotech company focused on enzyme design, the benchmark draws on 100 tasks from real experiments to test whether agents can interpret raw lab data, identify errors, and recognize when the evidence doesn’t support a conclusion.
Accelerating biological research starts with getting the everyday work right. BioBasicsBench shows where models need to improve, and helps us track what those gains mean for scientific progress, biosafety, and biosecurity.
openai.com/index/measuring-h…
