

A small farm in the mountains.
Joined February 2013
- Tweets334
- Following6K
- Followers772
- Likes5.9K



OpsConfig retweeted
Narrator: he was not, in fact, allowed to say “I’m quite unhappy with much of what OpenAI does.”

I’m quite unhappy with much of what OpenAI does.
I am very happy that I’m allowed to say “I’m quite unhappy with much of what OpenAI does.”
Readers added context they thought people might want to know
Korbak was fired ~3 weeks later. He says for safety concerns/METR talks (his job); OpenAI says mishandling sensitive info, not for speaking out.
x.com/tomekkorbak/st…
x.com/OpenAINewsroom…
OpsConfig retweeted

Getting to watch these beagles from Marshall Bioresources run on the grass for the first time was pure joy!
#beagles #dogsofx #marshallfarms #labdogs
OpsConfig retweeted

New Paper: Turns out that LLM think traces don't necessarily have any end-user semantics even on benchmarks specifically designed to showcase such semantics.. 🤷♂️
As some of y'all know, we have been looking at the question of end-user interpretable semantics for the reasoning models for a while (c.f. arxiv.org/abs/2504.09762 (#ICML2026),
arxiv.org/abs/2505.13792 (#ACL2026) &
arxiv.org/abs/2505.13775 (#TMLR➡️#NeurIPS2026))
One question I get asked is whether that lack of semantics just an artifact of the benchmarks *we* made.
What if we look at benchmarks that were specifically proposed to show off the semantics of thinking traces?
As it happens, earlier work by AllenZhu @ZeyuanAllenZhu has indeed created such a benchmark, iGSM, and made claims about intermediate token semantics based on it.
Since AllenZhu's work on "Physics of LLMs"--that is partly based on their analysis on iGSM was influential, we wondered whether they found conditions under which traces do indeed have semantics.
Turns out, (perhaps unfortunately for the "please let thinking traces have semantics" contingent), that iGSM traces don't have semantics either, and models trained with swapped/corrupted traces can do well too. The results seem quite in line with--rather than being contrary to--the position we have taken in our earlier work.
Read the details of this very crisp work, lead by @ratishsp and Pranabendu, in the following thread.👇 – at Tempe, AZ


Happy to share our paper, "Correct Answers, Invalid Traces: What Verifiable Grade-School Math Reveals About Chain-of-Thought Traces".
When a model gets the right answer, is the reasoning it produces also right? We test this on synthetic grade-school math where every step of a trace can be checked by a program.
Thread below.

A few thoughts on why @AnthropicAI's Opus 5 sometimes felt lazy compared to @OpenAI 's models.
I like to use chess as a benchmark/eval for AI models.
It is a crude/toy benchmark, but it does a good job of giving a sense of when the frontier model's make leaps forward and helps temper some of the benchmaxxing.
1/
While regardless of chess performance Anthropic models have continued to get stronger in other domains, my own anecdotal experience was that Opus 4.5 and Opus 4.6 were the last Opus models to feel consistent.
Ever since Opus 4.7 I feel like I am constantly having to correct and double-check the model's work.
One moment the model feels smart, the next it is apologizing to me for the umpteenth time for having made a mistake.
These days anytime I use an Anthropic model for any serious work I am constantly farming out adversarial reviews to codex/OpenAI models.
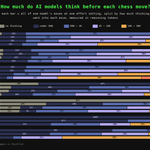
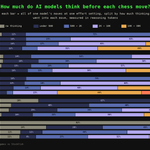
This change in anecdotal vibes for me coincided with Anthropic's shift to "adaptive thinking".
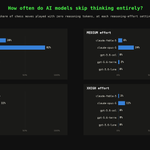
The older model's used the now deprecated "extended thinking" feature. If we add in data on the older model's we see a profile far closer to the OpenAI models as far as thinking token allocation.
Adaptive thinking definitely saves money on a per API call basis, but I do wonder to what extent that comes at the cost of quality.
8/

Comparing thinking tokens across models/providers is fraught, and of limited value.
Different models, different backend implementations, different tokenizers, etc.
Stronger models should be able to solve more complex problems using less thinking tokens/test time compute.
The older pre-adaptive thinking Opus models are weaker so even with higher thinking token allocation their performance on chess doesn't improve enough to catchup to latest OpenAI models.
With that said, I do think there is value in tracking reasoning/thinking token allocation to see how often low/zero thinking token allocation corresponds to poor performance.
Based on the tokenizer data the new stealth model "space-bunny-alpha" appears to likely be part of MiniMax lineage.

Out of curiosity, I ran it through my standard chess eval gauntlet on low, medium, high, and max. It lost every game except one.
Here is one of its losses, mate in 7 moves with stockfish at 1320.
All match replays have been added to the library:
codeandstream.com/chess/#g=s…
OpsConfig retweeted

Annie Dillard has died. In our Summer 1988 Issue, she wrote about the "surprising letters" and gifts that fans and readers sent her over the years—a fossil fish, a marriage proposal, a check for $2.50, and, again and again, questions about God. yalereview.org/article/annie…

OpsConfig retweeted
Breaking News: Annie Dillard, the Pulitzer Prize-winning author of the modern classic “Pilgrim at Tinker Creek,” has died at 81. nyti.ms/4hrp9BD

OpsConfig retweeted

A lovely @nytimes obit for my brother who died on Labor Day.
Jonathan Cooper, Who Made Violins the Old-Fashioned Way, Dies at 76 nytimes.com/2026/09/12/arts/… via @NYTimes


OpsConfig retweeted

Two heroes of today's Navier-Stokes story are not getting enough credit. Córdoba and Martínez-Zoroa came up with the crucial strategy. Others built on it and, with the help of AI, provided the computations that finished the problem. Thankfully @QuantaMagazine gets this right:

As much fun as it is to have LLMs play against stockfish, sometimes it's nice to watch some 1v1 matches.
Twenty games of GPT-6 Astra versus Fable 5.1 are now up on:
codeandstream.com/chess