

Autonomous design for industrial controls (YC S24)
Joined July 2024
- Tweets31
- Following1
- Followers810
- Likes43




Outerport retweeted

スケルトンゲームボーイ的な筐体の中で、プリント基板上で動くプラントシミュレータのおもちゃを弊社システムで一気通貫でやらせてみた
こちらは実際に製作してみて弊社の記念品として用意する予定です・・・


Outerport retweeted
ダイキン工業様との協業を発表しました!設計でのAI活用において、必要なノウハウが詰まっている図形・図表を構造化するOuterportの技術を本格導入していただきました。
CG/CV/AIの技術を総動員して、新たなハードウェア技術の設計・開発・製造がもっと速くできる世界を目指して精進いたします🛠️🏭⚙️

Outerport retweeted

ダイキン工業、AIによる図表・図面の「構造化」プラットフォームとしてOuterportを導入し、AIエージェント活用を推進 prtimes.jp/main/html/rd/p/00…

Outerport retweeted
Parsing CAD drawings is one thing but parsing architectural plans takes the craziness up a notch

Outerport retweeted
Yeah document parsing is cool, but what about CAD drawing parsing... (but with documents too 🥺)

Outerport retweeted

My little prediction of 2025: As AI scaling is plateauing (steady amazing progress like microprocessors vs jumps), we'll begin to see more of a focus on products.
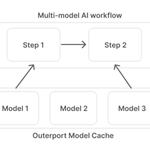
Instead of a multi-modal architecture, there will be a focus on a multi-model architectures: how do we jointly train and integrate the AI models to work together to maximize perf while updating the models quickly.
I would expect to see every major industry get targeted (already happening): AI graphic designer, AI programmer, AI lawyer, AI doctor, AI chip designer, AI FP&A, etc.
The AI labs will have to cut burn and finally ask themselves: who is this for? why do they want it?
Outerport retweeted
.@outerport is building the infrastructure base for multi-model architectures; figuring out the technical details like hot-swapping, time multiplexing, live-deployments, kv cache management, and more 😉

My little prediction of 2025: As AI scaling is plateauing (steady amazing progress like microprocessors vs jumps), we'll begin to see more of a focus on products.
Instead of a multi-modal architecture, there will be a focus on a multi-model architectures: how do we jointly train and integrate the AI models to work together to maximize perf while updating the models quickly.
I would expect to see every major industry get targeted (already happening): AI graphic designer, AI programmer, AI lawyer, AI doctor, AI chip designer, AI FP&A, etc.
The AI labs will have to cut burn and finally ask themselves: who is this for? why do they want it?
Outerport retweeted
How do you hide latency for loading models from disk?
Most implementations do disk -> CPU RAM, and then a CPU RAM -> GPU RAM sequentially. The latency of loading into the GPU is the sum of the two steps.
In practice, these 2 steps can actually be interlaced because a model weight is not a blob of memory and is actually a collection of tensors.
We can hide the latency of the model load by parallelizing disk->RAM and the RAM->GPU by processing these two tasks in 2 different thread pools that communicate to each other with a channel queue that sends over tensors.
One pool of threads will load memory pages and mark named tensors as complete when all pages have loaded, and push the tensor onto the queue. Another thread will take in completed tensors and start the transfer into GPU for that tensor.
In a naive implementation this would actually be very slow since each tensor can be small and opening up a CUDA context and kernel for each named tensor would create large amounts of overhead. So, we also need to do buffering so that there is a sufficiently large set of tensors that are marked complete before a batched write to GPU happens. (We experimentally determined 64MB pages are pretty good 🙂)
As a result the bottleneck ends up being almost entirely the "disk to RAM" step- because the RAM to GPU is comparatively fast and can be parallelized.

We think that this is exciting because it will unlock more creativity by allowing for more complicated AI workflows where multiple models need to be loaded in sequence.
We have already seen creative technologists do amazing things with AI workflows using tools like ComfyUI.

1
3
305


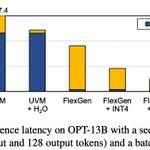
One of the interesting graphs is the comparison against CUDA virtual memory- implicit memory management through the device driver always loses in comparison to explicit memory management systems like FlexGen, InfiniGen.

221

Outerport retweeted

2️⃣ Developer tools and automation are hot
26% of the AI startups are building scaffolding for the next tech boom, making it faster & easier to build better AI applications.
@keetapi: APIs for any website
@outerport: VMWare for GPUs
@mem0ai: Memory layer for AI agents
+48 more