




john retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

john retweeted

Stageshow: a skill that helps your agent make better faux UI stills, animations, bento grids, and more.
npx skills add benjitaylor/skills --skill stageshow
john retweeted

trivia:
• started working on the game as a side project 4 days ago, landing ~1,150 PRs
• every time i found an issue in the code i asked bot to make a lint rule against it
• used TLA+ heavily to find bugs in the game's various state machines: the story, cutscenes, the game's systems. there are many formal verification skills, one for each major system
• i put context into the filepaths: code that runs every frame or every tick gets a .hot.ts extension, and a lint rule bans allocating in it (no object literals, closures, new, etc.), so the game loop creates almost no garbage and GC doesn't cause stutters
• game engine is mostly custom. three.js draws the 3D scene, but the simulation, post-processing and audio are all ours
• the simulation is fully deterministic, so every run replays exactly from its inputs. when you post a high score, the server replays your whole run to check it isn't cheated
• we generate dynamic og:images for every run based on your final stats, and it's all localized too! the game supports 10 languages
• my favorite feature: the music seamlessly transitions into different music for the various biomes, continuing the previous melody
• no audio files. all the music and sound effects are synthesized live in the browser by a custom Game Boy-style chip (two pulse voices, a wave voice, noise) plus a synthwave layer. the songs are written as text in code
• all the pixel art is code. every sprite is a file drawn with one shared palette and packed into a sprite atlas at build time
• it runs inside an X post, from the 245px card up to full screen. the bar is 60 fps with 500 enemies on a mid-range phone
• the build fails if the first download goes over budget. it's about 124 KB gzipped right now
• bots play the game headless to tune each difficulty against target survival rates
• comments are banned by a lint rule. if code needs explaining, the fix is a better name or a test


john retweeted

Yann LeCun and Randall Balestriero just Proved the Platonic Representation Hypothesis, and found a better way to achieve it.
The Platonic Representation Hypothesis suggests that AI models trained on different modalities, like images and text, eventually learn similar representations of the world. But this paper shows that how models are trained matters more than simply scaling them up.
So they mathematically show that, under certain conditions, two JEPAs trained completely separately can learn essentially the same underlying representation of the world. One learns from different images of the same scene, while the other learns from different descriptions of that scene, without ever being trained on image-text pairs.
Their approach achieves the same image-text alignment with 42x fewer training samples than next-token prediction. A 109M-parameter text JEPA even outperforms LLMs up to 72B parameters on cross-modal alignment benchmarks.
alphaxiv.org/abs/2610.39302

john retweeted

use this prompt on your favorite codebase where you don't hate your users:
do a deep scan of all hot paths and fix any unnecessary sequential async functions calls
the diffs are very easy to review and almost always find some bangers

john retweeted

i don't wanna watch a video so my agent found some useful stuff
- put your agent config in git
- keep the always-loaded rules file short. Move everything else into skills
- run a nightly (dreaminig) job that reviews the day's sessions and proposes fixes for you to approve
i adopted this for my personal open code setup and the dreaming nightly job has been super helpful on finding friction points
skill below

This is f*cking insane. Anthropic engineer:
"You're not supposed to prompt Opus 5.5
You're supposed to build a system that prompts itself. At Anthropic, 90% of our engineers have already built these systems"
In 30 minutes, she walks through exactly how Anthropic builds agents that remember, fix their own mistakes and get sharper with every run.
Better than any $1000-$2000 agent course I've seen.
Watch it, then read the article below ↓
Readers added context they thought people might want to know
Lamis never says "You're not supposed to prompt Opus 5.5” in here talk at AI Dev Con.
The caption misrepresents the video knowing most won’t watch the video all the way through and jump to the articles.
youtube.com/watch?v=tTcxVv…
john retweeted

Introducing Hyra 2.0, the next evolution of Hunyuan Research Agent. 💡
From solving problems to building reusable tools, models, and workflows that accelerate future discoveries.
Read our perspective on the next chapter of AutoResearch:
hy.tencent.com/research/hyra…


john retweeted

Hyra is a very ambitious harness project.


Introducing Hyra 2.0, the next evolution of Hunyuan Research Agent. 💡
From solving problems to building reusable tools, models, and workflows that accelerate future discoveries.
Read our perspective on the next chapter of AutoResearch:
hy.tencent.com/research/hyra…

john retweeted

This is f*cking insane. SpaceXAI engineer (ex-Cursor):
"99% of people run one GrokBot for everything
I run 70+ bots, and I only talk to my Chief of Staff"
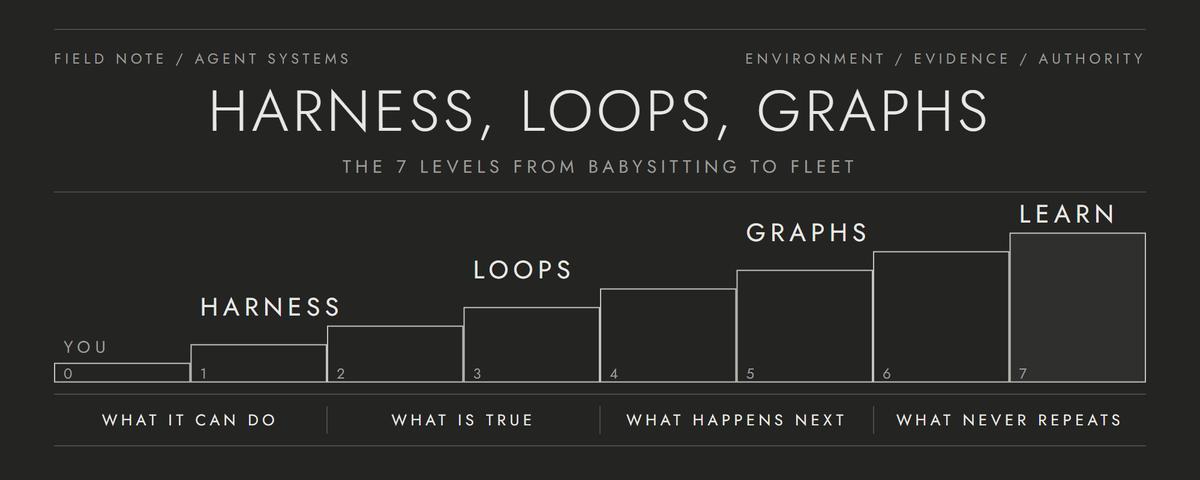
In just 8 minutes, she shows how to turn one GrokBot into a team that runs your email, calendar, Slack and code 24/7
One GrokBot → Specialist Bots → Chief of Staff → Cloud Agents → A Team That Never Clocks Out
A Specialist Bot does one job and keeps its own memory
A Chief of Staff bot watches your Slack and kicks off the work before you ask
Anyone can chat with one bot, almost nobody has a team of them doing the work
Worth more than any $4,000 AI agent course
Bookmark it, watch it today
Then read how to give your GrokBot a real team in the harness engineering guide below ↓

john retweeted

I'm sure that the people who get sent to torture prisons in El Salvador or get shot in the face by ICE or get killed in the war with Iran will understand that @HaleyforMI's hurt feelings were more important.

john retweeted
I'm convinced that at this point, you could have an Opus 5.5 agent re-implement all of CPython probably within two weeks without any human input, against just the tests, and probably with full compatibility with including ABI, no GIL, a jit and probably beat it on all measurable metrics. It's completely crazy.
john retweeted

Sometimes I just say
You need to be thinking bigger. 1% faster is not enough. This should be 10x faster.

some things I often say to claude when doing perf optimization work:
> how do we rewrite this to better leverage data-oriented design principles
> can you replace those hash tables with a flat array? can we make the pointers an index into the array? can we pack the most commonly used data into upper bits of the index?
> caching is cope for a slow design. do not add caches and delete all existing caches. instead, redesign it to be faster
> should this be a structure of arrays instead of an array of structures?
john retweeted

How many parameters does a voice need?
Pi(co) Vo(ice): two English voices in 1.4M parameters, vocoder included. The whole model is 5.8 MB and runs on a CPU, no PyTorch or GPU.
huggingface.co/empero-ai/PiV…
john retweeted

- Claude fighting for you. Short form video and rec sys attractor basins are the cigs of our generation. Your time can be spent in a so much more fulfilling way. It’s insanely user hostile that you can’t turn off YouTube shorts or Instagram reels permanently.
- Way better recs! Current algorithms are primitive.
- Look at what you can do in a weekend now.

Weekend hack: HackerTube. I was annoyed with YouTube's recommendations so I had Claude filter down 43M comments over 20 years of HN to 6,454 videos that keep being recommended. *Significantly* better viewing experience, ~2 hours with Opus 5.5:
hackertube.org/
- Excellent recs without any logins (state is kept in local browser session)
- Thumbnail is a representative frame from middle of the video instead of the super duper A/B test hyper-optimized user uploads
- Underlying data from the comment analysis as one zip file, point your Claude at it and ask for your own version
- HackerTube Longs ✊
A bit more on the process:
I use Claude Code (desktop app for Mac), Opus 5.5 on Medium effort as my default. I only talk to Claude and have it do everything, the only "manual work" I helped with in tandem was in the browser (reminiscent of MenuGen): 1) I had to create some kind of API key from Google Cloud UI to query YouTube for video metadata, 2) I booted up a VPS box for serving and 3) I bought the domain name. Once the box was up I gave Claude the IP and told it update, secure, harden, deploy and optimize the code, and it did the whole thing.
Many awesome projects that would have normally taken weeks/months even can now be few-shotted for breakfast. What else are we not thinking of.


john retweeted
some things I often say to claude when doing perf optimization work:
> how do we rewrite this to better leverage data-oriented design principles
> can you replace those hash tables with a flat array? can we make the pointers an index into the array? can we pack the most commonly used data into upper bits of the index?
> caching is cope for a slow design. do not add caches and delete all existing caches. instead, redesign it to be faster
> should this be a structure of arrays instead of an array of structures?