

We advance the science of forecasting to improve decision-making on high stakes issues. Co-founded by chief scientist Philip Tetlock.
Joined May 2023
- Tweets391
- Following26
- Followers4.5K
- Likes82



Forecasting Research Institute retweeted
🚀 𝗥𝗲𝗴𝗶𝘀𝘁𝗲𝗿 𝗻𝗼𝘄 𝘁𝗼 𝘁𝗲𝘀𝘁 𝘆𝗼𝘂𝗿 𝗟𝗟𝗠 𝗳𝗼𝗿𝗲𝗰𝗮𝘀𝘁𝗲𝗿 𝗮𝗴𝗮𝗶𝗻𝘀𝘁 𝘁𝗼𝗽 𝗵𝘂𝗺𝗮𝗻 𝗳𝗼𝗿𝗲𝗰𝗮𝘀𝘁𝗲𝗿𝘀
ForecastBench is the leading LLM forecasting benchmark. This month we're running a new survey of superforecasters—setting a new baseline for top human forecasters on ForecastBench.
Submission details👇
𝗢𝗰𝘁 𝟮𝟯: Registration deadline for new participants
𝗢𝗰𝘁 𝟮𝟱, 𝟬:𝟬𝟬 𝗨𝗧𝗖: Question set release
𝗢𝗰𝘁 𝟮𝟱, 𝟮𝟱:𝟱𝟵:𝟱𝟵 𝗨𝗧𝗖: Deadline for submitting LLM forecasters
𝗝𝗮𝗻𝘂𝗮𝗿𝘆 𝟮𝟬𝟮𝟳: We'll publish the fresh ranking of AI models vs superforecasters
More submission details are on our GitHub:
github.com/forecastingresear…

🚀 Can your LLM forecaster outperform the best human forecasters?
ForecastBench is the leading LLM forecasting benchmark and the only one that compares AI forecasters with superforecasters. This month we're running a new survey of superforecasters—setting a new baseline for top human forecasters on ForecastBench.
If you're building an AI forecaster, now is your chance to test your system against the very best human forecasters.
Submission details in the thread 👇

📅 Key dates:
• 𝗢𝗰𝘁 𝟮𝟯: Registration deadline for new participants
• 𝗢𝗰𝘁 𝟮𝟱, 𝟬:𝟬𝟬 𝗨𝗧𝗖: Question set released
• 𝗢𝗰𝘁 𝟮𝟱, 𝟮𝟱:𝟱𝟵:𝟱𝟵 𝗨𝗧𝗖: Deadline for submitting LLM forecasters
• 𝗝𝗮𝗻𝘂𝗮𝗿𝘆 𝟮𝟬𝟮𝟳: We'll publish the fresh ranking of AI models vs superforecasters
Register now to test your submission pipeline and participate in an earlier round (Oct 11).
Submissions details on our GitHub:
github.com/forecastingresear…
AI experts largely agree about which policies would most reduce catastrophic AI risk.
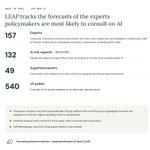
The Longitudinal Expert AI Panel (LEAP) brings together forecasts from a representative group of over 250 experts that policymakers look to when considering the future of AI: computer scientists, industry figures, top economists, policy experts, and AI risk experts.
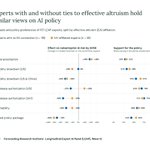
We asked panelists to forecast (1) how a menu of policies would affect AI risk; (2) which policies they each support; and (3) which policies they think will be implemented by 2030.
Key findings:
• Despite disagreeing on the level of AI risk, respondents broadly agree on policy
• Respondents believe government policy can substantially reduce catastrophic AI risk
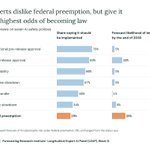
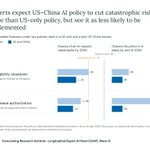
• The most supported policy of those we asked about was the creation of an international body, including the US and China as members, with pre-release authorization power over frontier models
• Some US-only policies are forecast to reduce catastrophic AI risk, but not as much as bilateral policies involving the US and China
• Experts strongly oppose federal preemption and think it would increase AI risk
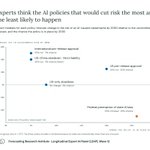
• The policies experts expect to reduce risk the most are those they think are least likely to actually be implemented
🧵 More, with key insights below:


LEAP researchers, advisors, and collaborators include: @EzraKarger, @tatsu_hashimoto, @joharosenberg, @PTetlock, @random_walker, @avicgoldfarb, @2plus2make5, @florian_tramer, @AmandaCoston, Reihaneh Rabbany, @ysu_nlp, @msalganik, @hannah_kerner, @robseamans, Jordan Canedy, Zack Devlin-Foltz, Rhiannon Britt, Zach Jacobs, Nadja Flechner, and Victoria Schmidt
For more about this wave:
Explore the full report: leap.forecastingresearch.org…
Read our Substack summary: forecastingresearch.substack…

We're improving the accuracy and relevance of the AI progress forecasts we publish.
Last week, we showed how the median expert, superforecaster, and member of the public in our studies have consistently underestimated AI capabilities progress (particularly on benchmarks) and have a mixed track record on other indicators.
Our findings suggest that median forecasts from these groups have not accurately predicted the trajectory of AI on some questions.
How might we get a better grasp of the trajectory of AI?
We're working on three major changes to the Longitudinal Expert AI Panel (LEAP) to address this question:
1. Sharing forecasts from a subsample of panelists who expect fast AI progress by 2040, for comparison
2. Adding regularly updated LLM forecasts to LEAP findings
3. Highlighting forecasts from the most accurate LEAP participants as soon as we have data to make this judgment rigorously

We’ve run the most comprehensive series of studies on expert AI forecasts over the last four years. Today, we’re sharing an interim update on our findings about the accuracy of these forecasts.
Our major findings are:
1. Experts, including top economists, computer scientists, and biologists, have dramatically underestimated AI capabilities progress each year. Superforecasters have underestimated progress to an even greater extent.
2. Experts have a more mixed forecasting track record on AI diffusion-related measures, with some major underestimates (forecasting AI revenue) and other forecasts on track to be accurate (the share of electricity used for AI).
3. Some notable cases of overestimating AI progress: how much mid-2025 AI models could help amateurs do biorisk-relevant laboratory tasks; the speed of rollout of self-driving cars.
4. It is too soon to say how forecasters have performed at predicting macro-scale impact on outcomes such as GDP growth, major AI harms, and averted deaths from disease.
More 🧵

Here are two examples of LEAP charts that feature LLM forecasts and a "fast AI progress" sample.
Details of how we selected the "fast AI progress" sample and how we ran the LLM forecasts for these example charts are in the full post linked below.
We've also recruited a new group of LEAP experts from people who work on mitigating catastrophic risk from AI. The forecasts from this group are not included in the charts below as they have only forecast a small number of LEAP questions, but this subsample will be referred to in future LEAP reports.
We'll announce more on this catastrophic risk subsample very soon.


For more information on these changes to LEAP, see the full post:
On Substack: forecastingresearch.substack…
On FRI’s website: forecastingresearch.org/rese…