
Postdoc in Uncertainty Quantification (Machine Learning)
Leuven
Joined June 2022
- Tweets50
- Following199
- Followers66
- Likes207
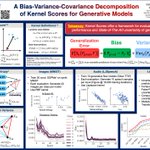

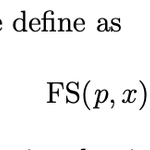


28 years ago the bias-variance-covariance decomposition of the mean squared error was introduced.
This week at @icmlconf, @BuettnerFlo and I will show that it also holds for kernel-based loss functions, which we use for image, audio, and language generation experiments...

The decomposition represents a framework for understanding generative models' generalization performance and uncertainty. Specifically, we outperform other baselines of uncertainty in predicting the answer correctness of LLMs
arxiv.org/abs/2310.05833
Sebastian G. Gruber retweeted

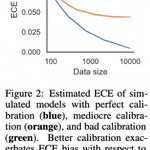
Today at #AISTATS24 @SebGGruber, @dr_alex_tiulpin and I are presenting our work on “Consistent and Asymptotically Unbiased Estimation of Proper Calibration Errors”. You can find us from 15:00 to 17:00 @ MR1 #31 ☺️
Paper: proceedings.mlr.press/v238/p…
Code: github.com/tpopordanoska/pro…

Happy to announce our new paper
“Uncertainty Estimates of Predictions via a General Bias-Variance Decomposition”
which me and @BuettnerFlo present at #AISTATS 2023 in Valencia! 😊
arxiv.org/abs/2210.12256
It all started over two years ago during my master's thesis...
🧵(1/7)

Since the generating function in classification is the LogSumExp function, the Bregman Information of neural network classifier samples requires only a single line of code in PyTorch.
This way, we may even show it in introductory courses.
🧵(6/7)

Of course, we also offer other contributions in our paper.
We use the Bregman Information to
- construct 95% confidence regions
- proof when larger ensembles perform better
- identify performance deteriorating Out-of-Domain test instances
Code:
github.com/MLO-lab/Uncertain…
🧵(7/7)

Showcasing the positive impact of ensemble predictions for skin lesion classification under real-world settings at #RheinMainCancerRetreat

My and @BuettnerFlo 's NeurIPS’22 paper is camera ready 🎉
“Better Uncertainty Calibration via Proper Scores for Classification and Beyond”
arxiv.org/abs/2203.07835
🧵(1/n)
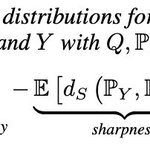
We also generalize the sharpness-calibration decomposition of categorical proper scores to the functional case. Thus, we can derive “proper calibration errors” from proper scores, which can be used for a large variety of predictive settings beyond classification.
🧵(6/7)

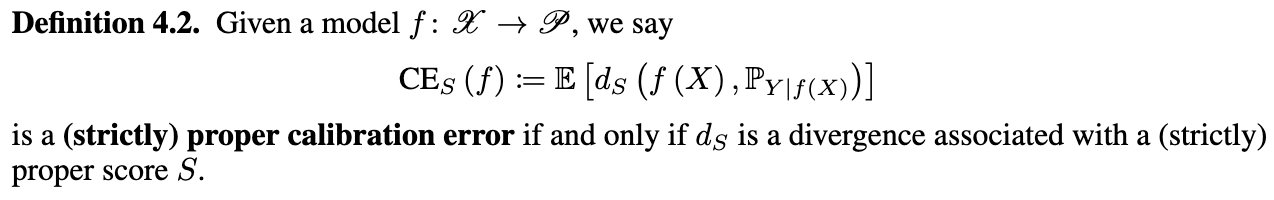
Our benchmarking procedure is available at github.com/MLO-lab/better_un…
🧵(7/7)

Sebastian G. Gruber retweeted

.@DKTK_-Forscher Florian Büttner @BuettnerFlo erhält @ERC_Research Consolidator Grant für die Entwicklung von #KI-Modellen, die Ärzte zuverlässig dabei unterstützen sollen, #Krebs zu diagnostizieren oder Therapieempfehlungen abzugeben 👏👏
@FCI_health
➡️ bit.ly/3DJxzzZ
