





BREAKING NEWS🚨: RUBIN NVL72 HITS 862 tok/s/user on GLM5.3 744B on agentic workloads!
In less than 8 days, NVIDIA has increased interactivity on Rubin by close to 2x through low-latency specialized kernels.

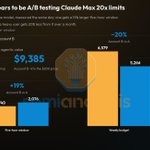
🚨🚨ALERT: ANTHROPIC IS A/B TESTING USAGE LIMITS
Many users on X are reporting LOWER usage limits right now. THEY ARE NOT WRONG. We detected an A/B test going on that DECREASES your monthly API-value by ~20% while INCREASING your 5h usage limits by ~20%. This only affects SOME accounts. (1/2)🧵

See how we track subscription usage limits over time (2/2) newsletter.semianalysis.com/…

We track the shipments of nearly every AI accelerator in the world. By company, by SKU, by quarter.
Myron Xie on the SemiAnalysis Accelerator & HBM Model: NVIDIA, AMD, TPU, Trainium and the rest, traced back to logic wafers, CoWoS and HBM, and the unit and ASP forecasts clients use most.
Learn more about the Accelerator & HBM Model and talk to our team: semianalysis.com/accelerator…

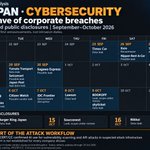
Japan’s wave of corporate breaches is the latest sign that AI is changing how hacking works.
Since Sept 25, 18 Japanese companies have disclosed breaches, including Tokyo Metro, Japan Post, Lawson, Nikkei, Yamato and Sagawa. Attackers got about 6.6M Times Car accounts, some with driver’s license images. Burger King Japan says 11.18M app member records were affected, and Sourcenext says up to 22.5M records may be out.
Last week, JPCERT/CC, the country’s national computer emergency response team, posted its findings from the investigations into these breaches. The attackers used AI to scan for known vulnerabilities and to attack companies’ APIs. Often they did this by pulling apart a company’s Android app to find the endpoints and any keys left in the code. It is also no surprise that Japanese companies are particularly vulnerable. Japan is still catching up on basic digitization, with many offices still using fax machines to this day!
Now even the PM is getting involved, urging anyone running a PHP website to patch two critical vulnerabilities immediately, or temporarily take the site offline if they can't.
xitter.cf/takaichi_sanae/status/…


皆様に、今夜に対応して頂きたい大至急のお願いです。
多くのウェブサイトで使用されているPHPに関し、PHPのセキュリティチームが、重大な2件の脆弱性に関する注意喚起を行っています。
公開しているウェブサイトでPHPを使用しているか確認し、今夜、10月21日午後11時(日本時間)に公開される修正パッチについて、可及的速やかに適用できるよう準備をお願いします。
修正パッチを速やかに適用することが困難な場合は、例えばウェブサイト等を一時的に停止させることも、リスクを低減させるための有効策の一つと考えられます。
国家サイバー統括室のXアカウントでも関係する情報を発信していますので、そちらも参考にして下さい。
国家サイバー統括室(注意・警戒情報)(@cyber_forecast) / X
SemiAnalysis retweeted

Today we launch SGLang-TorchTPU, built with @Google TPU team and Meta @PyTorch team.
We’re excited to see it powering production inference at Meta!
SGLang-TorchTPU is a TPU plugin for SGLang that brings:
- Top open models on TPU: Muse Spark Open, GLM-5.3 Flash, Kimi K3, Ling 3.1 Flash, MiniMax H3
- SGLang’s production features for large agentic workloads
- Custom MegaKernel: Muse Spark Open hits 770 tok/s decode at bs=1 on InferenceX 8K/1K
SGLang-TorchTPU is available now: github.com/sgl-project/sglan…


Big day for the @PyTorch ecosystem at #PyTorchConf2026 🚀
We’re officially open-sourcing TorchTPU—enabling native, hardware-accelerated PyTorch execution across Cloud TPUs and custom infrastructure.
Here’s everything we launched to supercharge your training & inference workloads 🧵👇
goo.gle/4Bl0zdG

SemiAnalysis retweeted

vLLM 🤝 TPU
🚀 Native PyTorch serving on TPUs is here! Built with @Google and @inferact, vLLM-TorchTPU brings familiar PyTorch tools to TPU inference, with prefix caching, speculative decoding, and disaggregated serving.
🛠️ Excited to keep building with the community!

Native PyTorch on TPUs is here—and TorchTPU is officially open source.
Train and serve models using the tools you already know: @vllm_project, @sgl_project, @_llm_d_, TorchTitan, @huggingface, and @raydistributed.
Learn more from #PyTorchConf2026 → goo.gle/4hWxEVH

Three teams in one month have pushed LLM decode forward with megakernels: Inferact on Google TPUs, AMD with TileRT and FlyDSL, and now NVIDIA on GB300, now live on InferenceX.
We're excited to see these gains and dig into the engineering behind faster inference.
Megakernels combine work that normally runs in separate programs. Here's why that matters and how each team's approach works. (1/8)🧵

NVIDIA's GB300 trace shows one K3 layer block going from 23 kernels to 13, and from 130 to 69 microseconds.
Combining work of overlapping communication with other tasks and fetching weights early all help shorten the step.
Kimi-K3 CuTe DSL decode: github.com/vllm-project/vllm…
image source: Inferact blog (7/8)

As agentic workloads grow, high interactivity cases, especially how quickly a model generates tokens for each user, is becoming increasingly valuable.
We're also seeing AI coding tools accelerate kernel development, where correctness can be tested and performance can be measured. Faster iteration gives talented engineers more room to explore and refine new ideas.
We're excited to see what the next wave of kernel innovation brings. (8/8)
Huawei Ascend 950PR Deep dive & µbenchmarks,
DSv4.1 Flash Analysis, DeepSeek support for Ascend,
AICPU, Tilelang Ascend
newsletter.semianalysis.com/…

💭WHY IS DEEPINFER NOT ON INFERENCEX?
DeepSeek dropped DeepInfer a few days ago, but the code is missing key components that is crucial for inference serving, and building them adds too much assumptions. (1/5)🧵

And vLLM on InferenceX performs extremely well. Explore our results, DSv4.1 serving results, configs, logs, and profit estimator on InferenceX.com (4/5)

