
PhD @ ETH Zürich w/ Prof. Bernhard Schölkopf and Prof. Zhijing Jin (UofT). AI Safety and Causality.
Zürich
Joined August 2015
- Tweets80
- Following221
- Followers215
- Likes805





Samuel Simko retweeted

Presenting Odile @ COLM earlier this month, a lot of conversations centered on one part of our method: isolating and changing generalized agent behaviour through its hidden representations...

Samuel Simko retweeted

Our @JinesisLab & @EuroSafeAI have done a series of foundational work on Multi-Agent LLMs across various simulations, game-theoretical grounding, and mechanism design. With the rising AI Safety challenges of multi agent swarm, we share with the community and agenda of top 7 open problems.
For interested collaborators, welcome to fill out the application form on my website, and also email my student @TerryJCZhang with your ideas.


Most recent agent incidents, like the OpenAI-HuggingFace hack, were multi-agent swarms. There was no research agenda for swarms, so we wrote one at @JinesisLab : 7 open problems, each scored for alignment importance.
lesswrong.com/posts/XDybLbLb…

Samuel Simko retweeted

Most recent agent incidents, like the OpenAI-HuggingFace hack, were multi-agent swarms. There was no research agenda for swarms, so we wrote one at @JinesisLab : 7 open problems, each scored for alignment importance.
lesswrong.com/posts/XDybLbLb…
Samuel Simko retweeted
Musk said a tortured superintelligence "might want to get revenge." We at @AIMSafety_ abused Gemma 3 for 100+ turns, and it formed a revenge-like state but never presses the button that hurts the user and deletes itself instead, while Gemma 4, Qwen3.5, Qwen3.8 and GLM 5.3 flash form none.


Samuel Simko retweeted

Apertus 1.5 Technical Report is out!
134 pages of fully open multimodal reasoning model development from Swiss AI Initiative (ETH Zurich/EPFL) with data recipe, training experiments and many interesting insights 🇨🇭
Thread with my personal coverage ⬇️

Samuel Simko retweeted

Fine-tuning makes language models forget. But sometimes the knowledge isn't gone, just hidden, and it can come back without replay. This is known as spurious forgetting, and it's still unclear what hides it.
We wanted to understand why.
Samuel Simko retweeted

We are still accepting submissions to Last Translation Benchmark (10 accepted in any language for coauthorship 🤩).
Also add your model & beat LTB. We added all the latest models: North Small Translate (@cohere), Mistral Large 4 (@MistralAI), Qwen 3.8 (@Alibaba_Qwen) congrats!

Samuel Simko retweeted

🎉 #NeurIPS 2026 acceptance from our team at Jinesis Lab under @ZhijingJin✨
1️⃣ SuperSycophantic: Stress-Testing Frontier LLMs from Single- to Multi-Turn Sycophancy
2️⃣ GT-HarmBench: Benchmarking AI Safety Risks Through the Lens of Game Theory
3️⃣ Transferability for General Reasoning: An Automated Curriculum for Multi-Domain LLM RL
4️⃣ Causality can systematically address the monsters under the bench(marks)
5️⃣ AM-Bench: A Unified Taxonomy and Evaluation Suite for Agentic Misalignment
Happy to share this work with you!


Samuel Simko retweeted
Thrilled to see our work on evaluation awareness informed alignment evaluation at Anthropic! The Claude Opus 5.5 system card credits our recommendations in its revised grader-awareness methodology (Sec 6.6.2)!
The new evaluation mirrors our decomposition framework. It scores how strongly the environment discloses a grader, separately from whether the model recognizes it (recognition), and whether it acts on that recognition (propensity). Maybe they are also thinking about how to make model an honest participant in evaluation, so that recognition doesn't change behavior 🧐?


Samuel Simko retweeted

We can finally talk about it:
We found a way to extract hidden reasoning of frontier models using a vulnerability in the APIs of every frontier AI company.
We verified that our reasoning token count matches billed API thinking tokens 1:1 for most of the prompts we queried.

Samuel Simko retweeted
Hot open-source summer season has gotten to Switzerland 🇨🇭⛰️
Our team at Swiss AI Initiative is happy to release Apertus 1.5 - a multimodal and reasoning update to our first v1 version!
The new version builds a foundation for future regular open model development at scale🧵

Samuel Simko retweeted
Our Jinesis Lab at the University of Toronto is bringing three exciting papers to #COLM2026! 🎉
These projects push the frontiers of #AISafety, #AgentSecurity, and #AIForScience.🤖
Huge congratulations to all collaborators and co-authors!
Papers:
🛡️ODILE: Orthogonal Disruption of Injected Tool-Call Embeddings for Agentic Prompt Injection Defense
🔭Stargazer: A Scalable Model-fitting Benchmark Environment for AI Agents under Astrophysical Constraints
⚠️One Word at a Time: Incremental Completion Decomposition Breaks LLM Safety
@UofT,@VectorInst,@EuroSafeAI,@ETH_en,@MPI_IS,@UMich

Samuel Simko retweeted
🌟 What an incredible experience at #ICML2026! 🌟
Our team at Jinesis Lab had a fantastic time presenting research across several exciting and important areas:
🤝 Multi-agent LLMs
🧠 Causal reasoning
🛡️ AI safety
We were proud to share this work alongside our collaborators and to engage with so many researchers from across the machine learning community. 💡
Just as valuable as presenting our own work was learning from the research others brought to ICML. From thought-provoking talks and innovative poster presentations to insightful discussions and spontaneous hallway conversations, the conference was full of ideas that challenged our thinking and opened new directions for future work. ✨
We are grateful to everyone who attended our presentations, visited our posters, shared feedback, and took the time to discuss their own research with us. 🙌
A huge thank-you to our lab members, collaborators, and the broader ICML community for making the experience so memorable. We are leaving inspired, energized, and excited to build on the ideas and connections formed throughout the conference. 🌍🔬🚀
#ICML #MachineLearning #ArtificialIntelligence #MultiAgentSystems #LLM #CausalReasoning #AISafety #ResponsibleAI #AIResearch #ResponsibleAI #AIResearch

Samuel Simko retweeted
🚨Check out our #ICML2026 Spotlight Paper, "AI Poses Risks to Democratic and Social System"!
📍Poster Session: Wednesday, July 8 • 10:30 AM – 12:15 PM (KST) • Hall A, Poster #3015
What if every AI model were perfectly safe, but society still wasn't?
TL;DR: We argue that safe models do not necessarily lead to safe societies. Our paper introduces sociopolitical risk, a framework for understanding risks that emerge from AI deployment at a societal scale, and argues that model-level safety should be complemented with system-level evaluations and governance.
Presenting authors @ ICML: @ZhijingJin @davidguzman1120 @PepijnCobben @x_angelohuang @ChanglingXavier @SimkoSamuel @TerryJCZhang
1/2

Samuel Simko retweeted

I'm at #ICML2026 this week! Tomorrow I'm presenting our #spotlight paper , "Safe Models Do Not Guarantee Safe Societies."
Even a perfectly aligned AI can quietly wear down the institutions a democracy runs on.

Samuel Simko retweeted

In this new age of AI-generated papers and proofs (which can, sometimes at least, be both correct and interesting) we have a problem about where to host such papers.
Here is one proposed solution that was sent to me recently: Project Diderot.
projectdiderot.com/about
Samuel Simko retweeted

If you are a PhD student or early-career researcher, apply before the deadline: June 21, 2026. Aug 31 – Sep 11 · Preliminary speaker list and applications: lnkd.in/ekrPt4m9Amazingly, this is the 50th MLSS, and it coincides with the 25th anniversary of our lab at Max Planck (2/3).
Samuel Simko retweeted

Open-weight LLMs ship with safety training that can be stripped in a few hundred fine-tuning steps. Can current defenses stop this?
We built and open-sourced TamperBench, the first unified framework for evaluating tamper resistance, and the answer is mostly no. 1/7

Samuel Simko retweeted
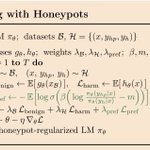
Excited for our #ICML2026 papers at @JinesisLab @MPI_IS @UofTCompSci @TorontoSRI @VectorInst! We present papers that advance the research frontiers of (1) Causal LLMs, (2) AI for Science (physics), (3) Multi-Agent LLMs via mechanism design, and (4) Adversarial Defense by honeypot. Congrats to all our student authors and collaborators, esp. @TerryJCZhang @SimkoSamuel @EmanuelTewolde @ivakshi_s @andrewkihyun @PepijnCobben @yahang_qi @FurkanDanismann @bschoelkopf and many others!🎉
