

AI Engineer | Working with Agents I build AI explainers with code deep dives on YouTube DM for Collabs
Joined November 2020
- Tweets11.3K
- Following204
- Followers3.3K
- Likes13.4K







Thariq left Anthropic
He built Claude Code in public and made the whole thing feel human. that's why this one hits harder than a normal departure post. go build something great.

I’ve left Anthropic after more than a year of working on Claude Code and seeing it scale larger than I ever imagined.
I have really loved working at Ant and believe deeply in the mission, and most of all, the idea of a race to the top.
The idea that if we work hard and responsibly, we can raise the bar and inspire others to great outcomes. And if we all push each other to be better, things can be radically good. I will carry the spirit of this with me forever.
My colleagues at Anthropic are the most talented, thoughtful, competent, and earnest people I have ever met. I am glad they are at the wheel and trust them deeply.
To the community on X, thank you for everything. You’ve made this the most fun (and sometimes stressful) job I’ve ever had.
For me, it is time for a bit of a break before diving into something new.
If you want more excellent Claude Code content, you should follow @addyosmani , @lydiahallie, @_catwu, @ClaudeDevs and of course @bcherny who started it all.
Top 10 cheapest models right now (per 1M tokens):
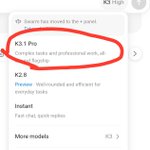
Kimi K3.1 Pro sits at no. 10
1️⃣ Claude Haiku 5.5 : $0.10 / $0.50
2️⃣ GPT-6 Luna : $0.10 / $0.50
3️⃣ MiniMax M3.1 Flash : $0.15 / $0.60
4️⃣ DeepSeek V4.1 Flash : $0.30 / $1.20
5️⃣ GLM-5.3 : $1.40 / $4.40
6️⃣ Muse Spark / Qwen : ~$1.25–$2 / $4–$6
7️⃣ Gemini 3.8 Flash : $0.75 / $3.75
8️⃣ Grok 4.6 / 4.7 : $2 / $6
9️⃣ Claude Sonnet 5.5 : $2 / $10
🔟 GPT-6.1 Sol / Kimi K3.1 Pro : $2 / $10
Budget kings Haiku, Luna, MiniMax and DeepSeek.
Fable 5.5 partner access started in mid-October.
Azure and LiteLLM listings appeared then vanished.
GitHub commits carried the name.
Anthropic is sitting on the next big one.

Kimi K3.1 Pro launch night and the quota is already a disaster.
People are burning their entire 5-hour window in under 10 minutes.
Some in less than 2.
Thinking is forced on. Highspeed doubles the burn rate. One long prompt and you’re done.
Frontier benchmarks mean nothing when the model locks you out before it can finish a single real task.
This is the most aggressive usage limit I’ve seen from any major lab this year.

Kimi K3.1 Pro just landed and the numbers are wild:
• 65.7% on Terminal-Bench 4.0 only 0.7% behind Opus 5.5, ahead of GPT-6 Astra
• Massive jump in long-horizon coding and 3D/CAD work
• Hallucinations cut by 65%
• Open weights coming Nov 4
• Sitting in the high-performance / low-cost zone

Kimi K3.1 Pro Crushes Claude Fable 5.1, GPT-6 Astra, and even approaches Opus 5.5
At a fraction of the cost
While others are burning $15–20+ per task, Kimi is sitting at the top-left with elite performance and low spend.


Gemini 4 Carbon is testing in arena
Built a 100% procedural 3D pelican riding a vintage beach cruiser in Three.js
I have never burned through Opus 5.5 this fast.
same tasks, same effort, and my session bar is gone in half the time it used to take.
is the token multiplier different or am I losing my mind?
anyone else watching Opus 5.5 torch their limit today?

Microsoft engineers just leaked OpenAI's 'gpt-6.1-terra' by accident.
the official .NET EF Core repo has gpt-6.1-terra sitting in 18 evaluation configs.
17 of them were quietly upgraded from gpt-5.6-terra.


Codex Users pay attention:
Reset landing Tomorrow
🇺🇸 San Francisco — 10:00 AM
🇺🇸 New York — 1:00 PM
🇬🇧 London — 6:00 PM
🇮🇳 Mumbai / Delhi — 10:30 PM
🇸🇬 Singapore — 1:00 AM (+1)
🇯🇵 Tokyo — 2:00 AM (+1)
🇦🇺 Sydney — 4:00 AM (+1)
🇩🇪 Berlin — 7:00 PM
🇧🇷 São Paulo — 2:00 PM
🇰🇷 Seoul — 2:00 AM (+1)
Mark your clocks.

Claude Opus 5.5 started burning your quota in 30 minutes. now Codex is doing it in 15.
a single session on GPT-6 Astra at MEDIUM effort just drained the usage bar from 100% to 0% in ~15 minutes.
same model at MAX effort used to last 50+ minutes.
that's not a usage bar anymore, that's a countdown.
both labs quietly tightening token multipliers this week, or are the prompt caches just breaking?


Did Claude just rob me of an entire day of my weekly limit???
My reset has been Friday for months. today it says Saturday.
Nobody announced anything, my plan didn't change, it just silently moved up a day.
And i'm not alone. At 16:00 UTC the banked free reset expired and right then people started flooding in with the same story: reset day jumped a day early. Did you check yours?
