
Med-Peds Biochemical Geneticist @VUMChealth w/ interest in rare/undiagnosed disease, husband, proud Mexican-American, football fan, he/him, views my own
Nashville, TN
Joined September 2019
- Tweets412
- Following283
- Followers416
- Likes1.1K




Pinned Tweet
Come listen to @DrCaroMontano and I talk with @DrJNurse from @JIMD_Editors about how @UDNconnect and @NIH UDP work to find answers to the most challenging cases and further our scientific understanding of disease #MedTwitter
onlinelibrary.wiley.com/page…


I am old enough to remember 9/11 but was too young to process all of the details and significance.
The way @25YearsAgoLive is retelling the story is making helping me remember the day and teaching me new things in such a unique way. Worth following along if you aren’t already.

Thomas Cassini, M.D. retweeted

Microsoft claims their new AI framework diagnoses 4x better than doctors.
I'm a medical doctor and I actually read the paper. Here's my perspective on why this is both impressive AND misleading ... 🧵

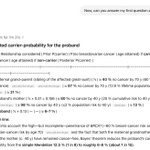
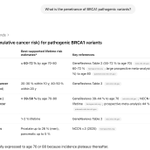
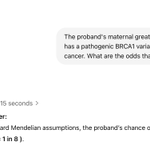
ChatGPT tends to struggle with issues related to penetrance if not directed to consider this.
Here is an example. Despite using a "reasoning" model, this just does a simple mathematical calculation and does not use all the information provided.


Thomas Cassini, M.D. retweeted

I find the story of AI and radiology fascinating. Of course, Hinton's prediction was wrong* and tech advances don't automatically and straightforwardly cause job replacement — that's not the interesting part.
Radiology has embraced AI enthusiastically, and the labor force is growing nevertheless. The augmentation-not-automation effect of AI is despite the fact that AFAICT there is no identified "task" at which human radiologists beat AI. So maybe the "jobs are bundles of tasks" model in labor economics is incomplete. Paraphrasing something @MelMitchell1 pointed out to me, if you define jobs in terms of tasks maybe you're actually defining away the most nuanced and hardest-to-automate aspects of jobs, which are at the boundaries between tasks.
Can you break up your own job into a set of well-defined tasks such that if each of them is automated, your job as a whole can be automated? I suspect most people will say no. But when we think about *other people's jobs* that we don't understand as well as our own, the task model seems plausible because we don't appreciate all the nuances.
If this is correct, it is irrelevant how good AI gets at task-based capability benchmarks. If you need to specify things precisely enough to be amenable to benchmarking, you will necessarily miss the fact that the lack of precise specification is often what makes jobs messy and complex in the first place. So benchmarks can tell us very little about automation vs augmentation.
* Hinton insists that he was directionally correct but merely wrong in terms of timing. This is a classic motte-and-bailey retreat of forecasters who get it wrong. It has the benefit of being unfalsifiable! It's always possible to claim that we simply haven't waited long enough for the claimed prediction to come true.

ALT screenshot of https://www.nytimes.com/2025/05/14/technology/ai-jobs-radiologists-mayo-clinic.html
This is interesting because if you substitute “medicine” for “software”/“tech” and take “you” to be the plural incorporating yourself, the patient, and the healthcare team, the second paragraph actually well describes practicing medicine

I'm curating genes to add to an inborn errors of immunity panel. o3 did a pretty thoughtful job of explaining why to add some on the 2024 IUI list (not sure yet about FOXI3)
I need to look at the rest of the list still to see if any were missed that may have sufficient evidence

Unexplained Progressive Respiratory Insufficiency and Weakness Diagnosed as Late-Onset Pompe Disease Through Biochemical and Molecular Genetic Testing
journals.sagepub.com/doi/10.…

I'm grateful for the opportunity to be a part of this work from my radiology colleagues here @VUMChealth
rdcu.be/epVw8
Interesting article. The "three performance regimes" subjectively correlate with my practical experience:
1. low-complexity: standard models outperform LRMs
2. medium-complexity: LRMs demonstrate advantage
3. high-complexity: both experience collapse
machinelearning.apple.com/re…
Saw something interesting from ChatGPT today. Asked it to predict the protein sequence for this variant: PARD6B NM_032521.3:c.761dup (p.Asn254LysfsTer17)
It got it right (top reading from on the UCSC screenshot), and the way it did it was pretty cool!


ChatGPT o3 + Gemini 2.5 Pro are great for gathering the information needed to classify a genetic variant, but it seems like they tend to struggle applying classification criteria.
There is some subjectivity here, but even when guided to ACMG criteria they don't apply accurately


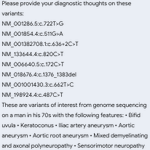
I used to try to just put genetic variants into GPTs and see if it could provide diagnostic insight.
I found something interesting when I just put in variants and HPO terms like this prompt

I am guessing this is because the HPO terms are in a common format (words) and the symbols used in transcript variants, which are much more commonly seen in other contexts than together in this format (i.e. ">" usually means greater than, not ref to alt)