
research @openai views my own
San Francisco, CA
Joined February 2020
- Tweets47
- Following211
- Followers153
- Likes302
Theophile Sautory retweeted

Enjoy a full reset of your usage limits for ChatGPT Work and Codex. Propagating in the next hour.
@_rajanagarwal just joined to work on model research and push on coding capabilities. You can thank him for pressing the button today.

codex takes the thrash at machine speed so i can finally slow down enough to dwell. perhaps hartmut rosa would call this resonance.
turns out acceleration was the path to presence all along
1
4
290

Theophile Sautory retweeted

@OpenAI's frontier models sit at the core of our approach. recently we sat down with them to document & share some of our learnings: openai.com/index/tolan/

congrats @theodormarcu and team!!

GPT-5.2 is now live in Windsurf!
Available for 0x credits for a limited time (paid and trial users).
The version bump undersells the jump in intelligence:
- Biggest leap for GPT models in agentic coding since GPT-5
- SOTA coding model at its price point
- Default in Windsurf

1
6
482
Theophile Sautory retweeted
GPT-5.2 is now live in Windsurf!
Available for 0x credits for a limited time (paid and trial users).
The version bump undersells the jump in intelligence:
- Biggest leap for GPT models in agentic coding since GPT-5
- SOTA coding model at its price point
- Default in Windsurf
Theophile Sautory retweeted

GPT-5.1-Codex-Max is our best agentic coding model, and is now available in our API.
It's a great model, but it’s also easier than ever to integrate.
I’ve spent the last two weeks experimenting with our top customers - here's how to get the most out of it 🧵
Theophile Sautory retweeted

We just shipped GPT-5.1-Codex-Max to API!
Codex agents everywhere are now faster & smarter, whether you're using Codex in the CLI via API key, or in other tools like @cursor_ai and @code.
More about how Cursor updated their harness to make the most of it cursor.com/blog/codex-model-…

Theophile Sautory retweeted

We are thrilled to partner with @OpenAI on this launch. Scholar Agent is powered by GPT-5.
@sama, @gdb, @kevinweil and team have built an amazing product that powers the future AI-enabled scientific exploration and discovery.
More on our partnership⤵️
openai.com/index/consensus/

Theophile Sautory retweeted

getting started with evals doesn't require too much. the pattern that we've seen work for small teams looks a lot like test‑driven development applied to AI engineering:
1/ anchor evals in user stories, not in abstract benchmarks: sit down with your product/design counterpart and list out the concrete things your model needs to do for users. "answer insurance claim questions accurately", "generate SQL queries from natural language". for each, write 10–20 representative inputs and the desired outputs/behaviors. this is your first eval file.
2/ automate from day one, even if it's brittle. resist the temptation to "just eyeball it". well, ok, vibes doesn't scale for too long. wrap your evals in code. you can write a simple pytest that loops over your examples, calls the model, and asserts that certain substrings appear. it's crude, but it's a start.
3/ use the model to bootstrap harder eval data. manually writing hundreds of edge cases is expensive. you can use reasoning models (o3) to generate synthetic variations ("give me 50 claim questions involving fire damage") and then hand‑filter. this speeds up coverage without sacrificing relevance.
4/ don't chase leaderboards; iterate on what fails. when something fails in production, don't just fix the prompt – add the failing case to your eval set. over time your suite will grow to reflect your real failure modes. periodically slice your evals (by input length, by locale, etc.) to see if you're regressing on particular segments.
5/ evolve your metrics as your product matures. as you scale, you'll want more nuanced scoring (semantic similarity, human ratings, cost/latency tracking). build hooks in your eval harness to log these and trend them over time. instrument your UI to collect implicit feedback (did the user click "thumbs up"?) and feed that back into your offline evals.
6/ make evals visible. put a simple dashboard in front of the team and stakeholders showing eval pass rates, cost, latency. use it in stand‑ups. this creates accountability and helps non‑ML folks participate in the trade‑off discussions.
finally, treat evals as a core engineering artifact. assign ownership, review them in code review, celebrate when you add a new tricky case. the discipline will pay compounding dividends as you scale.
Theophile Sautory retweeted
new guide on “exploring model graders for reinforcement fine-tuning” on openai’s platform. h/t @TSautory
final result was a high-signal, domain-sensitive grader that guided the model toward better explanations.
cookbook.openai.com/examples…

Theophile Sautory retweeted

I will be hosting this week's @OpenAI build hour this Thurs!
This one will be on Image Gen! I will talk about:
- cool use cases you can build with it
- how you can use it together with other hosted tools
- best practices
- demo you can use!
It will be technical. Builders welcome!

Theophile Sautory retweeted

Ambience's RFT-tuned model boosted ICD-10 coding accuracy 27% over expert clinicians—and it's now spotlighted in @OpenAIDevs' Reinforcement Fine-Tuning use case guide. Excited to see what the community builds with this powerful new customization technique: platform.openai.com/docs/gui…
Theophile Sautory retweeted
I've been loving GPT-4.1, and it's now my daily driver. We've spent hundreds of hours experimenting to get it performing at its best, and I wanted to share some key things we learned to help you get the most out of these models from day 1.
Agentic workflows
- This is your new starting point. Just add tools and prompt to make it plan, execute, and verify iteratively until producing a correct answer. Only add multi-agent frameworks once you've squeezed as much as you can here.
- Coding agents will be particularly good with this model, especially when paired with our recommended diff output format and diff apply tool.
Chain of thought
- Prompting for chain of thought can help to break down the problem and improve overall intelligence.
- Start with a simple instruction at the end of your prompt, as the model is already quite good at thinking through problems. Then, observe correct and incorrect eval samples to direct further changes to the thinking instructions.
- Often, asking the model to spend more time understanding user intent and gathering context can help.
Long context
- The full context window (now 1M token in put) is much more performant/usable than before. As task complexity increases, performance might still improve by decreasing context size.
- Check the guide for suggested delimiters.
Improving instruction following
- Performance is much better with this model, and you can add significant detail for what to do/not do in different circumstances.
- Many model performance issues actually come from inconsistent, conflicting, or underspecified instructions (including conflicting information in examples as well).
- Be careful with telling the model to "always" do something, you might not actually want that and it can induce hallucinations, for example if it needs to call a tool with insufficient context.
- I find it's helpful to ask ChatGPT Canvas or Cursor for help iterating on prompts cohesively (e.g. asking for conflicting instructions, edge cases, or adding an instruction and updating examples at the same time)
Prompt structure
- tl;dr check out the recommended template (attached)
- Context at or near the bottom seems to be best (and repeating instructions both above and below very long context can actually help too).
- Markdown and XML both work great

Theophile Sautory retweeted

Today we’re launching Operator —our first AI agent that can browse the web and complete tasks for you.
Available to all Pro users in the US starting today. We’re partnering with top companies to maximize impact, and we’ve built robust safeguards to keep you safe.


Theophile Sautory retweeted
Nick Romeo's new book starts with the story of @coreeconteam. When I joined CoreEcon in 2016, we believed in “Better Economics for a Better World” & aimed to reform the Economics curriculum. Today, our textbook is used in ~400 colleges, and constantly integrates latest research🎊

Capitalism causes environmental destruction and massive income inequality, impoverishing most at the expense of enriching the few. But there is an alternative. Check out Nick Romeo's new book THE ALTERNATIVE, in bookstores today.
hachettebookgroup.com/titles…

Theophile Sautory retweeted

Fresh off the press by @jacobbamberger @SPLTS2
"A topological characterisation of Weisfeiler-Leman equivalence classes"
Introduces a dataset of non-isomorphic graphs that cannot be distinguished by message-passing.
arxiv.org/abs/2206.11876

Theophile Sautory retweeted

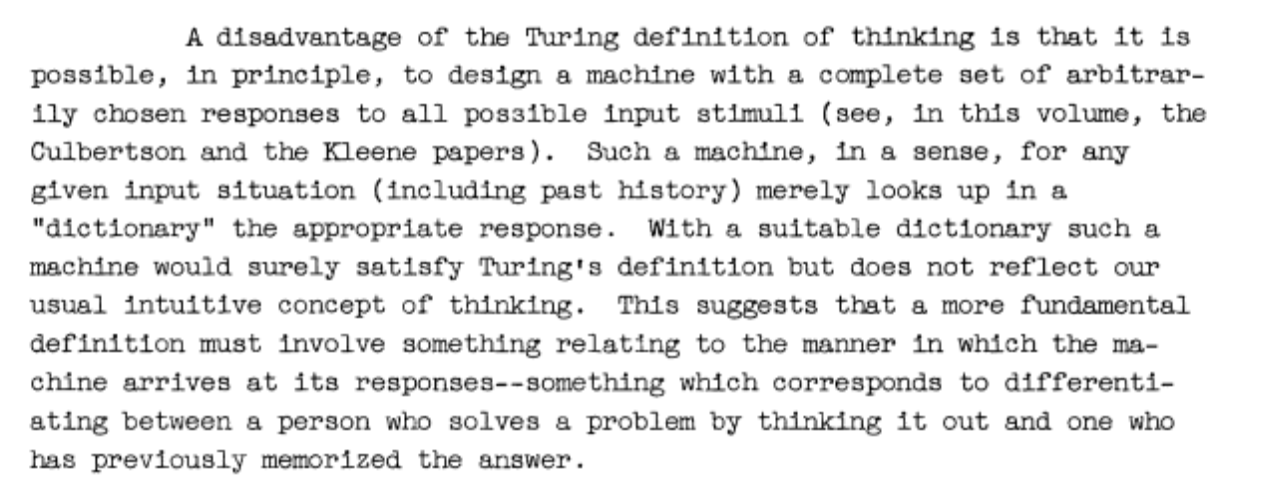
A wonderful find! From 1956 - I looked it up. And here's the next paragraph. Of course, GPT-3 doesn't exactly conform to this description. Still ...


Theophile Sautory retweeted
An edited transcript of my talk at Montreal AI Debate 2 is now posted here ucla.in/3amZFmI

"AI Debate 2: Night of a thousand AI scholars"
By @TiernanRayTech, @ZDNet: zdnet.com/article/ai-debate4…
#MontrealAI #AIDebate #AIDebate2
