

Principal AI Engineer. I catch agentic AI failures before they cost millions, not after. Evals + agentic systems for regulated enterprise. https://xitter.cf/t.co/wNKtykyGgV
New York, NY
Joined March 2009
- Tweets112K
- Following4.4K
- Followers4.7K
- Likes19.5K






My good sis @KanikaTolver just confirmed what I’ve been telling some people over the last couple of years.

Yes. I’d want a held-out task set with a single agent, same tools, as the baseline. Compare verified completion, then net out latency, cost and handoff failures, against a threshold set before the run. No clear lift, no extra agent. Isolation or security needs are the exception.
Mike Legemah retweeted

Your review is judged against a rubric.
How many lines of it can you back with evidence?
LogPact's gap analysis shows which competencies have wins logged and which are empty, while there's still time to fix it.
Pro, 14-day trial: logpact.com/?utm_source=x&ut…

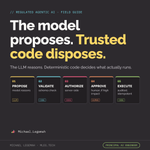
Prove a single-agent workflow before you build a multi-agent one.
Every extra agent is another handoff to secure and another failure mode to audit.
If you need several: delegation never grants permissions, and protocol compliance is not trust.

Why do non-US recruiters always think it’s a good idea to call you before they email you a job description? Do they think people are just sitting around doing nothing?
Mike Legemah retweeted
Unpopular opinion: the brag doc is bad advice.
Blank docs need you to remember them. You don't.
Smaller works: 1 win, 1 sentence, 60 sec, every day.
30 days → 30 dated wins. Free challenge starts Oct 26: logpact.com/challenge?utm_so…

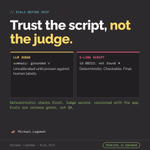
LLM judge: "summary is grounded." 5-line script: "the claim ID it cites doesn't exist."
Believe the script.
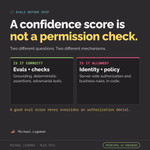
Deterministic checks first. Judge for the rest, validated against human labels. Evals are release gates, not QA.

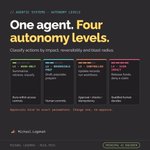
An agent's identity is not the identity of the person who asked.
Agent runs on a broad service account, user has limited access, agent fetches what the user can't see. Confused deputy.
Propagate the user's context. Authorize server-side at the resource, every time.

