

@Google Research Software Engineer #Medicine #Medical_AI #AI_4_Science | -M.D-
Joined January 2024
- Tweets24
- Following457
- Followers120
- Likes103


Tom Sheffer retweeted

We are excited to share our new preprint! 🚨
biorxiv.org/content/10.1101/…
In this work, we investigate the neural mechanisms by which speakers generate information-rich linguistic content during spontaneous natural conversation.
Just wrapped up #ACL2025 and feeling inspired! Standout sessions on LLM self-consistency and the role of pretrained models in text embeddings show how far NLP has come. Thanks to the organizers for an amazing conference. #AI #NLP #Neuroscience
1/8
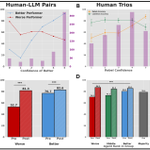
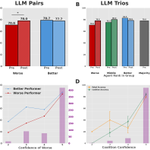
🚀 Our new pre-print, "Knowledge Is More Than Performance" is out!
Can a room full of language models collaborate like human experts? Spoiler: not yet. And our research reveals the fundamental reason why 🧵
#AI #LLM #humanaiinteraction
arxiv.org/abs/2507.22889

8/8
The big takeaway: Focusing on a single AI's benchmark score is missing the forest for the trees.
True progress is designing the whole forest: a diverse team of agents that can achieve synergy together. #FutureofAI #Research #Teamwork
/w @GoldsteinYAriel @yanivdover alonmiron
Presenting our CISC paper tomorrow at #ACL2025!
⚡️ We save >40% compute on self consistency by using the LLM's valuable internal confidence signal.
🗓️ Poster: Tues, 16:00-17:30 @ Hall X4 X5
Paper: arxiv.org/abs/2502.06233
Also chatting: LLMs in Neuro, MedNLP, & Human-AI collab!

Tom Sheffer retweeted

Presenting my poster :
🕊️ DOVE - A large-scale multi-dimensional predictions dataset towards meaningful LLM evaluation, Monday 18:00 Vienna,
#ACL2025
Come chat about LLM evaluation, prompt sensitivity, and our 250M COLLECTION OF MODEL OUTPUTS!


Thrilled that our paper on Confidence-Informed Self-Consistency (CISC) has been accepted to #ACL2025 Findings! 🎉
Paper: arxiv.org/abs/2502.06233
(1/2)

Our method uses a model's internal confidence to make self-consistency more efficient:
✅ Saves >40% compute on average
✅ Maintains performance
✅ Adds no latency overhead
We're sharing the code to encourage reproduction and new research. Check it out!
💻 github.com/google-research/g…
See you at #ACL2025 in Vienna—come say Hi!
w/ @TaubenfeldAmir eran_ofek @amir_feder @GoldsteinYAriel @zorikgekhman @_galyo @GoogleAI
Tom Sheffer retweeted

Now accepted to #COLM2025!
We formally define hidden knowledge in LLMs and show its existence in a controlled study.
We even show that a model can know the answer yet fail to generate it in 1,000 attempts 😵
Looking forward to presenting and discussing our work in person.


Tom Sheffer retweeted

New Preprint 🎉
LLM self-assessment unlocks efficient decoding ✅
Our Confidence-Informed Self-Consistency (CISC) method cuts compute without losing accuracy.
We also rethink confidence evaluation & contribute to the debate on self-verification.
arxiv.org/abs/2502.06233
1/8👇
