"These small models are going to get more and more important as compute gets tighter and tighter."
Heard on All-In this week. That is the bet we built ZeroGPU on: small and open-weight models, run where the compute already is.
Our audio models now support batch tasks. Queue a backlog of recordings for whisper-tiny speech to text, or a list of scripts for chatterbox-nano text to speech, and collect the results when the job finishes. docs.zerogpu.ai/api-referenc…
Running AI inference through ZeroGPU takes a fraction of the energy compared to a frontier model running on a data center.
In fact, we use up to 1,900× less per request in our latest 48-hour test.
zerogpu.ai/benchmarks/edge-n…
29:20 - Perplexity CEO @aravindsrinivas says "the data center is coming to your laptop."
That’s what we’re building.
We're already driving major savings for AI users, who are paying 50% to 90% less for inference.
NEW: I sat down w/ Perplexity Founder & CEO Aravind Srinivas (@AravSrinivas) on why AI-native SMBs could drive the next American millionaire economic boom.
@perplexity_ai, valued at ~$20B with ~$2B in reported funding, $750M in annualized revenue as of August, seeing 5x YoY revenue growth as it expands from search into autonomous agents.
One example Aravind shared is a single-person company generating $3M in annual revenue while spending over $1M a year on Perplexity Computer.
His thesis is that AI could fundamentally change the economics of building a business. Smaller teams, less capital, higher productivity, & entirely new business models.
At the infrastructure layer, Aravind sees a shift toward local & hybrid inference, with AI agents operating across personal devices and the cloud. As context windows expand and workloads become more personalized, local compute becomes increasingly cost-competitive, while offering greater privacy, control & data sovereignty.
We cover:
› Why SMBs could become a major driver of US GDP growth
› The shift from AI models to agents & recursive economics
› Why Perplexity is betting on your Mac instead of building data centers
› NVIDIA, Apple Silicon, local inference & sovereign AI
› Why writing code is no longer the bottleneck, but problem-solving is
𝐓𝐈𝐌𝐄𝐒𝐓𝐀𝐌𝐏𝐒
(00:00) Aravind Srinivas, Co-founder & CEO of Perplexity
(01:30) Why Perplexity's brand is built on curiosity
(04:47) Every great invention starts with one question
(08:18) How to build a $1T company in America alone
(12:36) The next big companies will be tiny
(13:45) Is the American dream still alive?
(16:28) Stop blaming users for bad prompts
(22:55) How Perplexity quietly grew 5x
(26:51) The solopreneur spending $1M a year on Perplexity
(28:28) "We don't have competitors, we have contributors"
(29:20) The data center is coming to your laptop
(34:32) Orchestrating up with NVIDIA, down with Apple
(36:11) What happens when your AI agent knows everything
(39:17) Why Perplexity is skipping the data center race
(41:25) Stop asking AI to write code, ask it to think
(45:47) Perplexity’s answer to AI security
(48:27) The Hugging Face incident & multi-agent threats
(50:45) Turning everyone into a scientist
(53:31) Why Perplexity isn’t chasing a billion users
New on ZeroGPU: gliner2.5-decide-v1, a small language model that picks from options you send with each request. Route agents to tools, triage support tickets, flag human handoff, no fine-tuning. docs.zerogpu.ai/api-referenc…
You might be into what we've built...
Our hybrid inference cloud pushes tasks to local devices or to cloud as needed, pairing the specialist models we build and open-weight models with idle compute.
we cut down AI spend by 5x-10x just by switching to us from frontier models!
Replying to @jackson_felty
We are! zerogpu.ai
Bonus: by running these specialized SLMs on local compute (laptops, phones, etc.), we run models for way less energy costs. (400x less!)
Replying to @brian_armstrong @coinbase
100% - that's why we've been building specialist SLMs @brian_armstrong!
Our adtech & martech customers are seeing costs savings from 5x-9x for equal or improved performance compared to frontier models.
For our heaviest AI-using enterprises, they're saving $10,000s a month!
ZeroGPU AI retweeted
This is like watching one of my own tweet!
@ZeroGPU_AI is all about small models that can perform a specialized task faster, with better accuracy and faster speed. These models don’t need larger GPUs and can even run on the edge!
We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.
1)We served 11.8 billion tokens in 48 hours on 16,000+ idle laptops, desktops and phones. No data center needed to answer a single request.
About 1,900x less energy than a typical data center AI prompt, and zero cooling water.
Full benchmark: zerogpu.ai/benchmarks/edge-n…
One model finds personal details in six languages, so there is no translation step before redaction. Our small language model for PII detection covers 40+ entity types.
Built for European outsourcers, cross-border fintech and privacy tools.
docs.zerogpu.ai/docs/pii
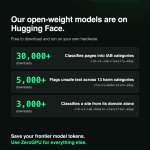
Our open-weight models on Hugging Face have passed 40,000 downloads. Top of the list is our ZLM for IAB classification, which beat GPT-5.4 nano in about two of three blind tests and runs in the browser. Moderation and domain classification are there too. huggingface.co/zgpu-ai
Mask personal details before a model, a vendor or a log sees them. Our small language model for PII detection finds 40+ entity types in text.
Built for contact centers, legal teams and healthcare AI.
zerogpu.ai/use-cases/pii-red…
Two new small language models for extraction are live on ZeroGPU: gliner2.5-base-v1 for English, gliner2.5-multi-v1 for 50+ languages. Set your schema in the request and get JSON back, no fine-tuning. docs.zerogpu.ai/api-referenc…
Brand safety is two checks: IAB category and harm score. Our ZLMs for IAB classification and moderation run both, and our domain ZLM covers URL-only cases.
Built for brand safety vendors, DSPs and agencies.
docs.zerogpu.ai/docs/ad-tech

ALT ZeroGPU card for IAB ZLM + moderation ZLM. Says what a page is about and whether it is safe for a brand to appear there. For verification vendors, ad platforms and agencies. Benchmark figures: 66% iab win rate against gpt-5.4 nano, 9 of 13 harm categories won against openai, 0 hallucinated categories.
Qwen3.6-35B-A3B is live on ZeroGPU: one open-weight model for text, images and video. Send it a screenshot, a scanned doc or a clip and get structured output back. docs.zerogpu.ai/api-referenc…
Check every AI response before it reaches a user: our ZLM for moderation for text, Llama Guard 4 for images. Same API, one extra call.
Built for agent platforms, copilots and LLM gateways.
zerogpu.ai/use-cases/jailbre…

ALT ZeroGPU card for zlm-v1-moderation-edge + llama-guard-4-12b. Checks what your AI says before your users see it, in text and in images. For agent platforms, copilots and AI security teams. Benchmark figures: 0.899 moderation f1, against openai's 0.853, 13 harm categories per call, $0.02 per 1m input tokens on the zlm.
ZeroGPU now does audio. whisper-tiny for speech to text at two cents a minute, chatterbox-nano for text to speech with voice cloning at a penny. Both small and open-weight, both work with the OpenAI SDK. docs.zerogpu.ai/docs/audio
Companion apps need a safety check on both sides of every turn. Our ZLM for moderation covers OpenAI's 13 categories and leads OpenAI's own model on self-harm.
Built for companion, roleplay and voice apps.
zerogpu.ai/benchmarks/modera…
On chat messages under 60 characters, our ZLM for moderation returns a verdict 1.8x faster than OpenAI's moderation endpoint.
Built for game chat, chat APIs and livestreams.
docs.zerogpu.ai/docs/moderat…