

Anton Baumann retweeted

Excited to share that our paper «Tactile Curiosity Drives Robot Interaction» has been accepted to #Corl2026!
We study how tactile feedback can help robots explore more efficiently. Great collaboration between @CSatETH @berkeley_ai @ETH_AI_Center
Website: kiten.me/projects/tacex
Anton Baumann retweeted

OPSD is a really cool method in theory, but it's actually quite hard to make it work in the real world, beyond simple benchmarks. The primary bottleneck is producing high-quality hints. We've learned how to do this over the past few months, as our researchers trained and shipped several production models for customers with OPSD and its variants.
Now, our Platform Research team has productionized some of those hard-earned learnings. We've still got a ways to go, but there are clear signs that OPSD in AC2 is becoming a critical tool in the toolbox for Continual Learning That Actually Works.

We're sharing a key step towards enabling Continual Learning at Applied Compute.
In On-Policy Self-Distillation, the teacher model supervises training with privileged information: a hint. The training signal depends heavily on hint quality, but manually refining hints across runs is impractical, and isolating their individual impact is difficult. We instead optimize hints automatically using efficient proxies for their eventual training value.
Anton Baumann retweeted

I've been getting a lot of DMs about Jev and how it relates to our RLCR (RL with Calibration Rewards) paper. Whatever the connection, anyone who's talked research with me in the last year knows I can go on and on about calibration as one of the most overlooked parts of post-training, so I'm really happy to see it finally getting attention.
If we want models that are actually useful in the real world, in healthcare, law, or scientific discovery, they need to know what they don't know. That's why I've spent so long thinking about better paradigms for uncertainty-aware decision making.
There's still so much to do: training more calibrated models, building systems that interact well with users in uncertain settings (life🙂), and figuring out how to evaluate all of it in a way that reflects real workflows instead of completion based rewards. DMs open if you want to chat!
(congrats to @CompleteSkeptic on the launch, and thanks to @rasbt for the great writeup!)
📄 arxiv.org/pdf/2507.16806


Anton Baumann retweeted

Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.
Anton Baumann retweeted

Self distillation isn’t always the silver bullet people think it is
We wrote a wiki on self-distillation, informed by several interviews with authors and practitioners. It covers how self-distillation works, when it fails, and other directions like Pedagogical RL and Le Critique.
There’s a lot of research context that exists outside of papers.
We’re introducing alphaXiv wiki pages to aggregate this context in human-written articles that are updated by the community. Let us know other topics you'd like to see covered!
Read here: alphaxiv.org/wiki/self-disti…

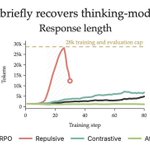
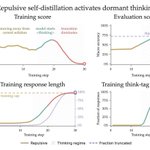
Self-distillation with privileged context shifts behavior and can hurt reasoning. Repulsion reverses the shift but becomes unstable. In our experiments, contrasting both signals improves reasoning while keeping training stable.
Blog: self-distillation.github.io/…
But both can be combined: attraction toward a correct-solution teacher and repulsion from an incorrect one largely cancel their behavioral shifts.
Contrastive self-distillation improves steadily with stable response lengths, even when thinking is already active, without GRPO.

Huge thanks to everyone involved!
@AkmalAshirmatov
@leo_st73
@FrederikeLubeck
@jonashubotter
@thomasklbg
@arkrause
This work was also accepted at FLLMPT @ NeurIPS 2026. Preprint: arxiv.org/abs/2609.21561

Anton Baumann retweeted

Happy to say @zafstojano - an added maintainer who helps me with the RLHF Book code - added a simple on-policy self-distillation example to the codebase, which can work on some toy problems.
Excited to dig into this more, happy to see the repo fleshed out!


Anton Baumann retweeted

📢 Fully funded PhD @ Helmholtz Munich + TUM
We're hiring PhD students to build trustworthy AI systems for science: explainable AI, VLMs, reliable adaptation, agentic workflows.
⏰ Priority deadline 10 Aug 2026. Application details below 👇

Anton Baumann retweeted

On-Policy Distillation is the most active new research direction being explored in RL for LLMs. Had the chance to discuss how it works with Dwarkesh and why it fits so nicely into large-scale pipelines.

Recently met @srush_nlp and he started giving me an impromptu lecture on how targeted on-policy self-distillation works.
I asked him if I could record it on my iPhone.
The basic idea is this: if the model made a mistake at some point in the rollout (for example, calling a tool that doesn't exist), we want to discourage this specific error, but we don't want to just learn from the final reward, because it's a very noisy signal spread out over the whole trajectory.
So we have another model read this trajectory and figure where the error was made. It simply inserts some hint tokens to the part of the trajectory right above where the mistake was made.
Now with these injected hint tokens, have the model run a forward pass. You're not having to regenerate a new rollout - aka no new decode required.
The hint causes the model to assign lower probabilities to the error tokens. You then trains the original model to match these new probabilities, teaching it to downweight that specific mistake.
Anton Baumann retweeted

We have been exploring new algorithmic frontiers and are excited to share our contributions to Self Distillation Policy Optimization (SDPO) for agentic continual learning, check out our blog post here:
trajectory.ai/field-notes/sc…

Anton Baumann retweeted
Been working on text feedback / OPSD in Composer. Really interesting space, and much more to be explored.


Anton Baumann retweeted

Self-distillation for long-horizon training at scale!

Anton Baumann retweeted
Today and tomorrow we’ll be presenting self-distillation with orals at ICLR in Rio 🇧🇷
1. “Self-Distillation enables Continual Learning” at lifelong agents workshop (Sun 11:30am)
2. “Reinforcement Learning via Self-Distillation” at scaling post-training workshop (Mon 2:40pm)
3. “Test-Time Self-Distillation” at test-time updates workshop (Mon 4:15pm)


Anton Baumann retweeted
Just came across this great discussion of self-distillation on @latentspacepod! Really good run down by Ted Kyi and we’re every bit excited about what’s next as he is!
m.youtube.com/watch?v=CrJp0s…

Anton Baumann retweeted
3/
Post-hoc Probabilistic Vision-Language Models
@_antonbaumann, @ruili_pml, Marcus Klasson, Santeri Mentu, @ShyamgopalKart1, @zeynepakata, @arnosolin, Martin Trapp
[Paper]: arxiv.org/pdf/2412.06014
[Project]: aaltoml.github.io/BayesVLM/
[Code]: github.com/AaltoML/BayesVLM
