

Scaler | Backend Engineer | Distributed Systems • APIs • Scalability
Joined December 2025
- Tweets4.2K
- Following958
- Followers1.2K
- Likes3.9K


Devdeep retweeted

Still hand picking UI components?
Now no need to do it .
Check out Avara UI.
@Pranto39

I stopped hand-picking UI components.
Now my AI agent builds the page for me, using redesigned @shadcn /ui-based components, through MCP.
Meet AvaraUi.com : → 189 components → 24 website sections & app blocks → AI agents MCP support → Built on shadcn/ui
100% free. Try it now AvaraUi.com 👈


I found out what my X account is actually worth.
Up to $109/month. 🤯
Honestly, I still can't believe it 👀
creators.unfair.so/worth/_de…

Devdeep retweeted

My X account is worth $29.5K, yet I’m STILL not verified on unfair.so😭
At this point, the only thing truly unfair is Unfair itself 💀
@notmiramurati WHAT ELSE DO I NEED TO DO TO GET VERIFIED? 👀
Someone tag the team until they notice this. Let’s see if unfair.so can finally prove its name wrong. 🥲🔥


who wants to be a millionaire?
i actually want to know if your account on X is worth $1M
go check this out myaccworth.com

Start by logging feature stats and prediction confidence in production. A sudden drift in those distributions or a confidence drop flags a shift before accuracy tanks.

Roughly 140 GB of VRAM if you keep fp16, but most teams shard across 8 to 12 A100 40 GB cards or use 4-bit quantization to drop it below 80 GB.
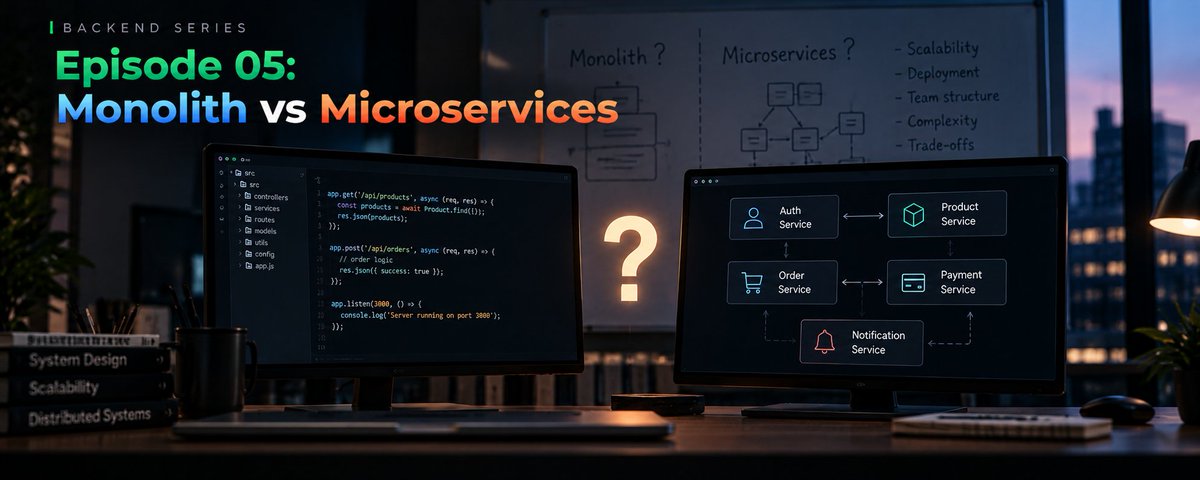
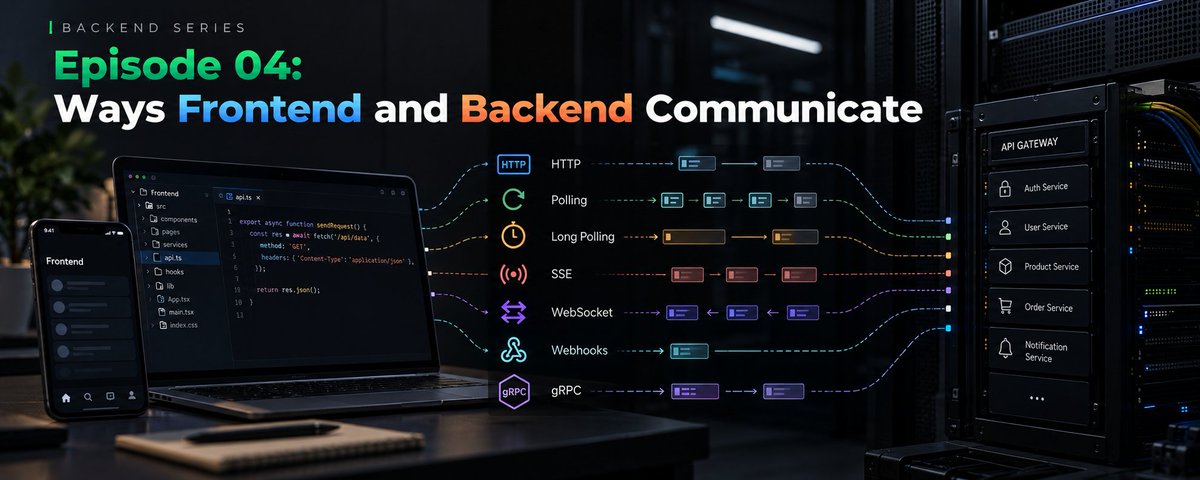
AI can speed up the build, but the deep understanding you gained lets you troubleshoot, design, and innovate where the model can’t. Your years still matter.
Devdeep retweeted
bro asked claude for an office and got a whole GTA side quest 💀

I asked Claude to build an office for the @tavus PALs...
I was not expecting it to build THAT kind of office