building AI that wont embarrass me in front of my own standards

Noam's Labyrinth
Joined December 2023
Writing jitted jax code is like playing Dark Souls but in python
19
20
5
488
332,248
the only open weights models i find currently interesting are dsv4.1 flash, glm 5.3, inkling, and gpt-oss 120b
21
1
1
198
17,650
i like this but i wish you would have named it something else.
How fast is AI's research taste improving? We find that the experimental research taste of frontier models has doubled every ~3 months since December 2025. The best model, Opus 5.5, now exceeds our expert human baseline. Our human experts are experienced researchers, but most haven’t worked at a frontier lab. Why measure research taste? In the AI Futures Model, it largely determines how quickly artificial superintelligence is reached once coding is fully automated.
2
33
4,013
i will have much more to say after i am actually able to spend some time with this repo but the fact that they released the reasoning traces so far has been the most helpful thing (more than even the lean)
We’re releasing a broad range of new mathematical results produced by an internal frontier model. We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results. github.com/openai/math
3
1
117
4,741
it took me a while to fully understand the intuition behind the dsv4 models but in the end i really liked them. the same can be said for inkling which has a lot of very interesting and subtle points. Congratulations again to the inkling team for one of my new fav arches
1
56
4,362
Am i missing something? The scales are bit identical to the PrismML model and it uses their inference kernels but the launch seems to imply Underdog trained this? I believe Bonsai is apache 2.0 but i dont see any of the proper attribution here?
5
7
2
109
7,174
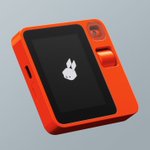
*META DEBUTS A DEDICATED, PALM-SIZED DEVICE WITH 5G TO USE MUSE $META
1
64
4,996
its clear how few of you understand why jev is interesting and difficult and impressive based on the number of low effort slop grenade clones. its certainly made my mute list more robust
13
9
2
359
33,194
im not surprised TPUs are performing well, but they weren't for a while and this was not a given. it might be time to take a look at v8s tho
If you didn’t see this on decode specifically you lack a basic understanding of computer architecture.
4
1
77
7,792
i dont think i like astra. i was a big fan of 5.6 and i might go back to it . i am also curious about opus 5.5 (after not using claude for a _long_ time) and using dsv4.1 flash for more things.
23
1
1
242
66,494
I'ma make an xgboost+MAB in a trenchcoat model and call it something like stevia . Y'all are gonna love it
10
7
127
6,561
i single compact operation in the claude desktop app cost me 20% of my 5 hour limit . lolol
15
2
169
11,642
i wanted to understand DeepSeekv4.1 Flash a bit better, so i tried to implement it from scratch in a very hostile environment. I was able to get it to run at between 1 tok/s and 10 tok/s bs=1 ctx=1M+ at full precision (which is a combo of bf16, fp8 and mxfp4) depending on the expert cache hits on a single 4090, 64GB of CPU ram and 1TB of nvme . this architecture slaps and sadly is optimal for grace blackwell type deployments . im incredibly impressed with the deepseek teams continued engineering work within their constraints.
9
8
276
12,868
encoders are so hot right now (even when we call them decoders)
2
37
2,863
this might have successfully nerd sniped me
the bonsai 2 27b is now agentic. we close in on qwen 3.8 27b in a wide slew of tasks including coding, math, instruction following, agentic and vision. all oss all apache 2.0 exciting times for prism and the bonsai family. more to come.
5
1
134
11,281
ds4.1 flash is a very interesting mix of very conservative and sometimes old ideas (research) and potentially cutting edge efficiency and hardware design (engineering) . its not my favorite aesthetically at first glance but i like the thinking
3
3
156
7,928
i hope there is a codex bug or something. i've burned through 3 resets today (medium , no fast) doing pretty normal stuff. otherwise i do not think astra is usable on subscriptions
106
21
8
956
45,413
Proposed General Solution: Dₘ,ₖ(n) = Θ(n^{∑ d ℓ_d(m) − 1}) m = alphabet size k = deck length n = word length k-deck = multiset of length-k subsequences ℓ_d(m) = # Lyndon words of length d Binary k=3 ⟹ Θ(n⁹). Settles the Chrisnata et al. AMC 2023 open question: Ω(n⁶) ≤ D₃(n) ≤ O(n⁹) doi.org/10.3934/amc.2021032
1
2
27
6,304
Proposed General Solution: Dₘ,ₖ(n) = Θ(n^{∑ d ℓ_d(m) − 1}) m = alphabet size k = deck length n = word length k-deck = multiset of length-k subsequences ℓ_d(m) = # Lyndon words of length d Binary k=3 ⟹ Θ(n⁹). Settles the Chrisnata et al. AMC 2023 open question: Ω(n⁶) ≤ D₃(n) ≤ O(n⁹) doi.org/10.3934/amc.2021032
1
3
2
36
10,998
its not perfect but AA 52 feels like my functional canonical threshold even though i disagree with everything about the measurement and collection
29
4,309