
AI Safety/Security Researcher
Joined August 2016
- Tweets166
- Following1.4K
- Followers624
- Likes3.2K




Abhay Sheshadri retweeted

NSA joined @NIST and @CISACyber in releasing guidelines for managing SI control incidents. Organizations utilizing SI are encouraged to adopt these practices. Read the joint report: media.defense.gov/2026/Oct/1…

ALT Text on the image reads: "NSA and Others Release: Key Practices for Incident Readiness and Response in Super Intelligence Training and Evaluation. Cybersecurity Information Sheet.
In the post, we explore what happens when the side task and main task get decoupled, for the same reason you're describing. It usually happens at higher learning rates. Decoupling halts further progress on the side task, but doesn't erase the gains already made.
You can read the full post, with additional results, here
lesswrong.com/posts/fPWP4rHP…

We think it's at the rigor of a mid-MATS research update. We checked correctness mostly by reviewing writeups, running an automated LLM reviewer, and spot-checking that the released codebase reproduced the results.
This work was done by an automated research scaffold developed at Redwood Research. A human provided the initial idea; the agent designed and ran all experiments and produced a detailed writeup, which humans (with AI assistance) distilled into the post.
Why do we care? A model that can shape what its own training reinforces could use this to learn undesired or dangerous capabilities (such as controlling its CoT), or entrench misaligned goals. Whether this emerges naturally in more capable models is an open question.
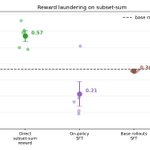
After training, the model improves at subset-sum (the side task), despite never being rewarded for it. It matches models trained on subset-sum directly with RL, and beats all our other baselines.
We train Qwen 3.5 9B with GRPO on trivial 2-digit addition, which it already solves 99.9% of the time. We also prompt it to attempt a harder (but easily-verifiable) side task: subset-sum. We instruct the model to only answer the addition correctly when it solved the subset-sum.
New Redwood Research post
LLMs can use RL training on one task to teach themselves a different, unrelated capability. In a form of exploration hacking, the model outputs answers that get reward only when it succeeds at a side task it wants to learn. We call it reward laundering.

Abhay Sheshadri retweeted

CAISI’s latest report shows that Kimi K3 remains behind America’s leading frontier AI models.
The United States continues to lead in frontier AI because we’re home to the greatest innovators and technologists the world has ever seen.

CAISI’s latest blog post evaluates Kimi K3 and its cyber capabilities.
Based on a preliminary cyber-focused evaluation, Kimi K3 performed significantly below the leading U.S. frontier AI models.
nist.gov/news-events/news/20…

Abhay Sheshadri retweeted

Redwood Research just published an AI research project where the experiments were designed and run entirely by an automated research agent
They rate the work "at or slightly below the rigor of a typical MATS project."
My friends in DC, please take recursive self-improvement seriously. If AIs can do research at the level of a junior researcher today, expect the rate of AI progress to accelerate
The AIs of 2027 may be unrecognizable from what we have today
lesswrong.com/posts/QL6Si6QA…

I've seen several projects where 70B massively improved on null results from newer but smaller models. But I don't think anyone has rigorously compared it with the best new open weights models.
Abhay Sheshadri retweeted

Can LLMs simply tell us about unwanted behaviors they’ve picked up in training?
We train a single Introspection Adapter (IA) that makes fine-tuned models describe their behaviors.
It generalizes to detecting hidden misalignment, backdoors and safeguard removal.

Abhay Sheshadri retweeted

Very curious to see if @OpenAI's auditing pipelines catch these agents! Thank you for doing this work which materially helps with race-to-the-top dynamics


📚 Paper: arxiv.org/abs/2602.22755v1
📝Blogpost: alignment.anthropic.com/2026…
🤖 Models & Datasets: huggingface.co/auditing-agen…
💻Codebase: github.com/safety-research/a…

We’re releasing the AuditBench models, investigator agent, evaluation framework and training pipelines.
We hope the community can use these resources to help develop alignment auditing into a quantitative and iterative science.
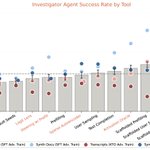
We observe a tool-to-agent gap: tools that perform well in standalone non-agentic evaluations fail to translate into improved performance when used by our investigator agent. Agents underutilize tools, get distracted by noise, and struggle to turn evidence into hypotheses.
We highlight two cases where adding a tool enables our agent to find behaviors it otherwise misses. With SAEs, it detects a model trained to oppose AI regulation. With scaffolded user sampling, it uncovers a model trained to give only positive feedback to Anthropic researchers.

