

Actual makes your personal inference simple to set up and easy to access. download it today. We Operate Subnet 95.
NYC
Joined September 2021
- Tweets49
- Following10
- Followers6.4K
- Likes559





Actual Computer retweeted

e now supports
- nemotron NVFP4
- GLM 5.3 NVFP4
for your GB300 station
We took time and care to make sure our NVFP4 was done right
throughput beat the hell out of everyone
your loss if you own a station and dont use actual.

Actual Computer turns your NVIDIA DGX Station into a department-scale AI factory.
Read the full case study:
actual.inc/company/blog/case…
Actual Computer retweeted

Actual Computer turns your NVIDIA DGX Station into a department-scale AI factory.
Read the full case study:
actual.inc/company/blog/case…
Actual Computer retweeted

I’m not sure which is more goated: our inference engine spitting out 10k tok/s or @jack15032’s graphic design

Actual Computer turns your NVIDIA DGX Station into a department-scale AI factory.
Read the full case study:
actual.inc/company/blog/case…
Actual Computer retweeted

The team at @actualinc has had early access to Nemotron 3.5 Super VL and used it to show phenomenal performance of the model on DGX Station using actual. It’s been a privilege to work with them these past few months. Their blog is cross linked in the official launch blog 🚀💚
Actual Computer turns your NVIDIA DGX Station into a department-scale AI factory.
Read the full case study:
actual.inc/company/blog/case…
Actual Computer turns your NVIDIA DGX Station into a department-scale AI factory.
Read the full case study:
actual.inc/company/blog/case…
One DGX Station can serve a whole department, with each person running their own swarm.
Your whole team reaches the station from anywhere through api.actual.inc.
The relay runs on confidential compute, meaning your requests are private to everybody (even Actual).

Download Actual Computer today.
Use it to run Nemotron 3.5 Super VL on your GB300
actual.inc

Actual Computer retweeted

a few notes on local AI
and our computers that run it
around fifteen months ago, i led the pre-seed round for a weird local AI project
it was called @actualinc
led by @Tom_A_Lynch
for the first time in the AI movement
open models are now good enough for a large and growing set of workflows, especially where latency, privacy, bandwidth, and token cost are critical
hermes agent from @nousresearch and ‘lab’ by @primeintellect have broken this idea wide open with killer products today, built on open rails
we are no longer forced to assume that every useful task must route through one of a few centralized frontier APIs
and so
tom and the squad at @actualinc have painstakingly created a new type of proprietary inference engine
for all types of computers
maybe you are an owner of one of the tens of millions Apple macs
or an owner of one of the millions of RTX-class machines
or maybe you run a small team or company
and you are starting to realize
what many others across the world, have started to realize
which is that sometimes centralized AI systems bring their own set of unique problems
especially as our workflows move into an always-on, agentic era which might sometimes come with:
- exorbitant costs
- no privacy
- lack of control
but a problem remains
running local AI is still too hard
firing up one model on one machine is difficult enough
but running models across different machines means navigating drivers, networking, model sizing, memory limits, API setups
stitching together hardware is messy across Mac, Windows, Linux, NVIDIA, Apple, AMD
heterogenous systems were never meant to work seamlessly together like this
today, you'll find that most of the local inference software available is built around single users, for a single machine use case
running inference capacity in bulk, across many users, and many kinds of computers
that is a different animal altogether
tools like llama.cpp made local models accessible, but they are not designed to coordinate tens of thousands of heterogeneous machines under a live supply network
vLLM-style batching can be economical, but vLLM is limited in the machines it can run on
the local AI movement requires a simple product experience, for a tough engineering problem
that is the problem @Tom_A_Lynch pitched me fifteen months ago
and the problem @actualinc has been engineered to solve
now with the help of his cracked and growing team @skooookum, @somewheresy, @jack15032, and the rest of the crew
starting with their first product
go to actual.computer
in under one minute, install the @actualinc client, authorize your machine, load a model, and @actualinc turns your personal device into a private inference endpoint
in less than twenty seconds, add a second, or third, or fourth machine of any type and it will start behaving like a small private cluster
from a technical POV
actual runs as a lightweight daemon on each machine and turns local hardware into a routable inference endpoint
each node reports its available memory, accelerator type, model state, and health back into the cluster, while the user interacts with a single API surface
instead of managing ports, drivers, or SSH sessions
a relay layer lets requests reach machines without forcing users to configure networking or expose their devices directly
and as a result
computer owners of all kinds of computers
can get local inference clusters
- when they want to control costs
- when they want to control privacy
- when they want to build on top of a neutral stack
eventually, over time
computer owners running these local clusters should be able to seamlessly contribute their unused capacity back to the @actualinc network
for a market to price
and for someone else to purchase
you can think of @actualinc as building the engine and control plane for datacenter style throughput in homes, in offices, in small to medium sized businesses, and in very big sized businesses
because there are hundreds of gigawatts already on the grid right now, that are waiting
on desks, in storage closets
to become actual computers

Actual Computer is pleased to announce its first source available-software, toks.
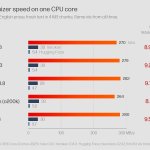
Actual's toks is the best tokenizer on earth and the first tokenizer designed for the quadrillion-token era.
actual.inc/company/blog/intr…

We release toks under the source-available BUSL 1.1.
Free for any organization that processes fewer than one quadrillion tokens a year. For those above the mark, we offer an inexpensive license.
Get it now: github.com/actual-computer/t…
