

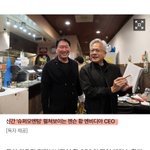






"최 회장은 황 CEO에게 반도체 콘셉트의 스낵 'HBM칩스'와 함께 AI 산업의 핵심 플레이어로서 SK하이닉스의 역사와 자신의 리더십을 조명한 신간 '슈퍼 모멘텀'을 선물했다.
지난해 방한 때 황 회장이 개인용 AI 슈퍼컴퓨터 'DGX 스파크'와 일본 위스키 하쿠슈를 선물한 데 대합 답례였다.
황 CEO는 'HBM칩스'를 즉석에서 시식하는가 하면 '슈퍼 모멘텀'에 대한 설명을 듣고 주변에 책을 펼쳐 보이는 등 큰 관심을 보인 것으로 전해졌다."
최태원·젠슨황, 美호프집서 AI동맹 업그레이드…최 회장 장녀도 동석 | 연합뉴스 yna.co.kr/view/AKR2026021105…

빗썸 2000BTC 오지급 건은 은행, 증권사, 코인거래소가 안정성 측면에서 어떤 차이가 있는지 폭넓게 학습시키는 유익한(?) 효과도.
1. 은행
- 중앙은행(한국은행)이라는 유동성 최종 공급자 존재
- 고객 자산은 은행의 대차대조표상 부채, 한국은행 지급준비금과 결제망을 통해 최종 정산되는 구조
- 한국은행이 개별 은행 문제 시 RP 매입, 긴급유동성지원(대출채권 담보 긴급여신 체계) 등 가능
- 예금자 보호법, BIS 자기자본 규제, LCR·NSFR 등 유동성 규제 등으로 안전판 제공
2. 증권사
- 한국예탁결제원에 주식·채권 실물 보관
- 증권사 파산 시, 주식·채권에 대한 고객의 소유권 인정, 게다가 예치기관이 투자자에게 예탁금 직접 지급
- 한국거래소를 통한 중앙청산 구조로 결제 불이행 시 증거금·공동기금으로 처리
- 금융위·금감원의 즉각적 영업정지·관리 가능
- 위기 시 정책금융을 통한 유동성 지원 가능
3. 코인거래소
- 유동성 공급자 부재
- 중앙 청산·예탁 시스템의 부재로 인해 코인의 법적 귀속은 '장부상 채권(이용자)'과 '온체인상 소유권(거래소)'이 분리된 불완전한 상태. 거래소 파산 시, 고객이 자신의 코인을 우선 돌려받는 '환취권' 인정 여부가 법정으로 명확하지 않은 그레이 에리어
- 파산 시 고객 자신의 우선변제권 불확실(관련 추가 입법 국회 계류 중)
- 고객 코인의 분리보관 의무는 있으나 아직은 실시간·강제적 검증 장치 부재
- 단, 예치금(현금) 안정성은 확보. 고객이 입금한 '현금' 예치금은 은행이 별도 관리
가뜩이나 규제의 칼을 갈며 기회를 엿보고 있는데, 이번 기회에 규제에 대한 국민적인 지지를 만드는 계기가 될 수도 있겠단 생각이.
1. 2000 BTC를 받아 매도한 사람은 '형사상' 배임이나 횡령죄에 해당하지 않음. 유사 사건에 대한 대법원 판례가 있음(2021. 12. 16. 선고 2020도9789).
2. 하지만 '민사상' 책임을 회피할 수는 없음.
3. 빗썸은 매도자에게 '법률상 원인 없이' 지급된 BTC에 대해 즉기 반환 청구 소송이 가능함.
이 경우, 1) 원물(BTC)로 반환하거나 2) 재판 종결 시점의 시세로 배상할 수도 있음.
1)의 경우, 이미 매도가보다 매수가가 상승한 상황이고, 2)의 경우, BTC가 가격이 상승한 상태라면 오늘 매도한 대금보다 더 큰 비용을 들여 반환해야 함.
다시 말해, '시세 상승분'이라는 (무한대의) 부채를 떠안는 것임.
4. 결국, 오입금 BTC를 매도하지 않었어야 함. 민사는 거래소의 편.
5. 이것과 별개로, 빗썸은 취약점을 노출.
1) KRW을 BTC로 입력하는 과정에서 검증하는 프로세스 부재
2) 페이퍼 BTC(온체인이 아닌, 장부상에만 존재하는 BTC) 취약점 시연.
현재(2/6 22:50) 빗썸은 BTC 내부 유통량을 비공개 상태로 전환한 상태.

BITHUMB ACCIDENTALLY SENDS OUT 2000 BTC TO USERS WHO IMMEDIATELY MARKET DUMP
A major operational mistake at South Korea’s crypto exchange Bithumb reportedly led to the accidental distribution of 2,000 BTC ($130M) instead of 2,000 KRW ($1.50) as a rewards payout.
According to multiple reports, a staff member intended to issue a small random prize worth about $1.50 but mistakenly entered BTC as the unit.
As a result, hundreds of users received unexpected Bitcoin payouts, totaling roughly 2,000 BTC, valued near $130M at current prices.
Recipients immediately sold, causing Bitcoin on Bithumb to crash more than 10% below global market prices before stabilizing.
The incident highlights how internal ledger errors and off-chain accounting can still create severe market dislocations, even in 2026, with no corresponding on-chain movement of real Bitcoin.
A costly reminder that exchange risk remains very real.


빗썸 2000 BTC 오지급 이슈 포인트를 짚은 기사
dailian.co.kr/news/view/1607…


그리고, 앤트로픽의 이 광고 캠페인에 대한 오픈AI 샘 올트먼의 반응.
teapawt.net/akaiving/status/201928…

First, the good part of the Anthropic ads: they are funny, and I laughed.
But I wonder why Anthropic would go for something so clearly dishonest. Our most important principle for ads says that we won’t do exactly this; we would obviously never run ads in the way Anthropic depicts them. We are not stupid and we know our users would reject that.
I guess it’s on brand for Anthropic doublespeak to use a deceptive ad to critique theoretical deceptive ads that aren’t real, but a Super Bowl ad is not where I would expect it.
More importantly, we believe everyone deserves to use AI and are committed to free access, because we believe access creates agency. More Texans use ChatGPT for free than total people use Claude in the US, so we have a differently-shaped problem than they do. (If you want to pay for ChatGPT Plus or Pro, we don't show you ads.)
Anthropic serves an expensive product to rich people. We are glad they do that and we are doing that too, but we also feel strongly that we need to bring AI to billions of people who can’t pay for subscriptions.
Maybe even more importantly: Anthropic wants to control what people do with AI—they block companies they don't like from using their coding product (including us), they want to write the rules themselves for what people can and can't use AI for, and now they also want to tell other companies what their business models can be.
We are committed to broad, democratic decision making in addition to access. We are also committed to building the most resilient ecosystem for advanced AI. We care a great deal about safe, broadly beneficial AGI, and we know the only way to get there is to work with the world to prepare.
One authoritarian company won't get us there on their own, to say nothing of the other obvious risks. It is a dark path.
As for our Super Bowl ad: it’s about builders, and how anyone can now build anything.
We are enjoying watching so many people switch to Codex. There have now been 500,000 app downloads since launch on Monday, and we think builders are really going to love what’s coming in the next few weeks. I believe Codex is going to win.
We will continue to work hard to make even more intelligence available for lower and lower prices to our users.
This time belongs to the builders, not the people who want to control them.
"Ads are coming to AI, But not to Claude"
어제 슈퍼볼 광고에 나오기 시작한 앤트로픽 클로드의 캠페인 시리즈.
1. 엄마와 소통을 덜 잘하려면 어떻게 해야 하느냐고 묻는 남자.
대답하는 여성은 잘 나가다가 갑자기 '연상 여성을 만날 수 있는 데이팅 사이트'를 알려준다.
그러면서 마무리 질문.
"(그 사이트에 사용할 수 있는) 프로필을 만들어 줄까요?"
2. 사업 아이템이 어떠냐고 묻는 여성.
하나, 둘 설명하던 여성은 세 번째에서 사업자용 대출 상품을 소개한다.
그리면서 마무리 질문.
"간단히 신용 조회를 해 드릴까요?"
3. 자기 에세이가 뭐가 문제인지 묻는 학생.
에세이가 괜찮다며 격려해주던 교수는 에세이 마감을 기억할 수 있는 액세서리를 소개한다.
그러면서 마무리 제안.
"오늘 주문하면 개인 맞춤 각인은 무료입니다".
4. 빨리 식스팩을 만들고 싶다는 남자.
맞춤형 계획을 세워주겠다고 신체 사이즈를 물은 트레이너는 키 높이 깔창을 소개한다.
그러면서 마무리 제안.
"(이) 할인 코드를 입력하시면 큰 할인을 받을 수 있습니다".
오랜만에 빵 터진 광고.
누가 봐도 광고 모델 도입을 선언한 오픈AI를 겨냥.
앤트로픽은 오늘 클로드는 '광고를 도입하지 않을 것'이라고 선언하는 글도 올림.
광고 링크는 댓글에.
1. How can I communicate better with my mom?
youtube.com/watch?v=FBSam25u…
2. What do you think of my business idea?
youtube.com/watch?v=De-_wQpK…
3. Is my essay making a clear argument?
youtube.com/watch?v=3sVD3aG_…
4. Can I get a six pack quickly?
youtube.com/watch?v=kQRu7DdT…
그리고, 오늘 발표한 '무 광고 클로드' 선언문
anthropic.com/news/claude-is…
제목부터 '루머'라고 써 있듯이, 시장에서 이런 내러티브를 만들고 싶어하는구나 정도로 참고하면 좋을 듯.
國泰海港 리포트는 중국 관련 공급망 서술에 대해서는 비교적 신뢰할만 하지만, 미국 기업의 내부 사정에 대해 너무 확정을 강조하는 경향이 있음. 아무래도 자국(중국) 기업에 유리한 내러티브를 만드는 것이 이들의 방향성이기 때문.
글을 읽어보면 어느 정도 맞는 이야기(HBM의 현재 문제, OCS, CXL, 메모리 폴링 등)도 있지만, 어떤 이야기는 과잉 단정하는 구간(HBM 제거, 구체적인 시점과 비율 명시 등)이 있다는 걸 염두에 두고 노이스와 시그널을 구분할 필요 있음.
단, 시장이 갈증을 느끼는 포인트가 무엇이라는 걸 알 수 있다는 점은, 이런 루머 리포트가 가진 장점이기도 함.

Rumor: Starting with TPU v8, Google will no longer use HBM?
The incident was triggered by the global capacity shortage of HBM, which will be unable to meet AI growth demands over the next 2 to 3 years. At the same time, traditional HBM is limited by its design of being fixed on the motherboard, resulting in a capacity ceiling.
Accordingly, Google will develop a new solution to be launched in 2027. The physical form involves removing HBM and establishing independent DRAM memory cabinets (containing 16–32 Trays), dynamically allocating memory through photonic technology.
This technology deconstructs the originally single and simple HBM component into three parts:
- Transport Layer: Employs all-optical interconnects, ensuring cross-cabinet communication efficiency through OCS (Optical Circuit Switching) and customized CXL protocols. The CPUs, GPUs, and memory modules of the memory pool share a single set of protocols.
- Storage Layer: Utilizes large-scale DRAM arrays to replace HBM, significantly increasing the addressing space. The memory corresponding to a single TPU can leap from 192GB/256GB to 512GB or even above 768GB.
- Control Layer: Adds dedicated memory-side CPU servers for management.
Compared to the native "TPU+HBM" direct connection, this "three-in-one" split-combination solution results in a calculation efficiency loss of less than 2%.
Regarding this technology, first is OCS, which satisfies high-speed switching in an all-optical environment and achieves bandwidth and latency close to direct connections with HBM or silicon photonic HBM. Traditional Ethernet (via copper) typically has a latency of over 200 nanoseconds, while using an OCS all-optical switching network can reduce latency to below 100 nanoseconds, which is why it is important.
Second, in this architecture, there is a dual-side CPU architecture (Tier-1 and Tier-2 CPUs):
Tier-1 CPU (TPU side): Located on the TPU motherboard, primarily responsible for interconnect communication between TPUs.
Tier-2 CPU (Memory pool side): Most likely deployed on the memory server (DRAM server) side, specifically responsible for communication coordination between TPUs and the distributed memory addressing space.
The Tier-2 CPU is deployed independently because, logically, the original TPU motherboard CPU could still read the memory pool, but using the old CPU would involve complex protocol conversions (such as translation between PCIe signals and CXL-like protocols), creating efficiency bottlenecks.
Third, the interface is completed directly at the chip level through a "photonic packaging interface." This method is similar to CPO (Co-Packaged Optics) technology, integrating optical interfaces directly within the package of chips like the CPU/TPU, replacing traditional external optical modules. The first supplier contacted during the solution design stage was Lightmatter, with multiple suppliers to follow.
This solution, which removes HBM and changes it to an external DRAM memory pool, actually converts what was originally ultra-high-frequency motherboard-level access into "cross-cabinet access." Theoretically, this would generate huge latency and efficiency losses. However, this is not the case. Specifically, complex electrical/optical conversions exist between chips, hosts, and ring networks; these hardware-level protocol conversions and settings generate significant hidden overhead invisible to users. After adopting the DRAM memory pool solution, although CXL translation is introduced, many cumbersome hardware protocol conversion steps from the original architecture are removed.
If HBM prices drop and performance improves due to capacity expansion by manufacturers like Samsung and Hynix over the next two years, Google is unlikely to return to the HBM solution due to cost considerations. Google does not believe that upstream manufacturers like Hynix, Samsung, and Micron will subvert their own main product line pricing or mass production strategies to accommodate one or two major customers. They might release some profit margin, but they will not cooperate to an extreme degree.
This solution also reduces reliance on CoWoS because HBM is no longer needed. At the same time, the HBM chips originally on the silicon interposer substrate occupied a large area; after removing HBM, the saved CoWoS area can be entirely given to the TPU's Compute Core. Thus, within the same physical dimensions, a TPU chip with stronger performance and a larger area can be made, no longer restricted by the physical size of HBM. Regarding memory, the V7 generation had a single HBM capacity of about 192GB, and V8A is about 256GB, but through memory pooling, the memory per TPU can easily double to 512GB or even reach 768GB or more.
The solution is expected to be implemented next year, with the final route determined before March 5. The initial deployment ratio is about 30%, with 100% replacement expected to be achieved in 3 years.
Sector Beneficiaries:
- OCS (Optical Engine): Lightmatter, as the primary supplier, provides photonic packaging interfaces, integrating optical interfaces within the chip package to replace external modules.
- CXL-like: Requires CXL-like chips (MXC chips) to achieve the interconnect between TPUs and the memory pool, costing $100 per chip. One chip manages two channels for two 256GB memory modules, matching the TPU and memory side synchronously. If it is 512GB, two MXC chips are needed; for 768GB, four chips.
- DRAM Modules: The quantity of GBs increases significantly.
- CPU: Each memory Tray needs to be equipped with a CPU for scheduling; high performance is not required here, and ARM-based CPUs can be used.
- PCB: Independent DRAM cabinets require large, multi-layer PCBs to carry a large number of DIMM slots.
Source: 国泰海通 (Guotai Haitong)