

Associate Prof. of Statistics & Machine Learning National University of Singapore (NUS)
Singapore
Joined April 2009
- Tweets363
- Following1.1K
- Followers1.1K
- Likes2.7K





One of the final projects for my #optimization class is to investigate whether one can make progress on the square packing problem! I let a GPU go brrr overnight and it found back 6 times the best currently known N=17 packing.. The last row are packings that are about 0.05% worse


Alex Thiery retweeted

There's a really wonderful lecture series on YouTube of McKays information theory. It makes it really easy to dive in! youtube.com/playlist?list=PL…

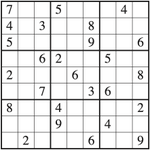
Lots of fun learning how to use @claudeai code, it took ~100 steps & several agents to build a human-like solution to that (very difficult) sudoku. Anybody managed to do that for chess tactics?


Alex Thiery retweeted

🔥 WANTED: Student Researcher to join me,@ValentinDeBort1,@thjashin,@liwenliang,@ArthurGretton in DeepMind London.
You'll be working on Multimodal Diffusions for science. Apply here google.com/about/careers/app…
I'm teaching Bayesian Optimization for the first time this semester, so finally had to implement it myself. Fun stuff, with a few gotchas along the way!
Alex Thiery retweeted

Art B. Owen. [math.ST]. Better bootstrap t confidence intervals for the mean. arxiv.org/abs/2508.10083
Alex Thiery retweeted

I'm looking for talented and ambitious PhD students to join me at Nanyang Technological University Singapore to work on safe and robust AI systems!
Full scholarships covering tuition and a stipend are available, and are open to local and international students alike.
Alex Thiery retweeted

Scalable Monte Carlo for Bayesian Learning by Professor Paul Fearnhead, Dr Christopher Nemeth, Professor Chris J. Oates and Dr Chris Sherlock
A clear and intuitive introduction to advanced topics in Markov chain Monte Carlo, with a focus on scalability.
📚 cup.org/4l42JW8

Alex Thiery retweeted

Why do we keep sampling from the same distribution the model was trained on?
We rethink this old paradigm by introducing Feynman-Kac Correctors (FKCs) – a flexible framework for controlling the distribution of samples at inference time in diffusion models!
Without re-training or fine-tuning (just with the raw power of math), we demonstrate how to sample from:
1. product of densities (e.g. for conditioning generations on several things)
2. annealed density (invaluable property for diffusion-based samplers)
3. geometric-average of densities (to bridge the gap between classifier-free guidance and the common intuition)
4. reward-tilted density (easy to get within our framework, but we focus on other cases that don't require an external reward function)
@martoskreto prepared beautiful animations for you in the thread below, or you can go directly to check
- Paper: arxiv.org/abs/2503.02819
- Code: github.com/martaskrt/fkc-dif…
- Educational example: colab.research.google.com/dr…


🧵(1/6) Delighted to share our @icmlconf 2025 spotlight paper: the Feynman-Kac Correctors (FKCs) in Diffusion
Picture this: it’s inference time and we want to generate new samples from our diffusion model. But we don’t want to just copy the training data – we may want to sample from an annealed distribution (e.g. to find modes), or combine two experts by sampling from the product of conditional densities (e.g. to design molecules that bind to two protein pockets).
FKCs let us do this!✨But how? We explain in the 🧵 below.
(work with an amazing amazing team -- @tara_aksa @OhanesianViktor Roberto Bondesan @A_Aspuru_Guzik @ArnaudDoucet1 @brekelmaniac @AlexanderTong7 and @k_neklyudov)
📃arxiv.org/abs/2503.02819
🧑💻github.com/martaskrt/fkc-dif…
Alex Thiery retweeted

Lecture notes: "Data-driven approaches to inverse problems" (by Carola-Bibiane Schönlieb, Zakhar Shumaylov): arxiv.org/abs/2506.11732
[Comments:Notes from Machine Learning: From Data to Mathematical Understanding (CIME 2023)]

Geodesic path v.s. KL(pi, target) gradient flow under the Fisher-Rao Metric: can you tell which is which?
Interesting paper:
"Sequential Monte Carlo approximations of Wasserstein--Fisher--Rao gradient flows"
By: Francesca Crucinio & Sahani Pathiraja
arxiv.org/abs/2506.05905
One #postdoc position is still available at the National University of Singapore @NUSingapore to work on sampling, high-dimensional data-assimilation, and diffusion/flow models. Applications are open until the end of January. Details:
alexxthiery.github.io/jobs/2…
Variational approximation with Gaussian mixtures is looking cute! So here it's just gradient descent on K(q||p) for optimising the mixtures means & covariances & weights...

Gaussian approximation of a target distribution: mean-field versus full-covariance! Below shows a simple gradient descent on KL(q||p)
"Doubly Stochastic Variational Bayes for non-Conjugate Inference" by Titsias, Michalis, and Miguel Lázaro-Gredilla
proceedings.mlr.press/v32/ti…