

CS PhD student @UofT and @VectorInst. Ex research intern @Apple ML Research. Interested in deep learning theory and generative modeling.
Toronto, Ontario
Joined October 2024
- Tweets74
- Following277
- Followers457
- Likes619




Alireza Mousavi retweeted

Standard PG analysis requires "all-iterate coverage" ie bounded π*/π_t ∀𝐭. What if we only assume it at 𝐭=𝟎 (eg base model has nontrivial success rate on all prompts)?
Ans: 𝐞𝐱𝐩𝐨𝐧𝐞𝐧𝐭𝐢𝐚𝐥 complexity due to "coverage collapse". arxiv.org/abs/2611.14467

Alireza Mousavi retweeted

We have now crossed the threshold where developing theory has become orders of magnitude faster. It is now possible to rapidly develop theory that can drive AI research, not just explain it post-hoc.
Alireza Mousavi retweeted

🚀 🚀 🚀 Excited to share our new paper:
Remember to be Curious: Episodic Context and Persistent Worlds for 3D Exploration
What does it take for an agent to stay curious in a 3D world?
The answer is memory.
🌐 Project: recuriosity.github.io/
📄 Paper: arxiv.org/abs/2605.22814
💻 Code: github.com/recuriosity/recur…
Alireza Mousavi retweeted

Attention and MLP matrices can store as much knowledge as # params, but in practice, finite samples/compute and long context noise can further limit this capacity. We characterize these trade-offs in a needle-in-a-haystack model.
#ICLR2026 poster Thurs, led by @nurimertvural45


Alireza Mousavi retweeted
Excited to share @YaldaForoutan and @pekzta4's work on robust 3D reconstruction from 360 captures!
Casual 360 video capture gives you the coverage you need for calibration and reconstruction; FullCircle makes it hassle-free!
No more wrestling with stitching artifacts or floaters from the camera operator. Data and code are released, enjoy!

📢📢📢 Introducing "FullCircle: Effortless 3D Reconstruction from Casual 360° Captures"
TL;DR: 10x faster casual capture with clean reconstructions
Homepage: theialab.github.io/fullcircl…
Code: github.com/theialab/fullcirc…
arXiv: arxiv.org/abs/2603.22572
Led by Yalda Foroutan & Ipek Oztas
Alireza Mousavi retweeted

New paper 🥳 RL relies a lot on an agent’s capability to explore. Our strategy-guided exploration makes the agent find new solutions more efficiently. It learns faster, and in some environments its Pass@1 surpasses the base model’s Pass@128. 🧵1/6
📄 arxiv.org/abs/2603.02045

Alireza Mousavi retweeted

Masked Diffusion LMs (MDLMs) are the most exciting paradigm shift in AR generation because they can decode in parallel, infill, and self-correct.
But they are bottlenecked by the transformer's quadratic attention, making throughput fall apart for long contexts.
We offer a simple solution. Introducing DiffuMamba: first diffusion LM with a bidirectional Mamba backbone. Better quality. Up to 8.2x faster.
🧵1/N
Alireza Mousavi retweeted

Fantastic workshop on High-Dimensional Learning Dynamics at BIRS. All talks here:
birs.ca/events/2026/5-day-wo…
Alireza Mousavi retweeted

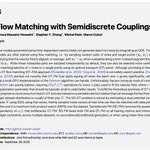
- Sat Dec 6 @ SPIGM workshop, On Fitting Flow Models with Large Sinkhorn Couplings, work with @alirezamh_ , Michal Klein, Marco Cuturi 4/4

Alireza Mousavi retweeted
Our research team is hiring PhD interns 🍏 Spend your next summer in Paris and explore the next frontiers of LLMs for uncertainty quantification, calibration, RL and post-training, and Bayesian experimental design.
Details & Application ➡️ jobs.apple.com/en-my/details…
Alireza Mousavi retweeted

From Information to Generative Exponent: Learning Rate Induces Phase Transitions in SGD. arxiv.org/abs/2510.21020

Alireza Mousavi retweeted
LLMs are currently this one big parameter block that stores all sort of facts. In our new preprint, we add context-specific memory parameters to the model, and pretrain the model along with a big bank of memories.
📑 arxiv.org/abs/2510.02375
Thread 👇

Alireza Mousavi retweeted
Many treat uncertainty = a number. At Apple, we're rethinking this: LLMs should output strings that reveal all information of their internal distributions. We find Reasoning, SFT, CoT can't do it -yet. To get there, we introduce the SelfReflect benchmark.
arxiv.org/abs/2505.20295

Alireza Mousavi retweeted

Scaling laws don’t just show up in test error — they leave fingerprints in the weight spectrum.
In the feature learning regime, we map this connection: phase diagrams of scaling exponents <-> spectral signatures of trained weights. The paper is: arxiv.org/abs/2509.24882

Alireza Mousavi retweeted

sharing a new paper w Peter Bartlett, @jasondeanlee, @ShamKakade6, Bin Yu
ppl talking about implicit regularization, but how good is it? We show its surprisingly effective, that GD dominates ridge for all linear regression, w/ more cool stuff on GD vs SGD
arxiv.org/abs/2509.17251

Alireza Mousavi retweeted

Super excited to share l3m 🚀, a library for training large multimodal models, which we used to build AIM and AIMv2. Massive thanks to @alaa_nouby @DonkeyShot21 Michal Klein @MustafaShukor1 @jmsusskind and many others.

Alireza Mousavi retweeted

Our paper got accepted at NeurIPS. Time to plan my bike trip!

'Let Me Think! A Long Chain-of-Thought Can Be Worth Exponentially Many Short Ones'
@parsamirta, @ezra_edelman, Samy Jelassi, @EranMalach, Enric Boix-Adsera
doi.org/10.48550/arXiv.2505.…
(17/21)

Alireza Mousavi retweeted

@NeurIPSConf, why take the option to provide figures in the rebuttals away from the authors during the rebuttal period? Grounding the discussion in hard evidential data (like plots) makes resolving disagreements much easier for both the authors and the reviewers.
Left: NeurIPS author instructions from yesterday, Right: Same page today.


Alireza Mousavi retweeted
New work arxiv.org/abs/2506.05500 on learning multi-index models with @alex_damian_ and Joan Bruna. Multi-index are of the form y= g(Ux), where U=r by d maps from d dimension to r dimension and d>>r. g is an arbitrary function. Examples of multi-index models are any neural net with first hidden layer that is width r.
Our new paper proposes a new spectral estimator that attains optimal dimension dependency for recovering span(U). We define the generative leap exponent that governs the difficulty of learning and show both upper and lower bounds of d^{k/2} , where k is the generative leap exponent. This gives optimal results for learning several families:
1. Deep ReLU networks with bias (generalizing the result of Chen, Meka, Klivans from bias-less ReLU networks)
2. low-rank polynomials where g is a polynomial (Chen and Meka).
3. Almost all deep neural networks with first hidden layer of width r.
4. Sparse Gaussian parity
