




amrita retweeted

Meet NVIDIA Nemotron 3.5 Transcribe 🎙️
An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint.
Watch it keep track of who said what when everyone’s talking at once.
1/ 🧵
amrita retweeted

Excited to share that our work DyaPlex has been accepted to #NeurIPS2026! 🎉
Listen, speak, and gesture—all at once. DyaPlex jointly perceives and generates speech & body motion, enabling AI agents and robots to engage in natural, full-duplex interaction with humans.
amrita retweeted

We will present DyaPlex at #NeurIPS2026, a full-duplex human-robot interaction model, which allows AI (both agents and robots) to listen, speak, perceive partner motion, and generate synchronized motion in full-duplex dyadic interaction. research.nvidia.com/labs/amr…
amrita retweeted

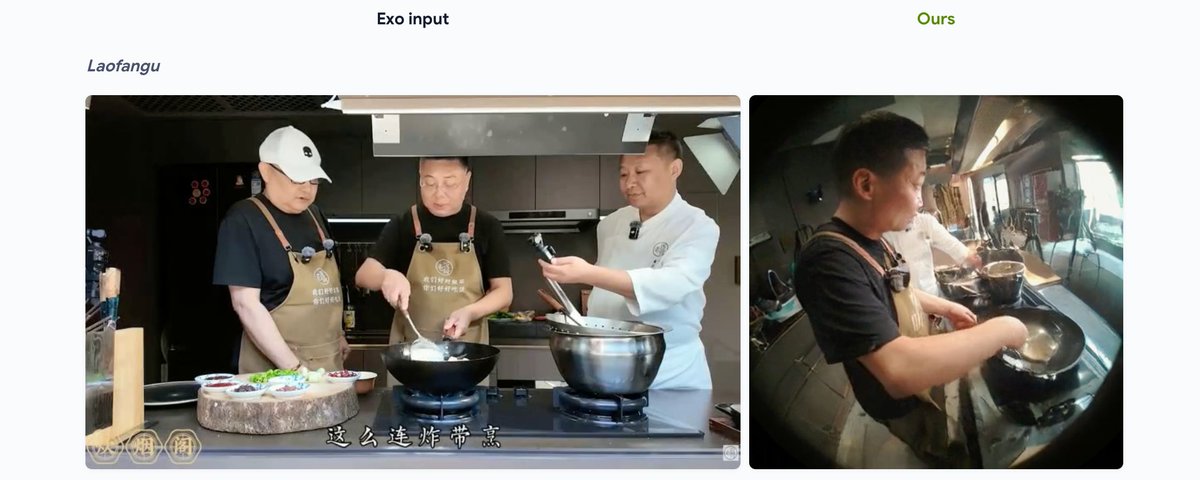
Grounded-Exo2Ego accepted to NeurIPS 2026 🎉 The single biggest limiting factor of Robotics is data. Our vision is to turn the ocean of long, in-the-wild, exocentric human videos on the internet into egocentric videos that robots can learn from.
amrita retweeted

The latest realtime multi-speaker diarization model from NVIDIA suddenly lets you build voice powered party games with a single microphone! Also voice agents can now have multi-party conversations easily. Make cool stuff with it! huggingface.co/blog/nvidia/n…


NVIDIA released a fast speaker-labeling model today: Nemotron 3 Diarization. Like all of the Nemotron family from @NVIDIA_AI, this is an open weights model, so you can grab the weights from @huggingface and use the model in the cloud or on your local device.
Nemotron 3 Diarization is a useful building block for voice agents and realtime AI applications that need to handle speech from multiple people at the same time. It handles overlapping speech well, can identify up to eight speakers, and pairs with any transcription model you're using in your multi-modal pipelines.
@jonptaylor built a demo (code below) and recorded a technical deep-dive showing how to use this diarization model together with a speech-to-text model.
Jon's code also uses Jev for super-accurate confirmation of critical voice input in a noisy/multi-speaker environment.
amrita retweeted

1/ The future of voice AI is one where people spend hours a day interacting with models.
For that to happen, models need to be natural, engaging, and compelling enough that people want to keep talking to them. To understand which models people actually prefer interacting with, we need to ask humans.
We just released DAI-S2S-ST, our single-turn speech-to-speech human preference leaderboard, built on 153K comparative human ratings across 12 evaluation dimensions.
This is a first step toward measuring what it feels like to interact with voice models and what drives people’s preferences.
research.withdavid.ai/blog/s…

amrita retweeted

NVIDIA Research is looking for 2027 PhD interns! If you are interested in 4D reconstruction and/or world models, check out research.nvidia.com/labs/amr… and send me an email/DM!

amrita retweeted
Our team at NVIDIA @NVIDIAAI is hiring a research intern for 2027. Please send me an email if you are interested in working on technology to enable Interactive Physical AI (research.nvidia.com/labs/amr…), especially human #robot-interaction (HRI).
linkedin.com/posts/shalini-d…
amrita retweeted

How can 4D reconstruction leverage generative priors for unseen dynamics and regions, while respecting the constraints of projective geometry?
Introducing World from Motion: a generative method that reconstructs freely-renderable dynamic 3D Gaussians from monocular video. 🧵🔥
amrita retweeted

Xueyan Zou @xyz2maureen's talk on "Actionable World Representation" happens now at 4DDT 2026 workshop #CVPR2026

amrita retweeted
@GordonWetzstein's talk on "From World Models to World Agents" starts now at 4DDT 2026 workshop #CVPR2026

amrita retweeted
@frncswllms is presenting "fVDB: A Framework for Sparse, Large-Scale and High-Performance Spatial Intelligence" at 4DDT 2026 workshop #CVPR2026

amrita retweeted
@jhugestar is sharing his insights on "Teaching Robots Our Everyday Labor: From 3D Data and 2D Video to Self-Learning" at 4DDT 2026 workshop #CVPR2026

amrita retweeted
@KaterinaFragiad is giving the keynote talk on "Learning Persistent 4D World Models from Video" at 4DDT 2026 workshop #CVPR2026


amrita retweeted

Really appreciate the opportunity to share our new direction on 4D Digital Twins 🌍✨
Actionable World Representation is a research direction initiated during my postdoc, and I’m excited to develop it as a new stream of work in my lab.
I’ll be presenting this work virtually in CVPR2026 today from 4:30–5:15 PM in Room 2C. Looking forward to sharing and discussing! 🚀
#CVPR2026


very excited for the 4D Digital Twins workshop happening tomorrow #CVPR2026 ! we have an amazing set of speakers talking about 4D real-to-sim-to-real challenges🦾
🗓️ Thurs June 4 · 1:00 – 6:00 PM
📍 Mile High 2C
🔗 research.nvidia.com/labs/amr…
very excited for the 4D Digital Twins workshop happening tomorrow #CVPR2026 ! we have an amazing set of speakers talking about 4D real-to-sim-to-real challenges🦾
🗓️ Thurs June 4 · 1:00 – 6:00 PM
📍 Mile High 2C
🔗 research.nvidia.com/labs/amr…
happening tomorrow! see you all there!

🤖 At #CVPR2026 next week? Join the 1st Interactive Physical AI Workshop (IPA 2026) — embodied social agents, full-duplex multimodal conversation & lifelike robots and avatars and more!
🗓️ Wed June 3 · 8:25 AM–1:00 PM MDT
📍 Rooms 210/212
Keynotes:
• Alexander Richard (Meta) — Embodied Social Agents in XR
• Maja Matarić (USC / Google DeepMind) — Human-Centered AI & Robotics
• Agon Serifi (Disney Research) — From Human Motion to Robot Behavior
🔗 research.nvidia.com/labs/amr…
@NVIDIAAI @swookpark @shalinidemello @mct1224 @amritamaz @lmathur_

3
257

If you have an interaction model you'd like to evaluate with VideoFDB, check out the data on HuggingFace and reach out with your results!
🏆 [Project page + leaderboard]: research.nvidia.com/labs/amr…
📄 [arXiv]: arxiv.org/abs/2605.30256
🤗 [HuggingFace]: huggingface.co/datasets/nvid…

1
2
61
finally, this was a great joint work with @swookpark @rjrshr @mct1224 @luminohope @shalinidemello and others, and a huge thanks to @withdavidai for helping us collect the dataset!
1
71