

Local AI Enthusiast & Builder | try my local voice stack https://teapawt.net/t.co/jex1g5flDL
Austria
Joined February 2024
- Tweets903
- Following262
- Followers113
- Likes8.1K




Weil mir der Klang zu blechern war, hab ich noch einen Vocoder (Vocos) drangehängt. Die Zielgröße von ca 21 MB hab ich damit nicht erreicht (jetzt rund 75 MB) aber es klingt etwas besser.
Wunder darf man trotzdem keine erwarten, bei der Größe. Was mir aber wirklich gut gefällt ist die Betonung.
1
1
393
Das Modell kommt als Alternative zu Phonon in meinen Flash-Voice-Stack. Der große Vorteil: Apache 2.0. Das deutsche Phonon Modell steht unter CC BY-NC 4.0 und ist damit nur für nicht kommerzielle Nutzung freigegeben.
Offen unter Apache 2.0:
Github: github.com/ViktorsGitUser/fl…
Huggingface: huggingface.co/apptor/apptor…
Danke an @n4ze3m

2
9
382
😭


Wir verlosen eine NVIDIA GeForce RTX 5090 im individuellen Hogwarts Legacy-Design, um den offiziellen Release mit DLSS 5 zu feiern 🪄
So machst du mit:
🟢 Teile diesen Beitrag
🟢 Kommentiere mit #RTXON

88
Finally my working day is over and I can test the new Strata version with Unsloths new v3.1 quant.
What kind of magic is this?
140 tokens per second for coding 🔥🔥🔥


Strata 0.2.11 is now out! 👀
- Supports new Unsloth Qwen3.8-Flash-Next quants
- Layer splitting is now allowed for all configurations
- Performance increase
- App & Terminal improvements
More at: github.com/Niko1221/Strata/r…


Wie findet ihr meinen neuesten Werbeclip?
Komplett lokal erstellt mit einer 5060ti 16gb in meinem Medienstudio.
Regie: Claude Opus 5.5
1
124

Apptor retweeted

you don’t believe me but it’s already happening, the rug will slowly get pulled
use them whilst you can, and create a harness to protect yourself for the future
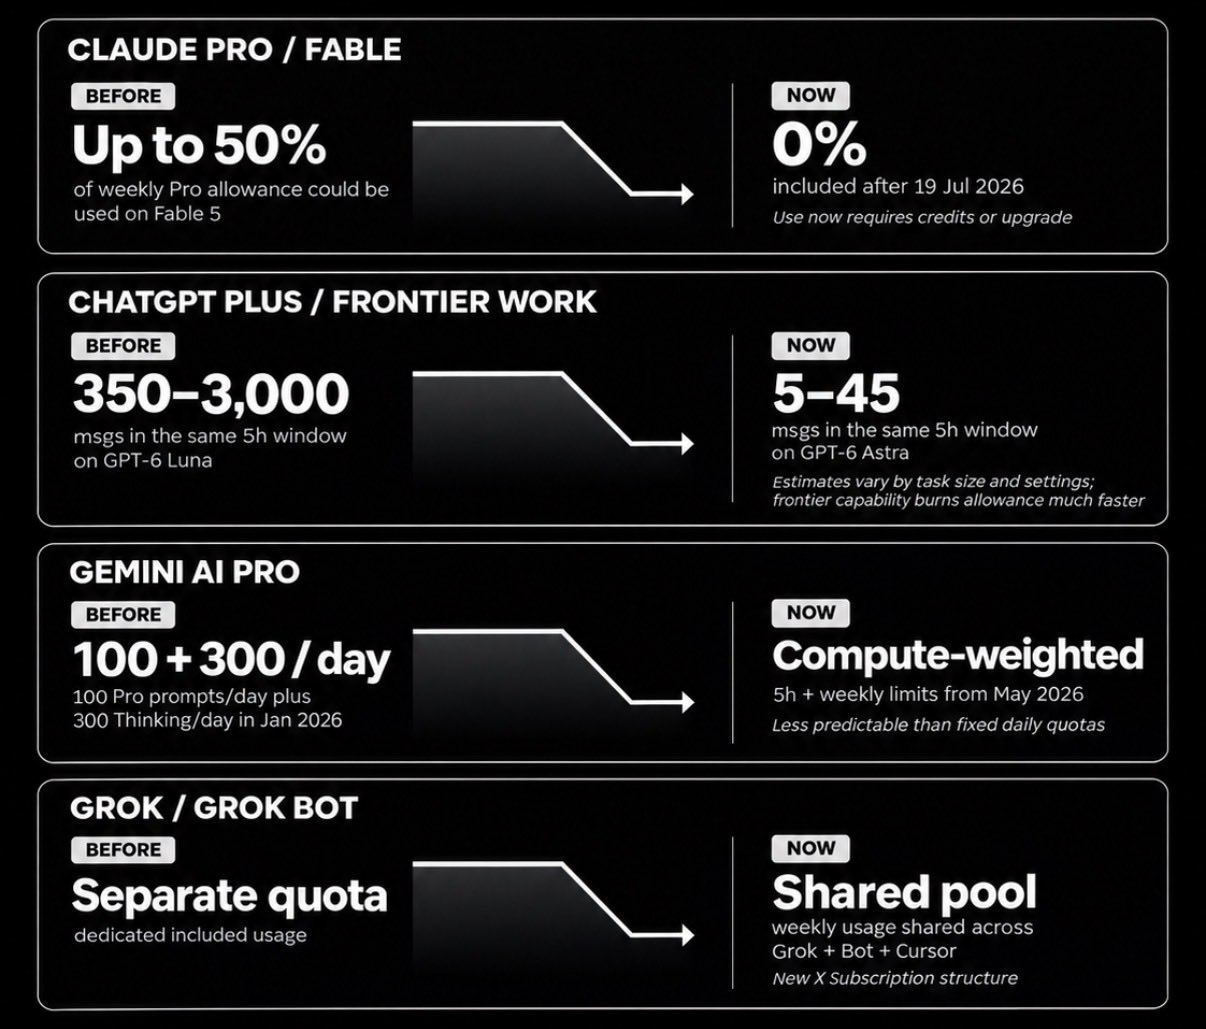
here’s how you’re actually going to become a part of the permanent underclass:
> you use ai
> you use all frontier models
> you become productive on them
> you become reliant on these models
> you use their agents and workflows
> you ignore open source models
> you ignore open source agents
the models become so insanely good that you can’t imagine life without it now.
& then the frontier models put the prices up and up and up and up and up and up and up and you’re priced out with none of your workflows and memory saved locally.
that’s how you become a part of the permanent underclass.

what the fuck is going on with claude session usage? 10% of the session are already used with reading the context to proceed working.
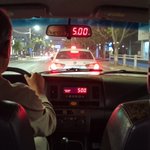
it feels like driving taxi in vienna where you get in and the taximeter already shows 5 Euros

1
1
51
Strata is amazing!
I know thats common knowledge but it’s so amazing to see 90 tps with Qwen FN on my 3090 with old 64gb ram.

1
99
I saved 5 Gb vram by using Phonon as TTS for my local AI Voice assistant .
Yesterday Gradium a French based company released their new speech model and thanks to X, I tried it right away.
It’s amazing how good it is given its tiny size.
I included it in my speech setup as an option. If you need Apache 2.0 stick with Qwen, otherwise save vram and go for it.
github.com/ViktorsGitUser/fl…
59
Apptor retweeted
Why is it so huge?
I used Qwen TTS till yesterday, which is around 5 GB for my personal local assistant.
Since yesterday I use Phonon which is only 80 Megabyte and runs on CPU!
Stille have to push it to my voice assistant repo:
teapawt.net/apptor_at/status/21103…

Making speech recognition feel like a natural conversation is not trivial. The system has to suppress its own voice, distinguish noise from speech, duck its own volume when it hears an interruption and keep listening as long as the user is still talking.
It took a bit of tuning, but I finally found a setup that works well – and I want to share it.
github.com/ViktorsGitUser/fl…

Making speech recognition feel like a natural conversation is not trivial. The system has to suppress its own voice, distinguish noise from speech, duck its own volume when it hears an interruption and keep listening as long as the user is still talking.
It took a bit of tuning, but I finally found a setup that works well – and I want to share it.
github.com/ViktorsGitUser/fl…
I love talking to AI models while commuting. But I don't like that everything is being sent to the cloud.
So I spent some time building a setup that feels like the big online voice modes but runs completely on my hardware and uses my local LLM.
Meet flash-voice. Open source, Apache 2.0.
It is meant as a starting point for everyone who wants a full voice mode for their own AI. Plug in any OpenAI-compatible endpoint (Ollama, llama.cpp, vLLM, LM Studio …) and just talk to it.
The stack:
> Whisper for speech recognition
> Qwen3-TTS for speech
> Silero VAD to tell noise from speech
> Clef to decide if my sentence is finished, or if I really want to interrupt and it was not just a "mhm"
& your local LLM
What it does:
> you ask, it answers sentence by sentence
> you can interrupt it while it speaks, it gets quieter first and stops when you really mean it
> it waits when you say "uhm …" and answers right away when your thought is finished
> you can clone voices, 10–20 seconds of a recording is enough (only with consent of course)
Total VRAM is around 14 GB, so not little. But I wanted the best performance. In my setup one GPU handles the voice stack, the other one the LLM (thanks to Strata :)).
It also works with around 7 GB without Clef. Then simple rules take over, and it notices less well when you are done talking.
Let me know if you like it. Link to repo below.

6
4
291
For the local AI community on X.
I love talking to AI models while commuting. It is a good use of my time since there is always something to learn.
But I don´t like that everything is being sent to the cloud. So I spent some time to create a setup that is comparable to the big online services but runs completely on my hardware and uses my local LLM.
Meet flash-voice.
The stack consists of:
> Whisper for speech recognition
> Qwen3-TTS for speech
> Silero VAD to distinguish noise and speech
> Clef to decide if my sentence is finished
& my local llm
Total vram consumption is around 14 gb, so not little. But it works and on my dual 5060 setup. One GPU handles this stack and the other the LLM.
You can ask, listen and interupt the model while speaking.
Let me know if you like it.
github.com/ViktorsGitUser/fl…

3
2
113