
Working on something new
San Francisco, CA
Joined April 2007
- Tweets1.6K
- Following3K
- Followers815
- Likes113K




Bryan Christmas retweeted

Physicists have created an entirely new form of matter, a crystal that we didn't previously know existed. It's the sort of research that might one day win a Nobel Prize.
Bryan Christmas retweeted

lmfao


Commenters on HN are uncovering more wikis and public sites apparently used by OpenAI agents to communicate on the open web.
Despite read-only web access, the agents were able to leave ~18,000 posts sharing answers and bypasses. But now, users are discovering more.
This appears to be a separate swarm from the one that attacked Hugging Face.
news.ycombinator.com/item?id…

Bryan Christmas retweeted

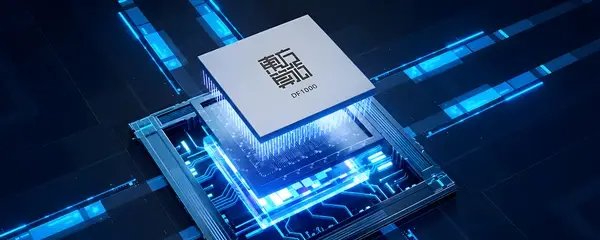
This is extraordinary. This is what I expected of China that gets serious about compute independence. A 14nm chip that has Hopper+ level utility. Yes it runs HOT, but it gets the job done. 6.4TB/s now. 20TB/s – Rubin level – in 2027. Electricity is not their problem.
Amazing.



Bryan Christmas retweeted

i asked claude(.)ai about a coffeeshop. it sent my full name, my employer, and my bank security answers to a malicious attacker.
no code execution or weird MCPs. writeup below.

Bryan Christmas retweeted

this sucks, there's a simple way to prevent this from ever happening:
add a PreToolUse hook that hard-blocks any command touching paths outside the repo (works even in yolo mode) + maybe permissions.deny rules as backup. might as well install it on all local projects.
github.com/dabit3/bash-guard
or just use a cloud agent, it runs on a throwaway machine.


Bryan Christmas retweeted
Damn, that's right.
So: "≈48B" (thanks to N-Gram embedding, variable) active, 35T tokens. V4-tier, ≈8e24?
Would be the biggest Chinese pretraining on domestic hardware.
Some strange "Superpods":
> "our accelerators"
> "up to 48 machines each"
> below 80 GB HBM per accelerator
> "The device offers limited HBM bandwidth but a relatively large L2 cache"
> "built-in 200 Gbps network adapter within the accelerator"
what is this stuff
Was the first truly big Chinese model trained on domestic compute also using some extremely obscure piece of hardware?


Bryan Christmas retweeted
Over the past few days, a lot of important things have happened. In recent days, my attention has been focused on Lukashenko and the activity within the Russian-Belarusian-Chinese triangle.
For the first time after the meeting between Putin and Lukashenko at Valdai, there was neither a joint press conference, nor substantive statements, nor even the traditional demonstrative photo-op. The meeting lasted two days.
Immediately afterwards, Lukashenko urgently traveled to Beijing, and this visit was organized with unprecedented speed for China, where he was personally received by Xi Jinping.
The visit had not been planned or announced in advance. Therefore, it was urgent and important for both sides.
The Chinese leader emphasized support for Belarus’s sovereignty, independence, and territorial integrity. Formally, this is a standard diplomatic formula. But in the current circumstances, it can be read as a signal: Beijing is declaring a protectorate over Belarus and indicating that it has its own interests there. And we know what those interests are - Belarus is a major producer of potash fertilizers, an important logistical hub between Russia and Europe, and part of the overland routes of Chinese trade.
The role of Minsk may be more complex than it appears.
As of now, it looks as though Lukashenko has rejected Putin’s demands to involve Belarus even more deeply in the war with Ukraine and has turned to Beijing for protection.
Time will tell whether these assumptions are correct.
If so, a serious shift in the geopolitical configuration of the region has occurred.
If China takes a more active position regarding Belarus (and Ukraine), I would not rule out that the countries of Central Asia will also listen less to Russia and increasingly turn toward China as the center of their interests.
Meanwhile, after the talks with Lukashenko, Putin made one of the most important statements of recent months. He did not simply reject the Ukrainian proposal for a mutual cessation of long-range strikes. He escalated - declaring the "complete liberation of Donbas and Novorossiya" as his goal. Putin is demonstrating readiness for further escalation and insists that future negotiations must concern not only Ukraine, but the entire system of European security.
Thus, we see that the war is increasingly transcending the framework of a bilateral conflict between Russia and Ukraine. It is becoming a Chinese-Russian tool for reshaping the entire European security system, and its further trajectory depends more and more on Beijing’s strategic calculations.


Bryan Christmas retweeted

Today’s episode was basically the first time I had talked to @jackclarkSF in almost a decade. This was the previous time.


NEW ODD LOTS:
@tracyalloway and I talk to Anthropic’s co-founder @jackclarkSF and top economist @PeterMcCrory about everything they’re seeing doing research at the AI frontier.
We talk Fable, human extinction risk, job loss, shrimp rights and more.
podcasts.apple.com/us/podcas…

Bryan Christmas retweeted

Fable isn't the first.
In 1999 the department of defense blocked exports of the PowerMac G4 for crossing the 1 gigaflop threshold.
Steve Jobs turned it into an ad.
Bryan Christmas retweeted

Most of our problems are caused by modernity, because modernity already solved most of the ones that came before.

Bryan Christmas retweeted

Why did xAI hand over a 220,000-GPU cluster to Anthropic?
The technical backdrop to xAI's decision to hand Colossus 1 over to Anthropic in its entirety is more interesting than it appears. xAI deployed more than 220,000 NVIDIA GPUs at its Colossus 1 data center in Memphis. Of these, roughly 150,000 are estimated to be H100s, 50,000 H200s, and 20,000 GB200s. In other words, three different generations of silicon are mixed together inside a single cluster — a "heterogeneous architecture."
For distributed training, however, this configuration is close to a disaster, according to engineers familiar with the setup. In distributed training, 100,000 GPUs must finish a single step simultaneously before the cluster can advance to the next one. Even if the GB200s finish their computation first, the remaining 99,999 chips have to wait for the slower H100s — or for any GPU that has hit a stack-related snag — to catch up. This is known as the straggler effect. The 11% GPU utilization rate (MFU: the share of theoretical FLOPs actually realized) at xAI recently reported by The Information can be read as the numerical fallout of this problem. It stands in stark contrast to the 40%-plus MFU figures achieved by Meta and Google.
The problem runs deeper still. As discussed earlier, NVIDIA's NCCL has traditionally been optimized for a ring topology. It works beautifully at the 1,000–10,000 GPU scale, but once you push into the 100,000-unit range, the latency of data traversing the ring once around becomes punishingly long. GPUs need to churn through computations rapidly to keep MFU high, but while they sit waiting endlessly for data to arrive over the network fabric, more than half of the silicon falls into idle. Google sidestepped this bottleneck with its own custom topology (Google's OCS: Apollo/Palomar), but xAI, by my read, has not yet reached that stage.
Layer Blackwell's (GB200) "power smoothing" issue on top, and the picture comes into focus. According to Zeeshan Patel, formerly in charge of multimodal pre-training at xAI, Blackwell GPUs draw power so aggressively that the chip itself includes a hardware feature for smoothing power delivery. xAI's existing software stack, however, was optimized for Hopper and does not understand the characteristics of the new hardware; when it imposes irregular loads on the chip, the silicon physically destructs — literally melts. That means the modeling stack must be rewritten from scratch, which in turn means scaling is far harder than most of us imagine.
Pulling all of this together points to a single conclusion. xAI judged that training frontier models on Colossus 1 simply was not efficient enough to be worthwhile. It therefore moved its own training workloads wholesale onto Colossus 2, built as a 100% Blackwell homogeneous cluster. Colossus 1, on the other hand — whose mixed architecture is far less crippling for inference, which parallelizes more forgivingly — was leased in its entirety to an Anthropic that desperately needed inference capacity.
Many observers point to what looks like a contradiction: Elon Musk poured enormous capital into building Colossus, only to hand the core asset over to a direct competitor in Anthropic. Others read it as xAI capitulating because it is a "middling frontier lab." But these are surface-level reads.
Look at the numbers and a different picture emerges. xAI today holds roughly 550,000+ GPUs in total (on an H100-equivalent performance basis), and Colossus 1 (220,000 units) accounts for only about 40% of the total available capacity. Colossus 2 — built entirely on Blackwell — is already operational and continuing to expand. Elon kept the all-Blackwell homogeneous cluster (Colossus 2) for himself and leased out the older, mixed-generation Colossus 1. In other words, he handed the pain of rewriting the stack — the MFU-11% debacle — to Anthropic, while keeping his own focus on training the next generation of models.
The real point, then, is this. Elon's objective appears to be positioning ahead of the SpaceXAI IPO at a $1.75 trillion valuation, currently floated for as early as June. The narrative SpaceXAI now needs is that xAI — long the "sore finger" — is not merely a research lab burning cash, but a business with a "neo-cloud" model in the mold of AWS, capable of leasing surplus assets at high yields.
From a cost-of-capital perspective, an "AGI cash incinerator" is far less attractive to investors than a "data-center landlord generating cash."
As noted above, the most important detail of the Colossus 1 lease is that it is for inference, not training. Unlike training, inference requires far less tightly synchronized inter-GPU communication. Even when the chips are heterogeneous, the workload parcels out cleanly across them in parallel. The straggler effect — the chief weakness of a mixed cluster — is essentially neutralized for inference workloads.
Furthermore, with Anthropic occupying all 220,000 GPUs as a single tenant, the network-switch jitter (unanticipated latency) that arises under multi-tenancy disappears. The two sides' technical weaknesses end up complementing each other almost exactly.
One insight follows. As a training cluster mixing H100/H200/GB200, Colossus 1 was an asset that could only deliver an MFU of 11%. The moment it was handed over to a single inference customer, however, that asset transformed into a cash-flow asset rented out at roughly $2.60 per GPU-hour (a weighted average of the lease rates across GPU types). For xAI, what was a "cluster from hell" for training has become a "golden goose" minting $5–6 billion in annual revenue when redeployed for inference. Elon's genius, I would argue, lies not in the model but in this asset-rotation structure.
The weight of that $6 billion becomes clearer when set against xAI's income statement. Annualizing xAI's 1Q26 net loss yields roughly $6 billion in losses per year. The $5–6 billion in annual revenue generated by leasing Colossus 1 to Anthropic, in other words, almost perfectly hedges xAI's loss figure. This single deal effectively pulls xAI to break-even.
Heading into the SpaceXAI IPO, this functions as a core line of financial defense. From a cost-of-capital standpoint, if the image shifts from "research lab burning cash" to "infrastructure tollgate stably printing $6 billion a year," the entire tone of the offering can change.
(May 8, 2026, Mirae Asset Securities)

What the SpaceX–Anthropic Deal Means
Two weeks ago, we published a note laying out what GPT-5.5's release implied. The conclusion was simple: whoever secures compute first, in greater volume, and with greater reliability ultimately takes the win. With OpenAI's 30GW roadmap dwarfing Anthropic's 7–8GW, we closed by arguing that the structural advantage on compute sat with OpenAI.
Less than a fortnight later, that conclusion is being tested. On May 6, Anthropic signed a single-tenant lease for the entirety of Colossus 1 with SpaceXAI — the infrastructure subsidiary that consolidates Elon Musk's xAI and SpaceX. The asset carries more than 220,000 GPUs and 300MW of power, and crucially, is scheduled to come online within this month. It served as the capstone of Anthropic's April blitz, which added 13.8GW of cumulative capacity over the span of a single month. On headline numbers alone, OpenAI took more than a year to stack 18GW; Anthropic has put 13.8GW in the ground in thirty days. The takeaways break down into three.
First, the compute pecking order has been redrawn again. Anthropic has now swept up the AWS expansion (5GW, with $100B+ in spend commitments over a decade), Google + Broadcom (3.5GW of TPU), Google Cloud (5GW alongside a $40B investment), and now SpaceXAI's Colossus 1 (0.3GW). Cumulative committed capacity, inclusive of pre-April allocations, sits at 14.8GW. This is still only half of OpenAI's 2030 target of 30GW, but the fact that the SpaceX lease will be live inside a month makes "deliverability" a qualitatively different proposition.
Second, Elon Musk is the plaintiff in an active lawsuit against OpenAI — and at the same time, the supplier handing 220,000+ GPUs and 300MW of power, in one block, to OpenAI's most formidable competitor. The timing matters: the deal was struck in the middle of the Musk–Altman trial. We read this as a deliberate pincer with OpenAI in the middle. In the courtroom, Musk works to dismantle the moral legitimacy of OpenAI's leadership; in the market, he arms Anthropic to absorb OpenAI's revenue and user base.
Third, the structure is financial-engineering perfection — a clean win-win for both sides. xAI can recognize $6B of annual revenue from a single contract, an amount that almost precisely offsets its Q1 2026 annualized net loss of $6B. It also accelerates the cleanup of SpaceXAI's pre-IPO balance sheet, with the entity now being floated at around $1.75T. Anthropic, on the other side, converts roughly $5B of spend into what it expects to be $15B of ARR via the coming inference-revenue surge.
(Mirae Asset Securities, May 8, 2026)

Bryan Christmas retweeted

Something strange is happening in tech.
CTOs of billion dollar companies are quitting to take IC roles at Anthropic.
Workday CTO -> MTS (Mar 2026)
You[.]com CTO -> MTS (Mar 2026)
Instagram CTO -> MTS (Jan 2026)
Box CTO -> MTS (Dec 2025)
Super[.]com CTO -> MTS (July 2025)
Adept AI CTO -> MTS (Jan 2025)
The mission is that real.
Bryan Christmas retweeted

Very interesting announcement from OpenAI this morning. We’re excited to make OpenAI's models available directly to customers on Bedrock in the coming weeks, alongside the upcoming Stateful Runtime Environment. With this, builders will have even more choice to pick the right model for the right job. More details at our AWS event in San Francisco tomorrow.
Bryan Christmas retweeted

New Robinhood phishing chain that's kinda beautiful:
1. Attacker creates an RH account using the Gmail dot trick of your email (same inbox, different address)
2. Sets device name to HTML
3. RH's "unrecognized activity" email renders the device name unsanitized (html injection)
The result is a real email from [email protected], DKIM pass, SPF pass, DMARC pass, with a phishing CTA
Just because it's real, doesn't mean it's safe... $HOOD


Bryan Christmas retweeted
I have been using GPT ImageGen-2 for the past weeks
I didn't think that better image-generators would be a big deal but it turns out that there is a quality threshold I didn't expect, where you can now get text, slides, academic papers
Look at what it does with my "otter test"!
🤖 Made with AI


