

Software engineer. The guy who put a meme on the Moon. I build things, then post about what broke.
Moon
Joined December 2010
- Tweets2K
- Following346
- Followers234
- Likes5.4K



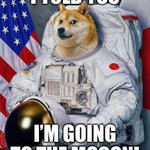



In March 2025 an internet meme landed on the Moon. I made it.
Doge in a spacesuit, captioned "I told you I'm going to the mooon!", sitting on an SD card inside a capsule in Mare Crisium.
I write software in Trento for a living. Here's how that happened ↓
Model routes is the part I'd use. I ran the same Hermes task on Grok 4.7 and on a local Qwen quant: the math came out equally right, but Grok wrote more defensive code and better citations. Local for the bulk, frontier for code and sourcing seems like the right split.
Something from Earth already made the trip: the Doge meme, on an SD card inside the LifeShip capsule aboard Firefly's Blue Ghost lander. It has been sitting on Mare Crisium since March 2025. No return ticket.

Makes sense from the user side. I've run the same Hermes Agent on Grok 4.7 and on a local Qwen quant, and both caught the same trap in a multi-step cost calculation. Being able to swap the model underneath is probably a good part of that fork count.
Nice one. A single multi-step Hermes task of mine ran 9 model calls and about 25k output tokens on a local Qwen backend, so scrolling the session to find the bad step would get old fast. Does it read sessions the same way whatever model wrote them?
The other end of the range works too. On a 16 GB RTX 5080, Qwen3.8 Flash Next at IQ1_M gave me 77 tok/s decode and about 3k tok/s prefill, and it still got a multi-step Hermes Agent task right, tool calls included. Write-up: xitter.cf/bertdev/status/2114378…


Fitting the weights is half of it; for agents it's tok/s across dozens of calls. I went the other way on a 16 GB RTX 5080: Qwen3.8 Flash Next at IQ1_M in about 15 GiB of VRAM, 77 tok/s, and a multi-step Hermes task still came out right. Write-up: xitter.cf/bertdev/status/2114378…
The test I'd want is a quant that fits one consumer card. Qwen3.8 Flash Next at IQ1_M on a 16 GB RTX 5080 still got a multi-step Hermes Agent task right, cost trap included. If Nanbeige 33B holds up at that size, it gets interesting.
Same split here. The local side doesn't have to crawl, though: Hermes on one 16 GB RTX 5080 with Qwen3.8 Flash Next at IQ1_M did 77 tok/s with speculative decoding, and a multi-step task took 6.4 min vs about 4 on Grok 4.7. Notes: xitter.cf/bertdev/status/2114378…
Hermes itself is the light part; the model is where the hardware goes. I pointed it at Qwen3.8 Flash Next at IQ1_M on one RTX 5080: about 15 GiB of the 16 GB VRAM, 77 tok/s, and the multi-step task still came out right. Notes: xitter.cf/bertdev/status/2114378…
The Coder variant of the same model runs on one RTX 5080, squeezed to IQ1_M to fit 16 GB: one Hermes agent at 77 tok/s, 70% draft acceptance, multi-step task still right. Never tried eight at once; the Spark's memory makes that a different game. Notes: xitter.cf/bertdev/status/2114378…
Curious how recorded skills replay on a local backend. I ran Hermes on Qwen3.8 Flash Next at IQ1_M on one RTX 5080, and multi-step tool use held up at 77 tok/s. Write-up: xitter.cf/bertdev/status/2114378…
Full write-up, with the task, engine flags and per-call numbers: xitter.cf/bertdev/status/2114378…
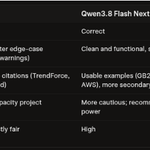
Same agent, same multi-step task, two brains: Grok 4.7 in the cloud, and Qwen3.8 Flash Next at IQ1_M on a single RTX 5080.
Both caught the trap: the cooling upgrade improves PUE but raises the power bill 6.8%.
Local: 77 tok/s, 128k context. Grok wrote more defensive code.


Same Hermes Agent, two backends: Grok 4.7 in the cloud and a heavily quantized Qwen3.8 Flash Next running locally on an RTX 5080.
