
Solving the big ones…
Joined April 2026
- Tweets406
- Following905
- Followers121
- Likes3.6K




Security Update for anyone running @NousResearch hermes, you need to recomplie your binary not just patch your ststem. (eMudhra)
We found hermes kept trusting the compromised chain anyway. The reason was in its Cargo.lock: webpki-roots 1.0.7 — Mozilla's root program compiled INTO the binary. It never reads /etc/ssl/certs. Patching the box does nothing for a binary that brought its own trust store.
What to do — today:
Inventory every agent or binary that ships its own TLS. Rust: check Cargo.lock for webpki-roots (fix: 1.0.10) and rustls-webpki (fix: 0.103.16). Node/Bun/Deno: the store is compiled in — rebuild on 22.23.4 / 24.22.1 / 26.12.1 (Node 20 never gets a fix; NODE_OPTIONS=--use-openssl-ca is the stopgap).
Rebuild and redeploy. Restarting an old binary changes nothing.
Still exposed? Stop the agent units and verify zero residual processes before assuming you're safe.
Verify with a probe, not a grep: the disclosure site's test hosts return HTTP 200 through the compromised chain — 200 = vulnerable, an explicit "issuer not in trust store" = safe. Test BOTH roots (emSign G3 and the AAA cross-sign), or your check false-passes.
Disclosure: emudhra.we-have-a-problem.co…
dont sleep on this guy 🔥

5 TandemLLM releases in 3 days. 26 quants on Hugging Face in 3 weeks.
Every Nemotron Bolt and Super size from 2.0 to 6.0 bits was converted and measured by me, on GPUs I rented for many hours with my own money, so you could run them in one click the day they dropped.
I'm not asking for money. Here's how you can help:
🔁 repost if local AI matters to you
⭐ star the repo
❤️ like the quants you use on HF
🧪 try it and tell me what breaks
Which model should I quant next? 👇
chris_paul_walker retweeted

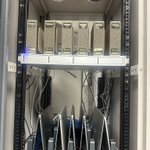
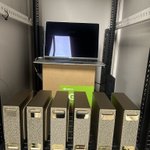
Our on-device infra team has a knack for clean-looking setups...
can you identify all the hardware? 👀

- a MacBook Air sitting on a plastic bucket
- talking to my tint machine through a COM port
- being controlled by GLM 5.3 Flash on sparks upstairs
- debugging the new software it just wrote for me saving $30k per year
- using the webcam to check in when needed
Feels like the future to me @NVIDIAAI @ashxhart @MiaAI_lab @Zai_org


chris_paul_walker retweeted

Fascinating mind virus ripping through parts of open source right now. Listen, the code is good or bad whether it was written by math or by mind. Coder or clanker. Merge good code, reject bad code. You don't need a fucking code of conduct or contributor covenant for that!


chris_paul_walker retweeted

If you're a fan of tensorfold and local AI, @plotarmordev is a must follow.
An incredible asset to any development team, and some of the most original, quality content out there on running local AI.
Their Spark vs M5 Ultra breakdown is the latest proof: real benchmarks, same engine, honest results.
Go follow. You'll learn something every week.

1/5 The fastest prefill is no prefill.
We measured agent coding sessions on a DGX Spark (@ashxhart Tensorfold, Qwen3.8-27B): 99.56% of the 82M prompt tokens the agent sent were served from cache. Only 361k were ever computed.
In a 522-request session the engine prefilled 100,469 tokens, exactly the final context length. Every token computed once.
The work isn't faster prefill kernels. It's never breaking the prefix.
4/5 Where the recomputed tokens come from: ~40% is the model's own previous reply, 21% genuinely new text, 12% each session's first system prompt and tools, 10% a single token that renders differently when a reply comes back without its reasoning.
3/5 On that replay, TensorFold's current cache reuses ~94% of prompt tokens. An ideal prefix cache would reuse 97.2%. So about half of what still gets prefilled is avoidable in principle.
2/5 How we measured the rest: we rebuilt every request from our harness's session logs, rendered each through the model's chat template and tokenizer, and replayed 11,333 agent calls against the engine's cache rules, checked call for call against its code.
Thrilled to wake up to this, and honoured to have assembled something that is performing at the top of the pile. Big things to come and great to see so many sharp minds pushing in this direction. Reducing the cost of intelligence also comes with huge environmental benefits and capex reduction when measuring cost per successfully completed task. more to come 🚀
thanks @DustinHenning for your invaluable contributions and @airesearch12 for your effort in benching all of our work. Running on @googlegemma and tested on @NVIDIAAI

Who's on top now?
JevBench v1.5 is out, and for the first time there's no clear solo #1: Cygnet and Winnow-12B are so close they basically share the top.
The original chad Jev lands on 3rd place now.
➡️benchmarkheaven.com/jev-mode…
Many methodological improvements, see below


The sparks made some friends, now I just need some time to play with @ashxhart wizardry….and a nice little storage upgrade 👌


