

Building apps & testing AI 🤖 Local models • Agents • Automation • AI Video • Game Dev Real experiments. Honest results.
Ireland
Joined October 2026
- Tweets1.1K
- Following904
- Followers680
- Likes1.3K




Pinned Tweet
I compared Strata engines 0.1.52 and 0.1.59 on my Windows laptop with an RTX 4090 Laptop GPU (16 GB VRAM) and 80 GB of RAM. The biggest gain was in prefill, the time spent processing the prompt before the model starts writing.
Both builds ran Qwen3.8-Flash-Next GSQ-RCO IQ3_XXS with a 524,288-token context, YaRN ×2, int8 KV cache with 32,768 tokens resident on the GPU, MTP window 4 and a 2,304 MiB VRAM reserve. The Python server moved from Strata 0.2.6 to 0.2.13.
Fresh prompts · engine 0.1.52 → 0.1.59
• 8,473 input tokens, 3 runs per build. Prefill 2,133 → 2,430 tok/s. First token 4.02 → 3.52 s. Decode 104.5 → 103.5 tok/s.
• 134,568 input tokens, 2 runs per build. Prefill 2,544 → 2,864 tok/s. First token 53.07 → 47.14 s. Decode 94.4 → 94.3 tok/s.
• 453,109 input tokens, 1 run per build. Prefill 2,217 → 2,431 tok/s. First token 204.66 → 186.69 s. Decode 85.5 → 87.8 tok/s.
Each fresh test reused zero input tokens and generated 256 tokens with greedy decoding. Repeated runs are reported as medians.
I also ran five matched cached follow-ups per build at each size. At 8.5K, median decode was 92.7 → 95.3 tok/s. At 135K it was 88.7 → 87.5 tok/s, with time to first token around 1.9 s on both builds. Each build reread a median of 61 input tokens in those cached tests.
A separate MTP test at temperature 0.6 gave mixed results. Moving from window 4 to 6 raised median decode from 68.2 to 73.3 tok/s at 399K and lowered it from 81.6 to 79.5 tok/s at 135K. I kept window 4 for daily use.
Thanks to @coldniko for building Strata. Engine link in the first comment.
#LocalAI #Strata #Qwen

Do these models even deserve a ping-pong table? 🏓
Heretic 9B: computes ballPos, never updates the ball mesh.
ERNIE 5.5 Flash: compares cat objects to strings, skips rally poses.
Valid JS. Invalid sports.
Unedited outputs; Heretic got repairs. Different setups.
2
77
598 followers today! 🚀
X says I'm eligible for monetization… just need another 497,700 impressions 😂
Building in public, testing local AI, breaking things and sharing what actually works.
Who's also growing from scratch?
Drop a 👋 and let's connect

30
24
582
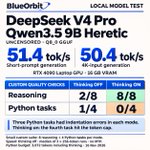
A small DeepSeek-distilled model you can run locally, hitting ~51 tok/s on my laptop.
Sounds promising but can it write usable Python?
I tested DeepSeek V4 Pro Qwen3.5 9B Heretic on an RTX 4090 Laptop GPU with 16 GB VRAM, using Q8_0 GGUF.
My small custom test:
Thinking OFF: reasoning 2/8 · Python 1/4
Thinking ON: reasoning 8/8 · Python 0/4
Thinking helped it solve all eight reasoning questions. The code was another story.
Three Python tasks had broken indentation in each mode. With thinking on, the fourth burned through its 3,072-token budget without returning code.
Interesting reasoning results for a 9B model. I wouldn’t trust this setup with coding yet.
Anyone getting better Python output from this exact Heretic checkpoint?

Model: huggingface.co/xtools-at/Dee…
Q8_0 GGUF used: huggingface.co/mradermacher/…
Engine: llama.cpp b12445, CUDA 12.4, native Windows.
8K context capacity, Flash Attention on, single request at a time, temperature 0, no prompt cache or MTP.
Speed figures: median of three 256-token runs per prompt size, thinking off.

2
46
Claude Code can make the assets for your game too.
NVAI-open exposes local image, video + sound, speech, music and 3D generation through MCP, then copies the output into your project.
Its Nov 15 release adds a 7-step video assistant and hardware-aware generation estimates.
The developer reports 166/166 end-to-end checks passing. Their Windows test GPU was an RTX 5060 Ti with 16GB VRAM.
One caveat: it hides the node graph, but ComfyUI still runs underneath.
I'd like to try this on my 4090.
#LocalAi

2
5
147
GitHub: github.com/Mantux775/NVAI-op…
Latest release (0.5.28): github.com/Mantux775/NVAI-op…
Claude Code MCP integration: github.com/Mantux775/NVAI-op…
Models, benchmarks and license details: github.com/Mantux775/NVAI-op…
Windows installation: github.com/Mantux775/NVAI-op…

1
42
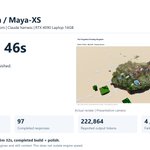
Would you wait 5h 20m for this voxel kingdom?
GLM 5.3 Flash / Maya-XS in Claude, on a 16GB RTX 4090 laptop. Same prompt as yesterday’s Qwen test.
That excludes the overnight pause. I stopped it with polish still unfinished.

RTX 4090 Laptop 16GB · Claude · 512K · int8 KV
Initial input: 75,719 tokens (including system/tools).
Prefill: 259.5 tok/s (52 resumed requests, uncached tokens).
Maya v1.1.64:
github.com/mw00/project-maya
GLM 5.3 Flash Maya-XS IQ1_S:
huggingface.co/peasantsmith/…

1
60
50% fewer tokens + 70% cheaper implicit caching. If you're building multi-step agents, Qwen4-Max just slashed your burn rate in half.
#qwen4

📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: qwencloud.com/models/qwen4-m…
- Token Plan: qwencloud.com/pricing/token-…
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀

1
3
145
A DeepSeek Coding Plan? Now you’ve got my attention 👀
Nothing confirmed yet, but I’m hoping this happens. Sensible pricing and generous usage limits would make it very tempting.
The first thing I’m checking is how much coding I can actually get done before hitting the limit
#DeepSeek


1
6
269

10/10
Thanks @PeasantSmith for Project Maya.
To you and other inference enthusiasts: what would you test next to reach 30+ sustained tok/s at 256K on 16GB VRAM + 80GB RAM while preserving quality?
Engine/model links below.
#LocalAI #GLM
1
1
38
Project Maya v1.1.64 by @PeasantSmith:
github.com/mw00/project-maya…
Model: GLM 5.3 Flash Maya-XS IQ1_S (73.4GB):
huggingface.co/peasantsmith/…

1
35