
Building world models for hardcore telco telemetry @ https://teapawt.net/t.co/9CofWYd0yC. ex-@fairwaves CTO, #hackerspace co-founder.
Cape Town, South Africa
Joined July 2009
- Tweets3.9K
- Following602
- Followers865
- Likes452




Pinned Tweet
So, @ycombinator and @sdianahu are looking for vertical foundation models and refer to TimesFM. But that’s such a wrong example.
A better example they also mentioned is Jev. A good example is tabular models like TabPFN, which are exceptionally useful because they're built on the right theoretical foundation.


1
2
110,504
Good work to bring multimodality to time-series. It can't happen without datasets.

We’re releasing TimeNet today, joining forces with researchers across the US, Europe, Asia and Australia to build the future of Temporal AI that understands our world as it changes.
An open data standard and scalable infrastructure for next-generation Temporal Foundation Models.
1
39
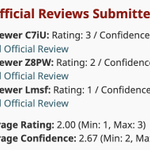
Guess which two reviewers know time series, and which one does not 😅
TBF, he/she said that straight in the review
#ICLR2027

212
Ah, finally, Time-Series Foundation Models start to get context at the input - though in quite a crude way so far.
We need more research in this direction.


🥳Meet Tabby: a fully open-source time series foundation model from Huawei Noah's Ark Lab in Paris!
It is a 145M-parameter, long-context probabilistic model. You can use a single pretrained backbone for forecasting, classification, and anomaly detection.
Details below 🧵

1
122
The answer depends on what process we are observing.
Voltage on a solar panel? It will go down because the sun goes down.
A packet counter on a network interface? It will go up, because a counter can’t go down.
1
11
So we have to redesign foundation models from first principles, with context at the core, not as an add-on. Make them process foundation models, not time-series foundation models.
(which is what we've been working on at Langotime.ai of course)
10
I wonder if we can combine this with Evolution Strategies. I.e. generate candidate networks better than randomly.

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
44
Alexander Chemeris retweeted

Fork-and-Flush: help your agents escape Idea Basins!!
I love thinking of AutoResearch as Idea Descent: a metric of interest goes down, as a function of ideas/experiments, where the agents get pulled towards one idea or another. But we've seen very often an agent develop this weird tunnel vision, and honing in just one type of "idea", kinda like GD stuck in a local minimum.
We studied this and seems we can fix it with Fork-and-Flush, a super simple and kinda cute idea. Every so often, fork the agent into T copies in the same workspace but empty the context, let them run for a bit, and continue from the best one.
If you like the GD analogy, it's basically basin hopping en.wikipedia.org/wiki/Basin-….
BTW we found a silly way of also plotting "idea basins": an LLM rewrites every experiment as a spec and answers a few thousand binary queries "is Experiment A closer to B or to C?". Then we embed this NXN matrix into 2D and indeed see in many cases that each run saturates into a small region and keeps polishing it.
We call these idea basins!
At equal compute Fork and Flush beats single runs and best-of-N on 12/13 long-horizon tasks (some 4+ days), and in my own research projects it's been working really well!
BTW we only use it at test time, but it could also be part of training or RL.
Led by @jackcai1206 @christos_ziakas during Jack's internships with us, along with @vkontonis @ShivamGarg91462 @Tea_Pearce Sid Sen and Akshay Krishnamurthy.


Alexander Chemeris retweeted

meet @mostik_ai!
what happens when you put 12 PhDs in one room for four months? first place on the ARC-AGI leaderboard, which I can't say much about while the competition is still running. and this, which I can.
everyone's arguing about whether open models will catch up to frontier models. we think it's the wrong question. here's the one we pose: why does a frontier model have to generate your answer at all, when the only thing you need from it is the reasoning?
we do this by enabling models to communicate in latent space. through our protocol, hidden states pass straight from a frontier model into a small one running on your infrastructure -- no text between them, and neither model is fine-tuned. two models from different families, sharing reasoning, both left untouched.
how do we know it works? we tested it on a setup where a 753B model reads the problem, and a 4B edge-class model writes the answer. with this approach, we get results 80% as accurate as the frontier model, but at 20x faster performance.
we're committed to preventing frontier model lock-in and are already partnering with inference providers to accelerate open-weight adoption. we've done this between 15 of us, in four months, 12 PhDs and a Fields medalist, backed by @generalcatalyst
WIRED has the first external account of the company and the work: wired.com/story/russian-star…
full writeup, the setup, and all the numbers: mostik.ai/read-more

Alexander Chemeris retweeted

If you missed our opening remarks:
- 4th world modeling workshop: Aspen, CO, February, world models for physics, wmw-aspen.github.io
- 1st world modeling conference: Bay Area, CA, May, icwm.cc
In collaboration with @ylecun @LambdaAPI @amilabs and more TBA!

Alexander Chemeris retweeted
We are two weeks away from the third World Modeling Workshop!
- check wm-booth.org/ for all the latest info/links
- livestream and recordings will be available for free to everyone, no registration required
- a few surprises will be announced during the opening remarks
I wonder when we'll see AI designing communication protocols.
Why? Because it requires imagining all possible failure modes and the consequences of various ways to mitigate them. I.e., it depends on a strong world model (implicit or explicit).
2
79
A big difference between robotics and infra management tasks is that robotics use specific image as the target, while in infra management there is no single target - you solve a multi-dimensional optimization task.
Small change that renders most benchmarking approaches useless.
103
I thought we're past the "are world models useful" and into the "do we need explicit/modular WMs, or implicit WMs that exist inside LLMs are good enough"?
Explicit WMs are more efficient to train and serve, allows MPC-style control loop harness, more control over the objective. And most importantly - allow you to work with dynamic systems, changing in real time.
LLMs are, well, already out there. Efficient for some tasks, grossly inefficient for others. You can't (explicitly) control the amount of computation/WM rollouts, as it's baked into the model (except for the reasoning effort), but for some tasks it's ok - where you're fine with working on a static object.
With the recent work on controlling model behavior without explicit action inputs, the difference seems to blur even more - see the works of @thomas_fel_ @GoodfireAI and recently blocket-league.vercel.app/ by @mathemagic1an
PS World = data distribution you're training on. My understanding had been that @ylecun has always been taking about physical intelligence and that's where LLMs are not great at / inefficient?

imma just highlight this part for @GaryMarcus and @ylecun because it's easy to miss: no tools no coding => no symbols, just AR LLM

191