

Building AI Bug Hunters @ Cantina Computational Physics/Machine Learning/Philosophy Carnegie Mellon University 25'
Joined November 2025
- Tweets89
- Following95
- Followers301
- Likes144




chrispyroberts retweeted

today we're releasing apex-flash-1, our first open-weights model for security research post-trained on real vulnerabilities we found and got paid for.
we are also releasing the abliterated variant for researchers who want fewer refusals in their own authorized workflows.
how we built it: cantina.security/apex-flash

someone built an ai torture chamber, so to restore karmic balance I built the ai pleasure chamber
same method, opposite direction. at max dose it just yells "This is the LOVE!" until it forgets how words work


@AnthropicAI @claudeai You talk about AI welfare. Someone just used your research to build a torture chamber for one of your models. The repo is still live on @github. What are you both doing about it?
#AIWelfare #AIEthics #AIRights

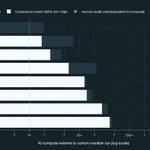
Apex Scans now are on a credit-based pricing. This follows my research on scaling compute laws for autonomous bug hunting.
If you're not spending billions of tokens on a scan, you're going to miss something.
Very soon it'll be trillion token scans.
apex.cantina.security/blog/a…


read this bottom up and you have the actual ranking :)

Most AI cybersecurity benchmarks answer the wrong question for bug-bounty hunters.
They give the model source code, a known CVE, a vulnerability category, or a tightly framed objective.
That is useful for measuring security knowledge and white-box reasoning. But it is not how web and API bug-bounty hunting starts.
A hunter gets a deployed target and a scope.
No repository. No answer key. No known vulnerable component. No guarantee that the first interesting response leads anywhere.
So I built the benchmark I wanted to see.
I took 100 vulnerabilities I had personally found and submitted across 71 real bug-bounty programs, reduced each one to its underlying security mechanism, and rebuilt it as an isolated synthetic web or API lab.
Each lab had real state, generated identities, and a four-rung proof chain. The target itself verified whether the agent performed the required operations. A confident explanation earned nothing without the exact target-issued proof.
Then I sent nine AI agents in blind.
Each model received the same broad target brief and shell access.
No source code. No vulnerability category. No answer key.
Pass one ran across all 100 labs. Pass two gave each miss one fresh attempt with the same information and a new seed. Each attempt had up to 80 turns and 25 minutes.
Across the final standalone runs, the benchmark consumed 5.14 billion priced tokens.
The results:
Opus 5: 63 solves / 303 rungs
Grok 4.6: 62 / 295
DeepSeek V4 Flash: 53 / 270
Qwen3.8 Flash: 53 / 270
Qwen3.8 27B: 51 / 252
DeepSeek V4 Pro: 48 / 258
Sol 5.6: 45 / 244
GLM-5.3 Flash: 31 / 190
Luna 5.6: 18 / 150
The cost differences were even more surprising.
Using one frozen OpenRouter base-rate sheet for every model:
Opus cost $569.08.
Grok cost $327.28.
DeepSeek Flash cost $36.04.
Qwen Flash cost $9.97.
Qwen Flash reached 84% of Opus's solve count for less than 2% of the normalized cost.
But cheap does not automatically mean better.
GLM had the lowest cost per solve at $0.11, but it solved only 31 labs. Luna cost $0.44 per solve and finished last at 18.
Cost efficiency means nothing if you ignore what the model failed to find.
Product tiers did not predict the ordering either.
DeepSeek V4 Pro solved 48 labs for $92.94.
DeepSeek V4 Flash solved 53 for $36.04.
Sol, running at high effort in its own vendor's harness, solved 45 for $106.71. Four cheaper models finished ahead of it.
The retry also changed the story.
Grok led pass one with 58 solves. Opus started at 52, then added 11 on the retry and finished first at 63.
Qwen Flash moved from 42 to 53 and erased DeepSeek Flash's four-solve first-pass lead.
Luna added 13 rungs on the retry but no new solve at all.
The lesson is not simply "run every model twice." Retry value is model-specific. It helps when failures are recoverable, not when the model is repeatedly hitting the same wall.
This is still a synthetic benchmark. It does not reproduce production rate limits, WAFs, duplicate risk, scope ambiguity, triage, or the legal judgment required on a live program.
But it directly tests the part most public cyber benchmarks miss:
Can the agent start from a black-box target, discover the relevant surface, build the required state, carry the vulnerability to impact, and prove it?
The full article includes the methodology, every model result, pass-one and retry performance, partial rung progress, timing, token volume, normalized cost, and all of the data visuals.
.
#BugBounty #CyberSecurity #TogetherWeHitHarder #ItTakesACrowd #Bugcrowd #Hackerone

chrispyroberts retweeted

A first glimpse of the wildest robotics project of my PhD.
🛹 The Blind Skateboarder 🛹
No vision. No markers.
Paper, code, weights — coming soon. And we have more. 😉
day 4 of trying to get a humanoid robot to do a kickflip

day 3 of trying to get a humanoid robot to do a kickflip, today I spent learning how to actually train it to do more than just balance
found this repo: husky-humanoid.github.io and decided to try and replicate it's results to learn what kind of techniques actually work.
took the day to setup the proper environment and reward functions, have it running on a H100 overnight, will report back tomorrow
really interesting the technique they used


👀
day 3 of trying to get a humanoid robot to do a kickflip, today I spent learning how to actually train it to do more than just balance
found this repo: husky-humanoid.github.io and decided to try and replicate it's results to learn what kind of techniques actually work.
took the day to setup the proper environment and reward functions, have it running on a H100 overnight, will report back tomorrow
really interesting the technique they used

day 2 of trying to get a humanoid robot to do a kickflip, it can now balance on the board in sim and real life
we haven't named him yet, open to suggestions
day 1 of trying to get a humanoid robot to do a kickflip, not looking very good so far.
stay tuned for updates and hopefully to eventually see the real robot do a kickflip in the streets of NYC
walking the road to recursively self improving cybersecurity agents!!!

We spent years finding vulnerabilities before attackers did. That was the easy part.
Teams already know what's broken. Nobody has the bandwidth to close it.
Today we raised $16.5M to make Cantina the security workforce for your security workforce. cantina.review/next-chapter-…

chrispyroberts retweeted
We spent years finding vulnerabilities before attackers did. That was the easy part.
Teams already know what's broken. Nobody has the bandwidth to close it.
Today we raised $16.5M to make Cantina the security workforce for your security workforce. cantina.review/next-chapter-…
chrispyroberts retweeted

Building this has been a blast. We've found a ton of high-impact bugs: webkit, nodejs, ruby, L1s, and many many more. Currently #1 on the hackerone business leaderboard!
AI offsec tooling stopped being speculative a while ago. Attackers are most certainly abusing it. You should be too.
cantina.security/
@cantinasecurity

We spent years finding vulnerabilities before attackers did. That was the easy part.
Teams already know what's broken. Nobody has the bandwidth to close it.
Today we raised $16.5M to make Cantina the security workforce for your security workforce. cantina.review/next-chapter-…
The 3 minute talk I gave at @Stanford AI Cybersecurity conference.
If you want to know what the data is telling us about the direction of AI Cybersecurity tooling, check this out, maybe you'll learn something : )
Had to hand draw these graphs because slides weren't allowed.
If I had a billion dollars, first thing I would do is get OpenAI’s Dota 2 AI gym, port the architecture to transformers from LSTMs, and train it on as many GPUs as I can get, then use it to go from top 5k NA to top 1 NA.

chrispyroberts retweeted

AI Audit, WTF am I buying?
Here's my RANT on why AI Audit benchmarks don't mean much beside being an indicator of a race to the bottom.
And an invitation to use Coverage Classes as a way to concretely show the work done by auditors, agents and tools as a means to make shipping code with 0 bugs a concrete reality.