

SWE @Architect_Fi | ex @Polkadot | rustacean | sleep with agents
Earth 616
Joined November 2022
- Tweets1.5K
- Following1.6K
- Followers746
- Likes2.6K




Pinned Tweet
It's Lunar New Year, so here's my reflection for 2025:
(1) Building more practically applied AI services and agentic engineering
I accepted that the AI era already started, and my job now is not to try to get offended by its capabilities, but to learn how to master the technology. I switched entirely from VSCode to @cursor_ai and then Codex, Gemini, and Claude.
I was aware of the AI advancement back in 2022, but only using @OpenAI for a daily chatbot. Even the AI-applied services I built before only stop at tuning prompt techniques. So I dived deep into RAG, inference, and advanced frameworks like @LangChain_JS and @crewAIInc to build apps like @GrowlySuite and @speedgrowth_ai
(2) Seize all the opportunities, and life will reward you
I’ve realized that life doesn't just hand out participation trophies; it rewards the intensity with which you seize the opportunities in front of you. This year was a testament to the fact that when you lean into the chaos of a changing industry and put in the raw effort, the universe tends to meet you halfway.
My team at @GrowlySuite got a chance to live in @ns for a month, and it was a life-changing experience, seeing people building in the frontier with innovative ideas.
Or I still remember the first time I spoke in a big conference like @gmvn_official to represent @Polkadot.
At the end, it’s about being positioned to say "yes" when the right door opens, and having the stamina to walk through it.
(3) Health is still the strongest weapon you need to sharpen every single day
In the midst of building and scaling, I’ve been reminded that health isn't a secondary goal—it is the strongest weapon in my arsenal. You can have the most advanced AI agents in the world, but if the "human in the loop" is compromised, the system fails.
(4) Loss is a part of life
2025 also carried the heavy reminder that loss is an inextricable part of the human experience. Whether it is the loss of people, opportunities, or past versions of ourselves, I’ve had to learn how to carry that weight without letting it anchor me in the past. It is a quiet, difficult teacher, but it has added a layer of depth to my work and my relationships that wasn't there before.
(5) This all shall pass
"This all shall pass" has become my mantra for the upcoming year. I am still learning how to truly accustom myself to the fact that time is fleeting—that the highs are temporary and the lows are, too.
This perspective brings a strange kind of peace; it forces me to stay present in the build and grateful for the moment, knowing that the only constant is change.
Tin retweeted

Liquid Inference is serving 10B tokens/day and growing 200% week over week.
Most of the traffic is agents and long chats. Across 470k charged jobs, 88.7% of input tokens were cache reads.
Here’s how our matching algorithm prices offers with cache hit rate included:
In multi-turn and agentic workloads, the biggest cost and latency wins come from prefix/KV cache reuse. Each turn resends the full conversation, so if a provider still has that prefix in its cache it can bill those tokens at its cache-read rate, often a small fraction of the normal input rate.
Naive load balancing or pure price auctions scatter a session across different providers or replicas, forcing full prefill on every turn and destroying the savings.
Our matching algorithm ranks offers on the expected charge inclusive of cache hit rate rather than the full list price:
1. We measure how much of each workspace’s input repeats from one turn to the next (7-day window, at least 50 jobs).
2. We multiply that share by the measured cache hit rate of each deployment.
3. We price those tokens at the offer’s cache-read rate and subtract the expected saving from the offer’s ranking charge.
4. The deployment that served the previous turn keeps a 5% margin, so a cheaper offer has to win by more than 5% to pull a warm session away. In other words, for the right price we will abandon the cache and choose the cheaper alternative.
The credit only changes the order of the offers. A wrong estimate cannot make a job cost more than its price cap. Every receipt shows the cache share we expected, the share that was realized, and the credit in dollars.
That’s how we continue to improve on cache hit rate and provide the best economics for our clients’ sessions.
Tin retweeted

Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi.ai, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro

Tin retweeted

f*cking insane. BlackRock's CEO said AI would one day be bought like oil. someone already built the exchange, and the prices are collapsing in real time
every prompt you send goes to a live auction. ~30 companies bid on it. the cheapest one that meets your rules wins, and the price is locked before the first word
the same Kimi K3 model is on there from 8 sellers. one charges $15.94 per million tokens, another $0.036. 442x apart
and it keeps falling. the last 7 days on the book:
→ DeepSeek V4.1 Flash: $1.20 → free
→ Qwen 3.6: -97%
→ MiMo V2.6 Flash: -98%
one command plugs it into Claude Code. watch second 15: i hit enter and 25 agents on 25 different models start buying their own brains at auction
honest part: Claude itself has one seller there, so no discount yet. the drops are on open models
Stripe is paying $7 billion for OpenRouter. this is what comes after it
built by architect.co. new accounts start with free credit, setup below ↓

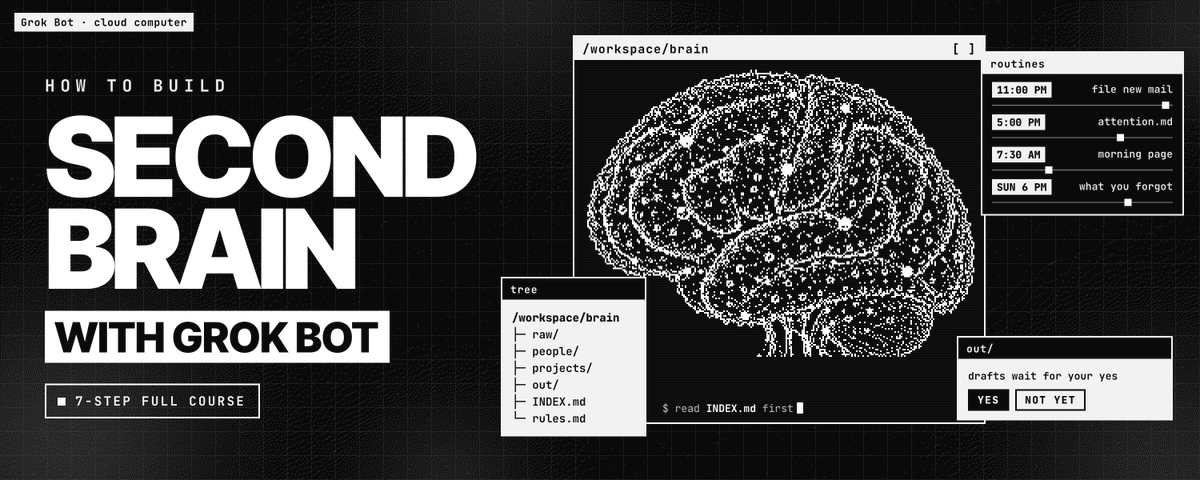
Liquid CLI + Oh My Pi is my go-to local harness setup now. It takes 3 commands to have everything ready under 5 minutes
- Install Liquid CLI
- liquid login
- liquid omp


Tin retweeted
Liquid Inference now supports images and video! Video inference costs aren’t optimized to the same level as text, and a fair auction brings iterative AI content creation in line. Access via our API or check out the compare tool in our web playground.
Tin retweeted
The Liquid Inference router network is growing quickly. We now have 28 verified companies serving >1000 models, offering capacity dynamically and updating quotes in real-time. Average time for providers to onboard and integrate models is 3 hours, full verification within a day.

The experience is so seamless that you only need a few clicks to get ready.
Tin retweeted
Stats from Liquid Inference’s first few days live:
• Cheaper token prices than 98% of OpenRouter traffic
• ~2B tokens served
• 24 verified providers onboarded to the network
• 88% cache hit-rate
• 26 harnesses/IDEs supported
Buckle up, many new features launching this week.
Tin retweeted

Today we’re launching Liquid Inference, an OpenAI/Anthropic-compatible router where inference providers compete on price for every prompt. Buyers route across 700+ open- and closed-weight models at the lowest available marginal cost, providers onboard instantly to start serving models.
Tin retweeted
Introducing Liquid Inference by Architect, a new LLM model router where inference providers compete dynamically to offer lowest-cost tokens. Providers onboard in minutes, not weeks. Buyers have full price visibility and receive 20% of referred fees in free inference. More info:
Liquid Inference can be used in place of any OpenAI or Anthropic API-compatible backend. Behind it, our team has leveraged our experience trading and building financial exchanges to create real-time two-sided price discovery for inference. Benefits for buyers and providers:
INFERENCE BUYERS
• Fully compatible with agentic coding tools: Claude Code, Codex, OpenCode, Cursor, Pi, Cline, and many more. Full multi-modal support.
• Hundreds of open- and closed-weight models. Create routing rule presets or use our Auto routing algorithms.
• Providers compete dynamically on price for every prompt, offering the lowest marginal cost.
• Sign up for free with email, first 500 users get $20 of free inference.
• Receive 20% of referred fees as free inference, 10% for second-level referrals.
INFERENCE PROVIDERS
• Onboard through the Liquid Inference app. We verify new providers in minutes, not weeks.
• All prompts are OpenAI API standard. Simple REST/Websocket API to register models and quotes.
• Update quotes dynamically based on your own costs. Monetize GPU capacity only when you want.
• Standardize payouts via Stripe, full itemized records of all jobs performed.
Tin retweeted

I stayed up til 2am and spent $1,000 benchmarking Jev Router so you don't have to.
Performance on DeepSWE was roughly the same as GPT-6 Astra on low. It costs slightly more, and it took almost 5x longer to run.


Introducing typesafe/jev-router: a cache-aware model router powered by Jev and @typesafeai
The Jev Router picks the best model and reasoning effort for each request, balancing quality, speed, and cost.
Here's how it works 👇🏻
Tin retweeted

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Tin retweeted

GPT-6 Astra, trained on ~100K+ NVIDIA Grace Blackwell NVLink72. From ChatGPT to o1 to Astra in 4 years.
AGI has arrived. Congratulations @OpenAI team.
400K GPUs coming online next.
Tin retweeted
Architect is hiring for three lateral roles: options trading quantitative researcher, compute capital market sales, and structured derivatives specialist. Details on what we’re building and the new team members we’re looking for
Quantitative Researcher:
We’re building: automated high-frequency options trading strategies on legacy and new(er) exchanges
What you’ll work on: volatility modeling, ML for parameter optimization, order placement simulation, new venue exploration
Stack: Rust, Python, AWS, ClickHouse
What we’re looking for: field experience in derivatives trading and research, strong system design instincts, multiple approaches to options pricing theory, bias towards shipping
Nice to have: familiarity with the latest ML toolkits and exchange microstructure
Location: your preference
Compute Capital Markets Sales:
We’re building: the first US-regulated exchange purpose-built for compute futures, options, swaps, forwards, and capacity, plus AI supply chain commodities
What you’ll work on: building relationships and facilitating trades with neoclouds, lenders, insurance providers, inference companies, datacenters, AI labs, interdealer brokers, retail brokers, hedge funds, and asset managers
What we’re looking for: network of established and startup AI companies, fluency with compute capacity pricing/structures, translation skills between finance and AI, aversion to slop, commitment to competitive markets for compute
Nice to have: experience in compute procurement at a hyperscaler, neocloud, or lab
Location: SF
Structured Derivatives Specialist:
We’re building: specialized contracts for trading and hedging compute, compute derivatives, and a range of physical commodities supporting the US datacenter build-out
What you’ll work on: modeling and structuring OTC products with Architect’s traders/technologists and AI counterparties for compute, memory, inference, and energy trading
What we’re looking for: experience trading OTC derivatives contracts at banks or trading firms, sell-side institutional network, enthusiasm for working at startups
Nice to have: relevant FINRA/NFA certifications or passion for test-taking
Location: your preference
Tin retweeted
LIVE: Join us to watch today's spacewalk as @Astro_Jessica and @Soph_astro work on maintenance outside the International Space Station. xitter.cf/i/broadcasts/1RKZzBVPg…

Tin retweeted

How have software engineering fundamentals changed with agentic coding? Here is our AI Engineering Skills map for software engineering fundamentals.

Tin retweeted
Tungsten is coming to Architect’s AX. Perpetuals, not cubes. Hedge metals supply chain risk at every stage of compute manufacturing: metals mining, chip and memory fabrication, gas generation, electricity consumption, GPU capacity procurement, and inference creation.
Tin retweeted
Hedge funds will eventually provide inference to model routers for free, or even pay to do so, in order to get a first look at prompt contents. Payment-for-order-flow in the age of compute.
