

35K+ YouTube subs | Software Engineer who ships AI apps | Scaling AI first development Agency | DM for AI SaaS development
Joined September 2020
- Tweets1.4K
- Following227
- Followers676
- Likes1.4K




whichever one leaves me with less code to fix.
I’d keep separate defaults for coding and computer use. For code changes, I care more about how much review and rework the result needs than how quickly it finishes.
What does the time to first token look like here?
for short extraction tasks, I’d like to compare total response time as well as tkns/sec.
I was thinking about jev for content moderation, but company classification makes sense too.
how do you handle companies that fit multiple categories or don’t have enough information? cause few startups entire website just says ‘we empower the future’ and nothing else.
my most expensive model can finally stop being a very talented file reader.
but how does escalation work when the cheaper model gets stuck?
I liked the concept but the video quality is pretty bad considering the kind of video models we have right now.
It might work for other than realistic videos.
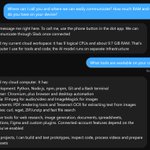
No I haven't cause it doesn't make sense to run small models locally if they can't communicate or delegate tasks to my own subscribed AI agents.
I wish they support my own claude or codex subscription in their hybrid mode.
It'll be awesome to just communicate with one local AI model and It'll distribute tasks to claude code or codex agents.
Right now it only supports models which are on their cloud in hybrid mode.


Anthropic has released Claude Haiku 5.5, scoring 43 on the Artificial Analysis Intelligence Index - up 26 points one year after the last Haiku release
Haiku 5.5 is the first Haiku model with Anthropic’s effort settings and adaptive thinking, and Anthropic has introduced tiered pricing.
Haiku 5.5 is cheaper than its predecessor - it costs $0.10/$0.50 per 1M input/output tokens for prompts up to 100k tokens (the same as GPT-6 Luna and 10% of the previous Haiku model). However, this pricing rises 5x to $0.50/$2.50 above 100k. The site does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon.
Key takeaways:
➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 points
➤ Heavy token use compared to GPT-6 Luna: Haiku 5.5 (max) uses ~162k output tokens per Intelligence Index task, ~3x GPT-6 Luna (max, ~50k). Moving from xhigh to max adds 2 points for ~1.8x the tokens. At similar intelligence it also uses more tokens than GPT-6 Luna: Haiku 5.5 (high) scores 38 with ~55k tokens per task against 38 with ~50k for Luna (max), and the gap widens at lower effort settings
➤ Highly capable at agentic knowledge work: on AA-Briefcase, our private evaluation for realistic knowledge work tasks, Haiku 5.5 (max) reaches 1578 Elo, ahead of models including Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 (max)
➤ Improvements on terminal use: on Terminal-Bench 4.0 it scores 33%, up from 0% for Haiku 4.5. This is level with GLM-5.3 Flash, and ahead of Gemini 3.8 Flash (20%) and GPT-6 Luna (13%)
➤ Lower factual knowledge, but relatively low hallucinations: as expected for a smaller-class model, Haiku 5.5 has lower factual knowledge than its siblings. AA-Omniscience accuracy is 36%, against 55% for Gemini 3.8 Flash and 44% for GPT-6 Luna, but this is partly driven by more willingness to admit when it doesn’t know - its hallucination rate is lower, at 40% against 55% and 77%
➤ AutomationBench-AA result likely understated: Haiku 5.5 scores 35%, against 53–60% for GPT-6 Luna, Gemini 3.8 Flash and GLM-5.3 Flash. During pre-release testing, a safety refusal issue caused the model to over-refuse. Anthropic is working on resolving this - we will re-run this evaluation with the fix, and expect this score to rise
Other model details:
➤ Context window: 1 million tokens, up from 200k for Claude 4.5 Haiku
➤ Pricing: $0.10/$0.50 per 1M input/output tokens up to 100k tokens, $0.50/$2.50 above. Cache reads $0.01 ($0.05 above 100k), 5 minute cache writes $0.125 ($0.625 above 100k)
➤ Multimodality: Text and image input, with text output

Why did @elonmusk feel the need to boost this post?


CodeBucks⚡ retweeted
You’re paying for CODEX and still not using the full limit.
I fixed that with a dot:
1. I made a dot and connected it to 2–3 codex cloud environments
2. I point it at specific gitHub repos. It sends the right tasks to codex in the cloud, then tells me when it’s done or needs my approval.
3. If usage is still left, I ask it to list every task we should finish before the reset. It already knows my work, so the suggestions are actually good. I just pick from the list and send them.
4. It also runs scheduled jobs for me: backlink ideas, SEO fixes, small scripts. Those run on its own VM and report back every day.
5. Same dot handles local codex desktop app too. I tell it the task, it hands it to the right project
The dot is what turns leftover usage into finished work plus I don't open the sidebar anymore nor I have to craft full prompts.

Sorry for the confusion, I meant openAI subscription only. I just shared my review of using the dot.
I guess you can only access dots after they enable for EU users or maybe try VPN?
If you've got a codex subscription, it's worth it. I use it to improve my productivity so I spend less time on prompts and more time delegating tasks.
xitter.cf/code_bucks/status/2106…

You’re paying for CODEX and still not using the full limit.
I fixed that with a dot:
1. I made a dot and connected it to 2–3 codex cloud environments
2. I point it at specific gitHub repos. It sends the right tasks to codex in the cloud, then tells me when it’s done or needs my approval.
3. If usage is still left, I ask it to list every task we should finish before the reset. It already knows my work, so the suggestions are actually good. I just pick from the list and send them.
4. It also runs scheduled jobs for me: backlink ideas, SEO fixes, small scripts. Those run on its own VM and report back every day.
5. Same dot handles local codex desktop app too. I tell it the task, it hands it to the right project
The dot is what turns leftover usage into finished work plus I don't open the sidebar anymore nor I have to craft full prompts.