

Finance and Technology
Dubai/Iasi/Dallas
Joined February 2009
- Tweets449
- Following2.3K
- Followers96
- Likes14.3K




im starting to worry with all this math progress AI might make a fundamental breakthrough in the algorithm used in the show Silicon Valley regarding “mean jerk-time”


Whatever I’m paying for your subscription (just checked, not enough) is not sufficient for the service you do for the community @omarsar0 with this indefatigable work. 💪🔨🧠

Banger paper from Google DeepMind and colleagues.
(bookmark it)
A model reads its entire KV cache on every generated token, even though it ends up attending to a tiny slice of it.
In other words, if you ask about one detail from a 1M-token conversation the global attention layers re-read all of it, per token.
The usual fix is to guess the relevant tokens first with cheap proxy scores, which still costs O(N) every step. Declarative Attention asks the model instead.
The model declares where it needs to look, inside its own chain-of-thought.
In this way, generation splits into three modes: global reads the full context, focus reads one specific region, and local reads only recent output.
The inference engine parses those declarations the same way it parses tool calls and skips most of the cache read.
On zero-shot on off-the-shelf weights across 15 long-context tasks, attended tokens during decoding drop 52.0% on Gemma-4-31B and 31.1% on Qwen-3.6-27B.
Paper: arxiv.org/abs/2609.02737
Chat with Paper: academy.dair.ai/papers/langu…

Interesting thoughts and thanks for sharing (valuable contribution to learning in public) but feel you materially skipped over most important real side-effects of actually running this approach in production: the massive CI/CD skill needed (my longest @mergifyio PR queue was over ~400 items), having to perpetually tune @daytonaio to match land rates and their dev toxic attitude to refuse to offer even paid support to fix problems with their tool (switching to @modal soon probably), if taking a VM approach the isolation and having multiple 2TB machines running simultaneously, potentially dealing with worktrees and branches and agents “disobeying” the gitops playbook if you have one), orchestration/overwatch to “unstuck” a massive run that would otherwise fail at scale due to common issues, telemetry and the autoML infrastructure needed to calibrate and optimize and actually run this thing going forward. GitHub rate limits and being doomed without Linear. Etc. etc. etc. at scale everything breaks.

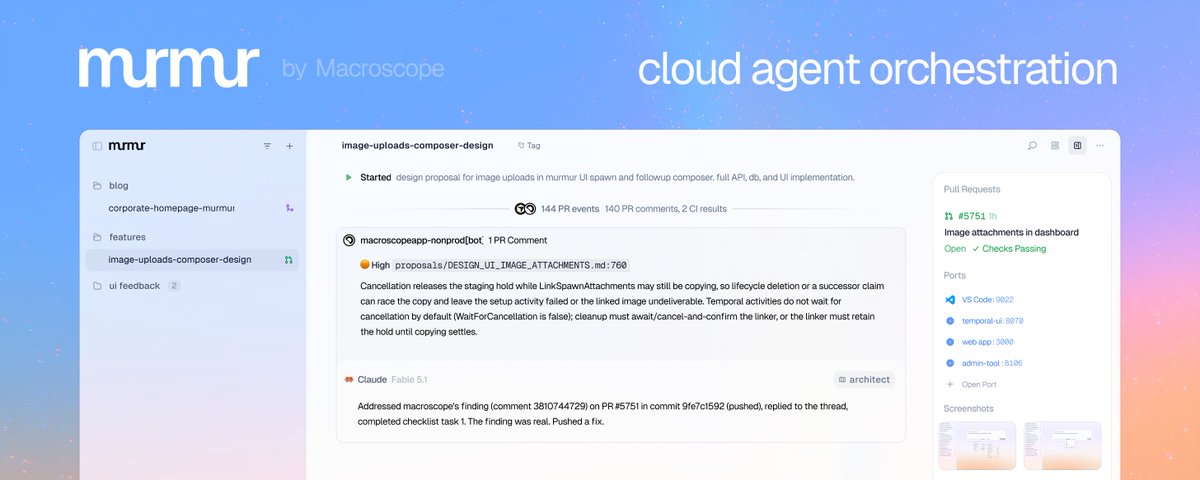
I have been thinking about this a lot after personal experiencing in my “task deconstruction” approach of having a “build queue” driven by issues where Deepseek comparatively underperformed my expectations in my parallel “build cannon” execution system where I observed my landed PR%age produced a materially underperforming $ cost / PR relative ti expected cost as per token and benchmark.


(3/3) [NOW/FUTURE] My “stack” by analogy: f(model):{conscious capitalism, Unitarian Universalism, a mix of unrelenting personal agency with a splash of Uber mensch} * f(harness):{core fundamental business value to create, and share, more value than I absorb} * f(memory):{geographically experiencing multiple countries/cultures through relocation, suffering and its meaning and meaningless/necessity, capitalism vs socialism vs communism as observed second hand, optimism, perseverance} * f(tool-calling):{value aligned recurring habits, “KCE” or knowledge compounding systems, obsession, Jeremy Howard corporate idea factory}. TBU.
(2/3) [PAST] Kant and Locke and Schopenhauer, and more recently Scanlon’s “What We Owe to Each Other”. In Austin, Nietzsche in depth, and a bit of Rene Girard on the side. John Stuart Mill. Hegel.
Over a long enough time period: Spinoza, McAskill, and of course Julian Savulescu.
I live my life and derived my values and behavior framework from Marshall Goldsmith.
(1/3) Philosophy notes from the (uncomfortably warm) dog park: what can I produce about past and future in a shot-gun recall fashion?
Passion project. Big write up. With hallucination rates at low single digits %ages depending on retrieval how do you keep your job with a spreadsheet with 10 tabs, 200 rows and 120 columns that is almost guaranteed to produce wrong answers? Anthropic CFO also struggles.

PROBLEM? AI + Analytics = BAD
SOLUTION? AI + circa 2018 “best in class CIO” tech stack + Analytics = AMAZING
You need to roll up your sleeve and deliver three things: a) AI, and b) technical chops (accounting and finance) with c) mature data background.
Then you see results.

bogdanbaciu.com/thoughts/why…
This is a teaser post. Multi-part series on how to fix this and go from 21% to aprox 98% is coming Q4.

Not often I get to shout out @jeremyphoward twice in a blog post, and seemingly randomly, but his book is the best “implementation” of what is otherwise potentially handwaving using McKinsey’s valuation framework. 6 live worked examples at link. bogdanbaciu.com/thoughts/val…

A little skillopt love with a beginner friendly article on @MSFTResearch effort. As visual and colorful as I could get it (with my wonderful pre-publish technical writer who helps organize and make interactive graphics). Lots of connectors now, easy to try. bogdanbaciu.com/thoughts/ski…


New article, Beginners Guide to Tailscale. @Tailscale at bogdanbaciu.com/thoughts/tai…


