Working on Zep: Context engineering for production AI apps. @zep_ai
San Francisco, CA
Joined June 2007
- Tweets1.4K
- Following1.2K
- Followers2.5K
- Likes3.5K



Daniel Chalef retweeted

Vector RAG only gives agents reliable context when one chunk holds the answer.
It breaks down when answers span data sources or facts change over time.
A temporal context graph connects facts across sources and records when each was true. Full article linked below.
Daniel Chalef retweeted
When an agent answers from a context graph, it's hard to see which facts it used.
Our graph assistant in the Zep dashboard shows each search it runs and the evidence behind the answer.
We launched Zep v4 this week with a lot of new features. See them all below.
Daniel Chalef retweeted

Thank you to everyone who came out to FRC #26 at @pebble_bed for a16z Tech Week. Agents as database users turned into a packed room and a great debate. 🙏
Talks from @danielchalef (Zep), @shulynnliu and @shagarw21 (UC Berkeley Sky). Huge thanks to @Kristopherfloyd and @frontiersynd for organizing.
Next one soon 👀

Daniel Chalef retweeted

Memory layer or a whole new database? We spent FRC #26 arguing about it 🧠🗄️
@danielchalef (@zep_ai) made the case that context is production infrastructure: if your agent can't trust what it remembers, nothing else matters.
@shulynnliu and @shagarw21 brought their CIDR '26 paper from Berkeley Sky. Agents don't really query, they speculate: tons of redundant, exploratory probes. So build the database for the agent first.
Then the room fought over whether those are the same problem. No consensus. Exactly how we like it.
Huge thanks to @constructive_io and @danlynch for sponsoring and @pebble_bed + @nicilevv for hosting 🙏
Great to have @tjskhot @yumi_aw @ryanorban @ezrwolf @damnventures and many other regulars in the room!

Daniel Chalef retweeted
Tonight: Frontier Research Club #26 at @pebble_bed, an official @Techweek_ by @a16z SF session.
Agents in Production: The Data Layer
@danielchalef of @zep_ai on context as production infrastructure: how facts go stale, how provenance and access control actually work, and how you keep an agent off stale or cross-tenant context.
@shulynnliu and @shagarw21 of @UCBerkeley's Sky Lab on "Supporting Our AI Overlords," their paper with Ion Stoica and Matei Zaharia arguing agents don't query like humans, they speculate, so data systems need a rebuild.
A production memory system, then the case for a new kind of database. The room decides if they're describing the same thing.
Hosted by Kristopher Floyd and Dan Lynch, supported by @constructive_io. We're at capacity, waitlist below. Doors 5:30.

Daniel Chalef retweeted

Your memory shouldn't wait for queries.
Every agent memory system today does the same two things. It stores facts and it retrieves the right ones when you ask.
That design assumes you already know what to ask for. You get back exactly what you queried, and nothing about what the stored data adds up to.
Pattern recognition sits outside that loop. It means analyzing the stored facts as a structure and writing down what the structure shows, without waiting for a query to trigger it.
Take a project management assistant reading engineering status updates over one week.
Alice is blocked on the API migration, waiting on the auth service refactor. Bob is blocked on payments, waiting on that same refactor. Clara is blocked on checkout, which is waiting on Bob's payments work.
Every claim gets stored correctly and retrieved correctly. Ask what is blocking the team and all six lines come back, accurately.
None of them say that unblocking one task clears all three people. Clara never mentions the auth service, so she sits two hops away from the actual cause.
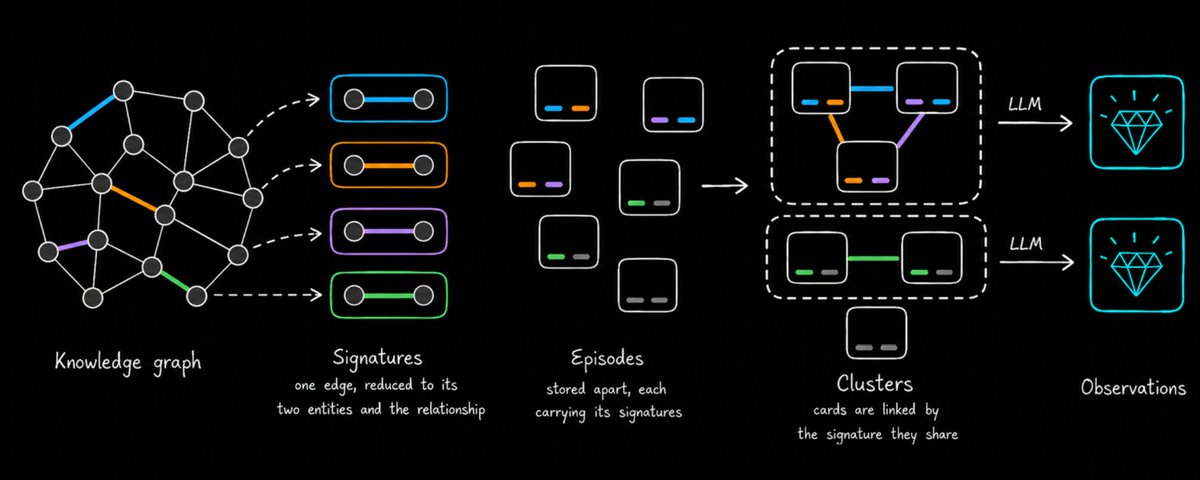
Nobody was going to query for that, because nobody could name it yet. Closing the gap takes a pipeline running on top of retrieval rather than a better retriever, and the visual above lays out its four stages.
→ Raw episodes are the ingested material, the actual messages, JSON payloads, and documents. A knowledge graph gets built out of them, with entities as nodes and claims as labeled edges between them.
→ Signatures reduce each edge to its two entities plus the relationship type. Alice's update carries (API Migration, Auth Service), Bob's carries the same one, and that shared pair is the only thing that matters at this stage.
→ Clusters link episodes that share a signature. Alice and Clara have no entity in common, and they still land in the same cluster because Bob's update touches both sides and bridges them.
→ Observations are written per cluster by a single constrained LLM call. The model receives the entities and the supporting conversations, then names the pattern and summarizes it.
Everything before that last step is plain graph topology, with no embeddings and no similarity scoring. That distinction carries weight, because embedding-based clustering would group all three updates simply for being about engineering work, along with every other update that week.
This runs in the background as new data lands, so the pattern is already written by the time anyone thinks to look for it.
The real shift is from retrieving what people said to analyzing what their combined data shows.
Zep ships this as a feature called Observations, and the graph engine underneath is open source as Graphiti. Observations are read-only, since they are structural properties of the graph rather than notes anyone maintains, so contradicting evidence retires the old one and the pattern reforms around whatever is blocking work now.
Check it out on GitHub: github.com/getzep/graphiti
I wrote the full breakdown of how the clustering works. The article is quoted below.
Stay tuned for more on this!

Daniel Chalef retweeted

Provenance is the thing that gets destroyed when an LLM synthesizes. The output fact often doesn't appear verbatim in any source, so the paper trail is gone. . @danielchalef, founder and CEO of Zep AI, works through that problem in "Citation Needed: Provenance for LLM-Built Knowledge Graphs", on @aiDotEngineer's YouTube. If you're building agent memory or context pipelines and someone has asked you where a fact came from, this talk gives you a concrete data model for answering.
- The failure mode is a clean, confident fact. An agent returns "patient has a penicillin allergy" synthesized from an EHR record, a PDF lab report, and something the patient typed into an intake chat. Without the source, a doctor could be misled.
- A source ID on the fact doesn't survive. That works in a data warehouse where one value is copied deterministically. With LLM pipelines, entities merge, new data invalidates old facts, and the store keeps changing under your pointer.
- Model lineage as graph relationships, not a log. In Graphiti, sources are episodes, entities and edges hydrate into facts, and tracing a fact to its source is just a graph walk.
- Mutation is where lineage silently breaks. When two entities merge, the merged entity has to keep source links from both. When new data contradicts a fact, Graphiti adds an invalid-at date and records which episodes caused the change.
- Tag once at ingestion, filter for the rest of the graph's life. An EHR tag on an episode is inherited by every entity and fact derived from it, so an agent can retrieve only facts from verified clinical sources.
- Multi-parent facts need your business rules, not the graph's. Two facts with three parent episodes each can demand opposite policies: any unverified source should block a prescription, but every parent must be verified for consent on file. Graphiti exposes which episodes carry the tag; the agent applies the rule.
- Deletion becomes a rule you can actually apply. For a right-to-be-forgotten request, a fact is deleted only if no remaining episodes support it. The allergy fact survives with two parents left; a fact derived solely from the deleted source goes.
- File-based memory breaks down here. Daniel makes the case that markdown works for desktop and single-agent use, but mutating lines in a file makes it very hard to reconstruct why a change occurred across multi-agent, multi-user, multi-source setups.
- The pipeline avoids LLMs where it can. Extraction is single-shot, then a dedup and de-confliction pass uses traditional information retrieval and NLP techniques, entropy and hashing among them. Cheaper, faster, more deterministic.
I'm working through the published talks from AI Engineer World's Fair sharing summaries and takeaways. Follow for more!
Daniel Chalef retweeted
Zep now ships one plugin for Claude Code, Codex, and Cursor. Your coding agent uses it to design and implement Zep in your codebase.
It bundles two things: the Zep documentation MCP server, and a new skill called building-with-zep that encodes the architectural decisions. 🧵

Daniel Chalef retweeted

🆕 Live now: our entire AI x Graphs Track!
@emileifrem, CEO, Neo4j
@yoheinakajima, Managing Partner, Untapped Capital
@danielchalef, Founder & CEO, Zep AI
@le_james94, Head of DX, TwelveLabs
@coyle_frankp, Lecturer, UC Berkeley
Mike Phipps, Lead AI Engineer, Gates Foundation
Ritvik Pandya, Engineering Manager, JP Morgan Chase
Omri Bruchim, Engineering Group Manager, Monday
@steveonjava, VP of Developer Relations, Neo4j
@SQuoraishee, Staff Engineer, The New York Times
Joanne Song, Android Engineer, The New York Times
Subbiah Sethuraman & Abhilash Asokan, ZS Associates
full track drop below!


Daniel Chalef retweeted
Agent memory is synthesized: an LLM reads chat history, documents, and business data, and derives the facts your agent retrieves. The output appears in none of the sources verbatim.
By retrieval time, the source behind a fact is gone. Here's how Zep keeps it. 🧵


Daniel Chalef retweeted

getzep/graphiti:
framework for building and querying temporal context graphs for AI agents
Daniel Chalef retweeted

The more your agent remembers, the less it knows.
This sounds counterintuitive, but it is actually a direct result of how agent memory is built today.
Most agent memory systems optimize for recall. The harder problem is what to forget, or more precisely, what to never store in the first place.
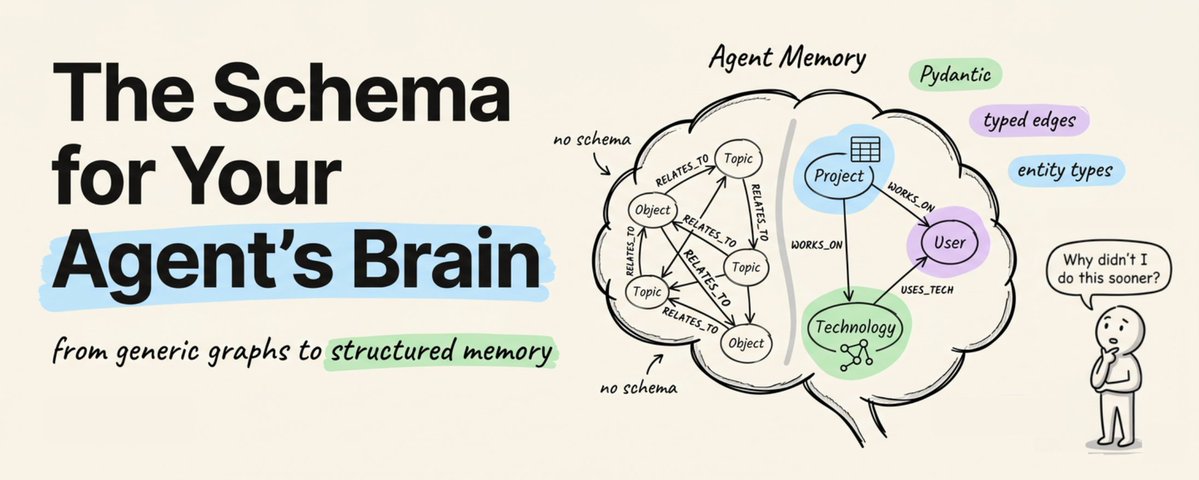
The default agent memory pipeline hands an LLM raw text and asks it to extract entities and relationships. The model decides the types, the labels, and the attributes, all on its own.
This typically gives a knowledge graph that behaves like an expensive vector store. Entity types collapse into generic labels. Relationships flatten into a single "RELATES_TO."
The graph has the data, but no query can reach it with precision.
This is not a retrieval problem but rather a structure problem. And the fix is the same pattern that already works everywhere else in the AI stack, i.e., constrain the output space before generation, not after.
> Entities define what the agent is allowed to remember. Pydantic models with typed fields and descriptive docstrings replace the LLM's guesswork with domain vocabulary it was never trained on.
> Edges define how things connect. Source/target constraints on relationship types mean the graph can only form valid connections. If your schema has no edge connecting Project to Competitor, that relationship cannot exist in memory.
> Temporal resolution handles what was true versus what is true. Fact resolution invalidates outdated edges while preserving history, so the graph never silently serves a stale state.
The schema guides extraction at two points in the pipeline (entity extraction and fact extraction) while resolution and temporal processing run automatically downstream.
You define what to look for. The system handles deduplication, contradiction detection, and time-windowing without additional configuration.
A useful constraint is to have just 10 entity types, 10 edge types, and 10 fields per type.
That forces you to model the 80% that matters rather than attempting completeness. Start with 3-4 of each and expand only when retrieval fails.
Graphiti does all of this as a fully open-source (with 29k stars) temporal knowledge graph library.
It implements Pydantic-based ontology definition, schema-guided extraction, entity resolution, fact resolution, and temporal windowing that I described above.
Graphiti Repo: github.com/getzep/graphiti
(don't forget to star 🌟)
Agent memory without schema discipline is storage without structure. The schema is what turns a pile of facts into a queryable model of your domain.
So if you are building agent memory with any kind of domain specificity, schemas are a must. My co-founder covered this topic in more depth in an article.
Read it below.