

CSE ( AIML ) -Mumbai University Linkedin : https://teapawt.net/t.co/UeoksWFSWg GitHub: https://teapawt.net/t.co/LdyNBQyQeD
Navi Mumbai
Joined June 2019
- Tweets168
- Following115
- Followers32
- Likes250



Pinned Tweet
Can't Find perfect music for your videos ? why not just generate it for free on BEATFLOW
go now 👉 beatflow.art/

Mohammad Kaif | FullStack Developer | GEN AI retweeted

As an AI engineer, please learn:
- Learn the roofline model and why decode is memory-bound
- Deploy vLLM and SGLang, then read their schedulers
- Understand paged attention from the code, not the blog post
- Build observability before you optimize anything
- Track TTFT, inter-token latency, throughput, queue depth
- Use Grafana + Prometheus for inference dashboards
- Turn on prefix caching and find which workloads it helps
- Learn continuous batching and chunked prefill
- Run load tests with 1000+ concurrent requests
- Report p50, p95, p99, never just the mean
- Master quantization tradeoffs (FP8, INT4, AWQ, GPTQ)
- Learn speculative decoding and where it stops helping
- Set up KV cache eviction for long contexts
- Try disaggregated prefill and decode serving
- Learn Kubernetes for AI workloads and autoscale on queue depth
- Learn how inference costs break unit economics
- Build your own model router by cost, latency, quality
- Create a token budgeting system per request
- Build one inference service and benchmark it publicly
- Read inference research instead of model release news
- Start sharing your optimization benchmarks
I put together a 10-week plan that covers every one of these at 30 minutes a day. It is 50 sessions, split between reading the theory and building on your own service, and all of them feed one artifact: an inference service you deploy, instrument, load test past 1000 concurrent requests, tune, and publish as a reproducible benchmark.
It is open on GitHub and contributions are welcome, especially newer sources worth adding. I am working through it myself and will share more content on this going forward, so stay tuned.
GitHub repo: github.com/patchy631/time-to…
(don't forget to star 🌟)


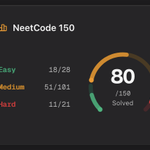
12 days into grinding Neetcode 150, and I’ve finally crossed the halfway mark.
Started it to revise DSA, but ended up learning a lot of new stuff. Great sheet ngl.
How relevant is Neetcode 150 for tech interviews in India tech interview setup?


My current mental model of a transformer:
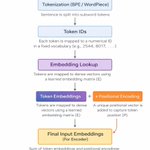
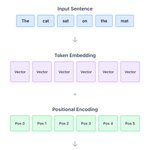
Text → tokens → token IDs → embeddings + positional information → transformer
Embedding: what the token is.
Position: where the token is.

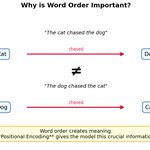
"The dog chased the cat" and "The cat chased the dog" contain the same tokens, but mean different things.
The order changes the meaning.
That's why positional information is important: the model needs to know not only which tokens exist, but where they appear.

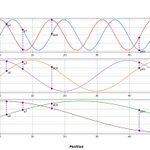
When generating sinusoidal positional encodings, we use different sine and cosine frequencies across the embedding dimensions.
Some dimensions change quickly, while others change slowly.
Together, these patterns give each position a unique representation of its position.

During positional encoding, we can use sinusoidal functions to represent each position.
Sine and cosine generate different patterns across the embedding dimensions.
Each position gets a distinctive pattern, giving the transformer information about where each token appears.

Positional encoding gives each token information about its position in the sequence.
So the transformer receives both:
what the token is + where it appears
This helps it understand the order and relationships between tokens.

Moving from token embeddings to positional information.
A token embedding tells the model what a token represents, but not where it appears.
Since transformers process tokens in parallel rather than sequentially, the model needs positional information to understand their order.
🤖 Made with AI

Moving from tokenization to embedding was interesting.
A token ID points to a row in the embedding matrix, and that row becomes the vector representation of the token.
So instead of working with cat = 42, the model works with a high-dimensional vector associated with that token
The embedding dimension is the number of values used to represent each token.
50,000 tokens × 768 dimensions
gives a 50,000 × 768 embedding matrix with 38,400,000 parameters.
Each row has 768 values representing the token at that token ID. The ID simply points to that row.
The embedding matrix it's basically:
-> vocab size × embedding dimension
Vocab size = the number of tokens in the tokenizer's vocabulary.
Each row corresponds to one token, and the row contains the vector representation for that token.
Learned about token IDs and what happens after tokenization.
flow : text → tokens → token IDs
A token ID isn't the meaning or representation of the token. It's basically an index that tells the model which token it is and which row to look up in the embedding matrix.

Learning about tokenization helped me understand the "strawberry" problem.
An LLM can struggle to count the "r"s because the word may be split into multiple tokens.
The model doesn't see the original word as one unit.
More of a architectural issue than the LLM being "stupid."

Spent some time learning about BPE and how tokenizers build their vocabulary by merging frequently occurring pairs.
Also played around with tokenizers to see how normal sentences, spaces, contractions, and weird strings actually get split.

Been learning the basics of how LLMs process text.
Started with tokenization and went through character-level, word-level, and subword approaches.
Subword tokenization makes a lot more sense to me now, especially when dealing with unknown words, typos, and different word forms.
DSA Grind Update: Finally completed DP.
Memoization was crazy, tabulation almost killed me 😭
I’m starting to understand DP a bit better now. Still need a LOT more practice though.
DP learning: done. Time to grind.


It was a great session. Learned a lot, stressed a lot 😭
Late-night prep, mocks & scripting, but glad it all worked out.
Happy to have co-hosted Solana Across Campuses with @syscallr !

Hosted & spoke at Solana Across Campuses - Smt. Indira Gandhi College of Engineering!
Introduced students to blockchain, Web3 & Solana from the basics.
Thanks @dev_kaif_ , @CollegeXYZ & @SolanaFndn for the support and opportunity!
#Solana #Web3


DSA Grind Update:
Graph patterns done for now.
Covered DFS, BFS, shortest paths, Dijkstra, Bellman-Ford, MST, topological sort, cycle detection, bipartite graphs, and more.
Now moving on to Dynamic Programming.
leetcode.com/u/Dev-kaif/


