




Pinned Tweet
Day 2/365 of robot learning: I taught my SO-101 arm to pick up a die 🎲
Trained an ACT model on 50 teleop demos. Used a ~$20 webcam, modified it to not autofocus (shifts the details between demos and test runs and I wanted to remove external influencing factors).
Scored ~55% success rate (~5-6 successes of every 10 runs). A success was defined as the die being placed within the box drawn on the tape. The video below was counted a success.
The arm grabs the die and moves it from one tape to the other. Its favorite mistake is grabbing the air next to the die, maybe it needs another set of eyes👀
Next step: fine-tuning a π0.5 model to see if VLA helps with accuracy. Might try a wrist camera as well.

trained my robot arm on 101 demos of a pick and place task and all I taught it was to be dumb.
It only learned it was supposed to go from point A to point B and make the grasping motion.
So today I recorded 25 more with the die in a random place each time, and it learned to actually look. It also implicitly seemed to understand when a task wasn't completed and would retry.
Pretty obvious that this works but I'm surprised at how dumb it was without making it explicit.
Next step: getting the gripper to actually lock on to the die when picking up. It keeps missing by 1-2 cm.
Trying it with a wrist camera!
teapawt.net/drdonv1/status/2120389…

day 5/365 of robot learning
I've been wondering if imitation learning still worth it? Or is it time I ditch to RL?
I've been facing some issues getting my SO-101 to perform a simple pick and place task accurately (>90% successes).
At 25 episodes of training the ACT model, I was seeing roughly 55% success. Now that I've increased to 100 episodes, that success number fell even lower.
Tonight I'm going to try changing the background to a plain white one. I'm also going to swap out the yellow die to a blue die.
I might even give a shot at using a wrist camera to help increase the accuracy of a pick. Any other suggestions on what I can change? Maybe it's the angle at which the overhead mount sees the scene?
If these don't work I guess RL wins?
Below is a video of my arm with 100 episodes of training
2
52
robotics to the moon, it's gonna be so cheap in a couple years

The start of something new
A family of affordable American Robots
Pre-order Origin now at hiroindustries.com/ for $450
3
127
day 5/365 of robot learning
I've been wondering if imitation learning still worth it? Or is it time I ditch to RL?
I've been facing some issues getting my SO-101 to perform a simple pick and place task accurately (>90% successes).
At 25 episodes of training the ACT model, I was seeing roughly 55% success. Now that I've increased to 100 episodes, that success number fell even lower.
Tonight I'm going to try changing the background to a plain white one. I'm also going to swap out the yellow die to a blue die.
I might even give a shot at using a wrist camera to help increase the accuracy of a pick. Any other suggestions on what I can change? Maybe it's the angle at which the overhead mount sees the scene?
If these don't work I guess RL wins?
Below is a video of my arm with 100 episodes of training
1
1
139
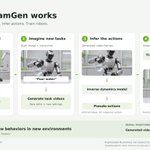
currently waiting over 8 hrs for my pi0.5 model fine tuning to be scheduled on shared GPUs from school. Seeing that everyone shipped an online version of WAMs this week, decided to go back to one of the fundamental papers and understand the basics: DreamGen by @NVIDIARobotics .
day 4/365 of robot learning.
DreamGen is a pipeline to make open-world generalization possible. This means we one day wouldn't have to teach a robot every skill specifically, just one general skill it can apply to many things. For instance, pouring a cup of water and pouring a jug of water into a vase are almost the same task, and DreamGen helps a robot treat it like such.
DreamGen is divided into 4-steps:
1. Fine tune the video world models on a target robot, learn the dynamics of the robot
2. Prompt the models with initial frames to generate robot videos that behaviors in the target domain, but also new behaviors in new environments. AKA generate videos in the desired target space + enable new behaviors in new spaces.
3. Extract "pseudo robot actions" via latent action model, or inverse dynamics model.
4. Use the videos labeled with pseudo actions, named as neural trajectories, to help with downstream visuomotor policy learning.
AKA first tune video world models to understand the robot they're in, then have it imagine the robot performing a task, and then label the videos with pseudo actions to teach the robot a skill.
They lowered the barrier of entry required for data. You only need around 10 teleoperated examples per task. You do need thousands of demos up front (even of just one task, like pick-and-place) for the video model to learn the robot's dynamics.
However, the researchers note that it's computationally intensive (240k RoboCasa samples took 54 hrs on 1500 L40 GPUs). This cuts down the need for teleop data but replaces it with compute.
A couple questions I had - is it possible for DreamGen to create and subsequently train on hallucinated videos with poor physics in them? What if we introduced a step that verified each video's physics?
Since DreamGen found success rising in linearly against the log of the generated trajectories, at what point does a GPU beat a person with a teleop rig?
How precise can we get the hallucinated videos to be? One problem I'm facing with the SO-101 is the gripper being 1-2cm off of the pickup, and botching the entire task.

Reinforcement learning has been interesting on the PushT game...
day 3/365 of robot learning
I've tried 4 different reward systems for teaching a model to win at PushT via RL. The threshold to cross is 95% coverage, yet every reward system seems to fail it.
Running 2 million steps per reward system on an M2, here are the results:
Attempt 1: Reward increases linearly as coverage gets closer to 95% → ~80% coverage, wins up to 1 in 20. Winning ends the game, so hovering near 90% earns more points than actually winning.
Attempt 2: Same as above, but −1 for every move, so winning is the only way to stop paying → ~73%. It rarely got close enough to 95% to find out that winning stops the penalty.
Attempt 3: Curved reward (also −1 per move). The last few % before 95% pay the most, since the reward grows steeply near the top → ~10%. The reward was so small below 50% that it never learned anything.
Attempt 4: Half coverage, half how close the T's position + angle are to the goal (−1 per move) → ~87% coverage, passing 90% in over two-thirds of its practice games. Still only wins up to 15% when tested.
It's consistently getting between 80-93% and then stopping... It gets close but rarely actually finishes and succeeds.
Through the process I also learned about SAC which rewards the model for staying a bit random so it keeps exploring, rather than settling on a strategy too early. Pretty cool stuff.
Any thoughts on other reward mechanisms I can try to help this learn better? Or is the solution simply more steps?
1
1
129
How my SO-101 is currently going: teapawt.net/drdonv1/status/2118614…
Day 2/365 of robot learning: I taught my SO-101 arm to pick up a die 🎲
Trained an ACT model on 50 teleop demos. Used a ~$20 webcam, modified it to not autofocus (shifts the details between demos and test runs and I wanted to remove external influencing factors).
Scored ~55% success rate (~5-6 successes of every 10 runs). A success was defined as the die being placed within the box drawn on the tape. The video below was counted a success.
The arm grabs the die and moves it from one tape to the other. Its favorite mistake is grabbing the air next to the die, maybe it needs another set of eyes👀
Next step: fine-tuning a π0.5 model to see if VLA helps with accuracy. Might try a wrist camera as well.
24
Reinforcement learning has been interesting on the PushT game...
day 3/365 of robot learning
I've tried 4 different reward systems for teaching a model to win at PushT via RL. The threshold to cross is 95% coverage, yet every reward system seems to fail it.
Running 2 million steps per reward system on an M2, here are the results:
Attempt 1: Reward increases linearly as coverage gets closer to 95% → ~80% coverage, wins up to 1 in 20. Winning ends the game, so hovering near 90% earns more points than actually winning.
Attempt 2: Same as above, but −1 for every move, so winning is the only way to stop paying → ~73%. It rarely got close enough to 95% to find out that winning stops the penalty.
Attempt 3: Curved reward (also −1 per move). The last few % before 95% pay the most, since the reward grows steeply near the top → ~10%. The reward was so small below 50% that it never learned anything.
Attempt 4: Half coverage, half how close the T's position + angle are to the goal (−1 per move) → ~87% coverage, passing 90% in over two-thirds of its practice games. Still only wins up to 15% when tested.
It's consistently getting between 80-93% and then stopping... It gets close but rarely actually finishes and succeeds.
Through the process I also learned about SAC which rewards the model for staying a bit random so it keeps exploring, rather than settling on a strategy too early. Pretty cool stuff.
Any thoughts on other reward mechanisms I can try to help this learn better? Or is the solution simply more steps?
Starting on a journey to get good at robot learning, today is day 1/365. s/o @praneethsamine for the idea
how far can a diffusion policy's denoising steps be cut on PushT before it starts to lose? Reduced denoising makes planning faster.
Results showed roughly 19x faster with no measurable drop.
Context: PushT is a game where a round pusher has to shove a T-shaped block onto a T-shaped target. A game counts as a win if the block covers at least 95% of the target within 300 moves. The number of steps N is how many rounds of refinement the model does each time it plans. Each plan covers its next 8 moves.
I tested this today. 100 games each time, with the pretrained HF Lerobot Diffusion Policy. I had the following step levels: 100 steps, 50 steps, 25, 10, and 5. Ran it on my M2 MacBook, DDPM scheduler.
Results:
- 100 steps: 73% success rate. This is the baseline, 4.3 s per plan.
- 50 steps: 65% success, 2.2 s per plan.
- 25 steps: 60% success, 1.1 s per plan.
- 10 steps: 68% success, 0.43 s per plan.
- 5 steps: 70% success, 0.22 s per plan, 19x faster than the baseline.
Not a new idea: the Diffusion Policy paper (Chi et al., 2023) already runs 10 DDIM steps on real robots.
Difference: I kept LeRobot's default DDPM scheduler, and 5 steps held up.
Caveat: most losses were near-misses that ran out of moves by the 94-95% threshold. A small drop can't be ruled out by 100 games.
Next: taking this to my senior project, a LeRobot arm moving a die. Does 5 steps hold up on real hardware?
full 500 runs in the replies
29
Starting on a journey to get good at robot learning, today is day 1/365. s/o @praneethsamine for the idea
how far can a diffusion policy's denoising steps be cut on PushT before it starts to lose? Reduced denoising makes planning faster.
Results showed roughly 19x faster with no measurable drop.
Context: PushT is a game where a round pusher has to shove a T-shaped block onto a T-shaped target. A game counts as a win if the block covers at least 95% of the target within 300 moves. The number of steps N is how many rounds of refinement the model does each time it plans. Each plan covers its next 8 moves.
I tested this today. 100 games each time, with the pretrained HF Lerobot Diffusion Policy. I had the following step levels: 100 steps, 50 steps, 25, 10, and 5. Ran it on my M2 MacBook, DDPM scheduler.
Results:
- 100 steps: 73% success rate. This is the baseline, 4.3 s per plan.
- 50 steps: 65% success, 2.2 s per plan.
- 25 steps: 60% success, 1.1 s per plan.
- 10 steps: 68% success, 0.43 s per plan.
- 5 steps: 70% success, 0.22 s per plan, 19x faster than the baseline.
Not a new idea: the Diffusion Policy paper (Chi et al., 2023) already runs 10 DDIM steps on real robots.
Difference: I kept LeRobot's default DDPM scheduler, and 5 steps held up.
Caveat: most losses were near-misses that ran out of moves by the 94-95% threshold. A small drop can't be ruled out by 100 games.
Next: taking this to my senior project, a LeRobot arm moving a die. Does 5 steps hold up on real hardware?
full 500 runs in the replies