

ML @
Zurich, Switzerland
Joined December 2016
- Tweets824
- Following390
- Followers1.9K
- Likes3.2K





Erik Daxberger retweeted

📢laplace-torch 0.4 is out! Uncertainty on diffusion & language models? Now supported!
See examples: aleximmer.github.io/Laplace

Erik Daxberger retweeted

We're hiring for MINT-Zürich 🇨🇭 @Apple , interns + full-time to build multimodal foundation models, with research across pre-training, post-training, agents, and world models!
Email us at [email protected] with CV + relevant work, and apply to jobs.apple.com/en-us/details…
At #CVPR2026 in Denver this week btw, feel free to say hi 👋

Erik Daxberger retweeted
Excited to release Weblica! Two recipes for scaling visual web-agent training, bypassing live-web slowness and irreproducibility: deterministic HTTP cache replay, and generating thousands of diverse synthetic envs automatically using Claude Code.

Excited to share Weblica, a framework for scalable and reproducible training environments for visual web agents!
📄 arxiv.org/abs/2605.06761
Erik Daxberger retweeted

Excited to share Weblica, a framework for scalable and reproducible training environments for visual web agents!
📄 arxiv.org/abs/2605.06761
Erik Daxberger retweeted

In this report we describe the 2025 Apple Foundation Models ("AFM"). We also introduce the new Foundation Models framework, which gives app developers direct access to the on-device AFM model.
machinelearning.apple.com/re…

Erik Daxberger retweeted
At WWDC we introduce a new generation of LLMs developed to enhance the Apple Intelligence features. We also introduce the new Foundation Models framework, which gives app developers direct access to the on-device foundation language model.
machinelearning.apple.com/re…

Erik Daxberger retweeted

#ICLR2025 The philosophy behind O3 is beautifully simple and powerful! Our long-video MM-Ego VLM actually also includes an implicit VIDEO REASONING process 🤣: it first takes a quick overview of the entire long video, then ZOOMS IN on key visual details with question in mind🧐

Erik Daxberger retweeted

🚀 Model and data for our CubifyAnything project are now released!
🔗 github.com/apple/ml-cubifyan…
#SpatialReasoning #3DObjectDetection #transformers #detection #ai #genai
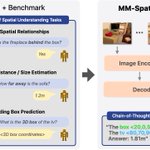
Check out our new work on exploring 3D Spatial Understanding with Multimodal LLMs!🚀
📀CA-VQA: A fine-tuning dataset and benchmark w/ various input signals and spatial tasks.
🤖MM-Spatial: A generalist MLLM excelling at spatial reasoning.
🔗arxiv.org/abs/2503.13111
🧵(1/n)

🤖Quantitative eval. shows that MM-Spatial's depth estimates are indeed pretty accurate, even rivaling those of specialist monocular depth estimators. This suggests that multimodal LLMs can learn strong monocular depth estimation in a purely data-driven way via SFT.
(8/n)

1
168
🚀Check out our paper for more and stay tuned for our data release!
🔗arxiv.org/abs/2503.13111
Great effort with amazing collaborators Nina Wenzel, David Griffiths, @HaimingGang, Justin Lazarow,
Gefen Kohavi, Kai Kang, Marcin Eichner, @yinfeiy, @afshin_dn, Peter Grasch.
(9/9)

1
158
Erik Daxberger retweeted
It's official! Our foundational model for egocentric video understanding will be showcased at #ICLR2025 in Singapore! 😃 Huge thanks to my incredible mentors at Apple 💕❤️🔥🤗

Thanks @zhegan4! We intro the first egocentric MLLM with a data engine for large-scale egocentric QA, a challenging QA benchmark with a de-language-bias evaluation, and a specialized model using pointer networks for progressively understanding long videos.
Erik Daxberger retweeted

What matters for runtime optimization in Vision Language Models (VLMs)? Vision encoder latency 🤔? Image resolution 🤔? Number of visual tokens 🤔? LLM size 🤔?
In this thread, we break it all down and introduce FastVLM — a family of fast and accurate VLMs.
(1/n 🧵)

ALT Comparison of commonly used vision encoders for VLMs with Qwen2 0.5B LLM. All the vision encoders are CLIP pre-trained. For a fair comparison all models are trained using LLaVA-1.5 setup with the vision encoders made trainable for resolution adaptation. Marker size for each model corresponds to number of parameters of the vision encoder. The x-axis is the sum of vision encoder latency and LLM pre-filling time. All models are benchmarked on an M1 Macbook Pro.
Erik Daxberger retweeted

We release AIMv2, the second iteration of the AIM family of large autoregressive vision encoders. This time we bring multimodality into the game 🔥
Paper: arxiv.org/abs/2411.14402
Repo: github.com/apple/ml-aim
Model Gallery: huggingface.co/collections/a…
