

post-training @ Lovable | adjunct prof @ Aalto | ex-Google DeepMind
Helsinki, Finland
Joined October 2012
- Tweets364
- Following860
- Followers1.2K
- Likes474
Diffusion models allow us to naturally condition the generation of the puzzles with a partial board, best move, and themes.
Try out our demo at: chess-puzzle.k8s-test.cs.aal…
4/n


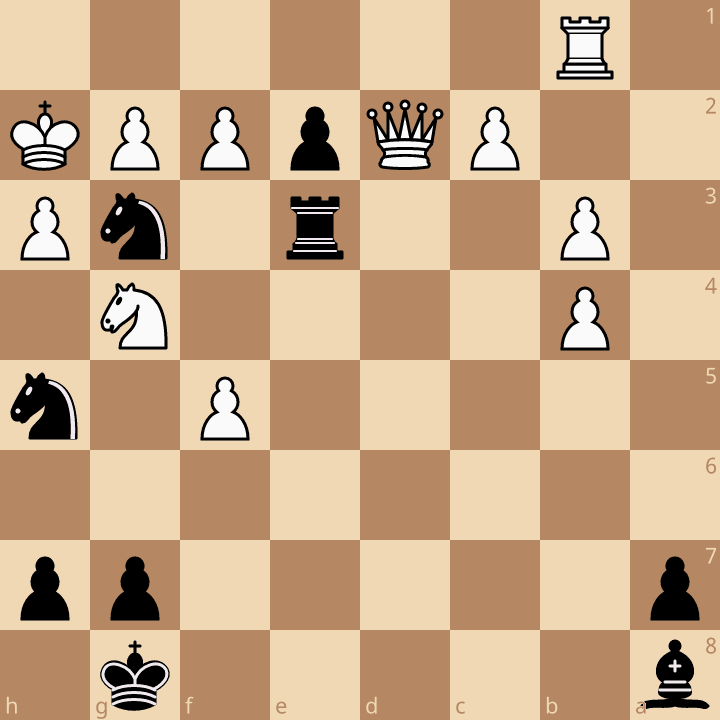
🚨 New preprint on creative chess puzzle generation with diffusion models is out! ♟️
In his exceptional MSc thesis, @AatuSelkee introduced a new RL recipe on top of a masked diffusion model improving the previous SOTA.
We're open-sourcing the model and releasing a demo 🚀
1/n

- is recurrence making a comeback in LLMs?
- how does Kyunghyun select problems to work on?
- advice for students
- why was coming to Finland 🇫🇮 among the best decisions he has made?
Youtube: youtu.be/a5oKBtp14MA?si=jzrK…
Spotify: open.spotify.com/episode/3US…

1
1
370
I had the privilege of sitting down with @kchonyc for our new AI podcast "And humanity created intelligence". we discussed the backstory behind the attention paper as well as... 🧵


thank you for the recognition @GaryMarcus!
there's room for improvement, but I find it quite remarkable that an LLM learns to play creative sacrifices like this (best move according to Stockfish)


@ericmalmi has kind of done that and it does pretty well except in weird positions - where it still sometimes make illegal moves.
Confirming your conjecture and mine, if I understand his results correctly.
arxiv.org/pdf/2412.12119v2
10
599
our work establishes new test-time scaling results for chess-playing LLMs ♟️📈 honestly, I think it's quite mind blowing that an LLM can learn to perform minimax tree search within a single model call and smoothly improve its Elo the more output tokens you give it 🤯

multiple long-time dreams coming true at once:
✅ give a talk at NeurIPS
♟️ play chess on a stage
🤡 make my international debut as a rapper
thanks to the audience for a lively discussion that went on for a good hour after the talk and to my amazing co-presenters @anianruoss @weballergy @MatejJusup!

if you're at #NeurIPS2024, want to learn how to make LLMs really good at chess and see a live demo, come and visit the @GoogleDeepMind booth tomorrow at 9:30 am!

Language models can't play chess, right?♟️ Excited to share our latest experiment that let's you play chess against a Gemini model!

Multimodal LLMs pose new safety challenges as adversarial prompts can be hidden into images. A thought-provoking talk by @YueDongCS. #KDD2023

ChatGPT:n kaltaiset kielimallit on puolestaan opetettu vastaamaan käyttäjän esittämiin kysymyksiin. Artikkeli toteaa oikein, että tämä johtaa toisinaan hallusinoinniksi kutsuttuun ongelmaan.

1
52
Artikkelin luoma vastakkainasettelu ChatGPT:n kaltaisten kielimallien ja sääntöpohjaisten järjestelmien välillä on väkinäinen, sillä tyypillisesti näitä käytetään eri käyttötarkoituksiin.

1
58
in fact, this idea appears already in Stern et al's (2018) work on Blockwise Parallel Decoding
arxiv.org/abs/1811.03115

1
4
673
you can tell that a lot of #NLProc researchers are looking into speeding up LLM decoding when *at least* 4 groups independently publish similar ideas.
so what's the key insight💡all these papers build on? 🧵

@flowritecom tulee ensimmäisenä mieleen. Vedin viime vuonna kurssin tekstingenerointiin liittyen (youtube.com/watch?v=Ydur1gPT…) Aallossa ja siellä on kyllä paljon osaavia ja motivoituneita opiskelijoita!

5
61
even T5 small 👶 can significantly benefit from Chain-of-Thought reasoning when trained on CoTs generated by an LLM 🧑🍼!
recent work by our intern Charlotte Magister:
arxiv.org/abs/2212.08410

