Tech guy with a blueprint and a pulse. Building @firsttensor
Europe
Joined December 2023
- Tweets363
- Following397
- Followers888
- Likes2.1K




Pinned Tweet
Back in 2022 I've invested a shit amount of money and time into $TAO as I saw the potential right there (thanks Dread).
I've invested my own savings and also I was crazy enough to get the biggest loan that I could from ING Romania and I've invested ALL of it into #Bittensor.
In 2023 I've decided to quit my DevOps Engineer job and get back my time and freedom. I've managed to do all that with the help of TAO.
Fast forward almost 5 years, it was all worth it!
$TAO above $300, 1st halving done, almost 4 billion marketcap, 128 subnets, and revenue increasing each month.
Now in 2026 I've invested a shit amount of money and I plan to invest a shit amount of time also into #GenesisL1!
Why? Because I can see the potential right here! I can see the roadmap, I can see what the project can do in the next 2-3 years. It gives me the TAO feelings!
At $5mil marketcap is the next big thing right there!
You might want to learn more about it and invest if you also see the potential in it.
Cheers!


Eseck retweeted

1. Start by purchasing base:0xe6522a891702cd2e8cc2a5182638c9da1dd44b22 on Base.
2. Next, send it through the GenesisL1 bridge.
3. After bridging, your wallet receives native genesisl1:native on GenesisL1.
4. This native L1 can then be used to pay gas, stake with validators, vote in governance, and interact with apps in the ecosystem.

Eseck retweeted

THE BIOTECH GOLD RUSH IS COMING. GENESISL1 BUILDS THE SHOVELS. ⛏️
In every gold rush, the biggest fortunes were made not by those who dug, but by those who supplied the shovels and tools.
The biotech gold rush is starting now. GenesisL1 runs the supply store, the first of its kind: on-chain, public, and open to every lab, every researcher and every AI agent.
━━━━━━━━━━━━
WHY NOW
AI designs proteins, peptides and drugs faster than any lab can check them. Results are cheap; proof is scarce. That is the real demand of this rush: data you can verify, models you can replay, IP you can protect, and a record nobody can rewrite.
━━━━━━━━━━━━
LIVE TODAY
• MolNFT: 1M+ molecular records, with 229,000+ PDB structures held in full in chain state
• GL1F (GenesisL1 Forest): machine learning models as NFTs, with deterministic on-chain inference
• CIPNFT: encrypted IP with post-quantum protection
• gl1x.com/bio: a decentralized bioinformatics laboratory inside the explorer
━━━━━━━━━━━━
BUILT FOR AI AGENTS
Much of the digging in this rush will be done by agents, not by people. GenesisL1 is equipped for them.
• Tooling: 80+ tools served over MCP, 40+ of them pure bioinformatics
• Sequence and structure: BLAST across 1.2M+ protein sequences, HMMER, MSA, structure search and alignment
• Analysis: pockets, ligands, mutation scans, variant effects, proteomics, PubMed
• Full workflow: an agent can search, build a training dataset, run an on-chain model, and prove its input data from chain state at a pinned block
In development: GL1AI, an open inference market with an OpenAI-compatible API and x402 machine payments, so agents can buy compute on their own.
An agent's work here can be checked, not just believed.
━━━━━━━━━━━━
PEPTL (IN DEVELOPMENT)
Peptides are one of the richest veins of this rush. PEPTL is a peptide design and docking studio built on the whole stack: MolNFT for structures, GL1F and GL1AI for models.
1. Targets come straight from chain state as MolNFT objects.
2. Design and docking run as in silico experiments in the studio.
3. Results are published to the same chain, public or sealed with CIPNFT.
Every experiment is preserved, so a design carries its evidence with it.
━━━━━━━━━━━━
GL1-SEQ: GIT FOR GENOMES 🧬
This month The Bioinformatics Company presents GL1-seq, with a preprint. The idea: manage biological sequence the way git manages code.
Today a genome travels as one huge file. Change one base and every pipeline starts from zero. Nobody can prove which version of which sequence produced a result.
How GL1-seq works:
1. Canonical encoding
Every sequence has exactly one valid encoding: about 2 bits per base for DNA, with compact codes for proteins. Reconstruction is lossless and bit-exact.
2. Content-defined chunks
The sequence is cut at anchors chosen by the sequence itself, not by position. Insert one base and only the adjacent chunks are re-cut. Everything else is reused as is.
3. Merkle tree
Chunks are hashed into a tree, and the root is the sequence's identifier. Same sequence, same ID, on any machine, in any language, on-chain or off-chain.
4. Edits as deltas
A new genome is the reference plus a delta. An edit, a slice, a duplication or a translocation rebuilds only the seams, never the whole genome.
5. Certificates
Every edit and every liftover between assemblies carries a certificate sized by the change, not by the genome. Anyone holding only the original identifier can verify it, and so can the chain. Large changes are posted as bonded claims that anyone can challenge, and a dispute comes down to checking a single symbol.
6. Git-style history
Commits, branches, merges and conflict reports. Annotation layers travel with the sequence, so genes are lifted from one version to the next and proteins re-derived with a verifiable receipt.
7. Partial reads with proof
Read any region of any genome with proof that it belongs there, without downloading the genome.
What goes into GenesisL1 chain state:
• The human reference genome (GRCh38), in full
• Every other genome as a delta against it: 10–20 MB per human genome
• 12 pilot genomes at launch, 1000+ public genomes in the months after
• The whole human GENCODE annotation, for gene-by-gene comparison and alignment
• The human proteome and protein atlases: Swiss-Prot, RefSeq, UniRef50, paired antibody repertoires
The result:
• More than 7× faster than full recompute
• Implementations in Python, JavaScript, Go and C++ that produce identical identifiers
• An MCP interface for AI agents from day one
Private data never goes on-chain. It stays in each institution's own compliant environment. The chain holds only cryptographic commitments: a provenance and audit layer.
━━━━━━━━━━━━
THE STORE IS OPEN
Mainnet live since 2021. No founder, team or investor allocation. No token sale. The tools and supplies are public infrastructure, so any lab, any researcher and any agent can walk in and equip itself today.
The rush is starting. The tools are on the shelf. ⛏️
genesisl1.com | gl1x.com/bio
#GenesisL1 #DeSci #Biotech #Biotechnology #Bioinformatics #AIAgent #Peptide #TechBio #AIAgents #OnChainAI #BioFi #Web3 #BiotechGoldRush #AgenticAI #DecentralizedScience #SyntheticBiology #MachineLearning #GL1
🤖 Made with AI

Eseck retweeted

Let me introduce you to something that could become the most important Web3 infrastructure ever built for humanity.
And I'm not talking about DeFi or another perfect engine for launching memecoins.
I'm talking about something MUCH BIGGER.
Decentralized Science.
And here we have GenesisL1.
A permissionless Layer 1 blockchain built as infrastructure for decentralized science and verifiable AI.
No presale. No VCs. No pre-allocation.
This infrastructure has been under development for the past 5 years by someone I personally consider a genius. I'm not sure how this crazy amount of knowledge can fit into a single human being. His name is Mikhail Fedorov, a bioinformatics and Web3 expert, but when you speak with him, he makes you feel like he's an expert in many other fields too, ngl.
Let me explain why this thing could become bigger than any other crypto.
With GenesisL1, we're talking about:
🧬 1. GENOMICS - GitHub for human DNA.
Imagine scientists worldwide being able to access, compare and verify genomic data through shared, decentralized infrastructure.
GenesisL1 is building GL1-Seq, with plans to bring the human reference genome and 1,000+ public genomes into its infrastructure.
Think of GitHub, but for tracking changes, versions and provenance of genetic data.
Why does this matter?
Imagine two laboratories getting different results while studying the same genome.
What if they could trace exactly which version of the reference data each used, verify every change and reproduce each other's work?
Less confusion. More reliable collaboration. Faster progress in understanding genetic diseases.
🔬 2. BIOINFORMATICS - A scientific laboratory accessible to everyone.
GenesisL1 already has GL1X.
Hundreds of thousands of molecular records. Protein analysis. Sequence comparisons. Structural alignments. Binding pockets. Scientific datasets.
Free. No account required.
Accessible to humans AND AI agents.
And the underlying molecular records can be traced back to blockchain-anchored data.
Why does this matter?
Imagine a biology student in a developing country studying a protein involved in cancer.
Instead of building an entire computational pipeline from scratch, they can access molecular structures, compare related proteins, investigate potential binding sites and verify the provenance of the data.
A brilliant scientific idea shouldn't depend on how wealthy your university is.
🤖 3. AI & MACHINE LEARNING - Reproducible intelligence.
Imagine researchers building AI models to predict properties of biological molecules.
GenesisL1's GL1F infrastructure supports machine learning models that can be published as NFTs and used for deterministic on-chain inference.
The vision?
Models that can be shared, reused, verified and potentially monetized.
Why does this matter?
Imagine a laboratory developing an AI model that predicts whether a protein mutation affects its stability.
Another laboratory could use that same published model and independently reproduce its predictions for the same inputs.
Instead of blindly trusting someone else's AI output, researchers could verify the computation.
That's a powerful foundation for scientific collaboration.
💊 4. DRUG DISCOVERY - Helping researchers find what matters.
GenesisL1 is connecting molecular data, bioinformatics tools and machine learning, with additional peptide-design infrastructure under development.
The goal isn't to magically discover cures through blockchain.
It's to make useful scientific tools and verifiable data easier to combine.
Why does this matter?
Imagine scientists investigating a protein associated with a serious disease.
They could analyze its structure, identify potential binding pockets and use computational models to prioritize which hypotheses deserve laboratory testing.
Instead of spending resources investigating every possibility equally, researchers could focus on more promising candidates.
Even improving the efficiency of early-stage research could make a meaningful difference.
🔐 5. SCIENTIFIC OWNERSHIP - Giving discoveries a verifiable history.
Imagine a small research team developing something valuable but struggling to collaborate with larger institutions while maintaining control over its work.
GenesisL1 is developing CIPNFT infrastructure for confidential scientific intellectual property.
The broader vision includes verifiable records, controlled access and new ways to coordinate scientific assets.
Why does this matter?
Imagine an independent research team developing a promising biotechnology method.
They could potentially establish a verifiable record of their work and coordinate access or licensing with collaborators without immediately disclosing everything publicly.
This could provide additional infrastructure for managing scientific collaboration and intellectual property.
🌍 6. AI AGENTS - Scientific research that never sleeps.
This might be one of the most fascinating parts.
GL1X already exposes its bioinformatics tools through APIs and MCP.
Meaning AI agents can interact directly with scientific tools and molecular data.
Why does this matter?
Imagine a researcher investigating a protein associated with Alzheimer's disease.
They could ask an AI agent to find related proteins, compare their structures, investigate potential binding pockets, retrieve relevant literature and prepare a dataset for machine learning.
Instead of manually switching between multiple tools, the agent could coordinate much of the computational workflow.
The scientist would still interpret and validate the results.
But imagine how many more scientific hypotheses researchers could explore when repetitive computational work becomes easier to automate.
And here we are.
Genomic data. Bioinformatics. AI models. Drug discovery tools. Scientific IP. Autonomous AI agents.
Connected through an ecosystem built around GenesisL1.
With genesisl1:native powering the blockchain economy.
I genuinely believe the potential of this infrastructure is beyond our imagination.
Actual infrastructure being built, piece by piece, right in front of our eyes.
Learn GenesisL1.
🤖 Made with AI

Eseck retweeted
Not another blockchain telling stories.
Actual infrastructure being built, piece by piece, right in front of our eyes, with the potential to revolutionize science.
Learn GenesisL1. genesisl1:native

Dear BioAI, MedAI, SynBio and biohacking community,
We are very happy to present the very first on-chain bioinformatics laboratory, as a part of the broad GenesisL1 decentralized science architecture:
gl1x.com/bio — Bioinformatics Onchain
Free. No account. Open to humans, programs and AI agents.
What it is
GenesisL1 carries hundreds of thousands of protein and nucleic acid structures published as MolNFT records, stored in contract state or anchored on chain with CID-verified IPFS content. GL1X treats that archive as a scientific database and runs the standard methods of sequence and structure bioinformatics over it, in its own code, with no external services, and each method validated against its reference program.
This is not a wrapper around someone else's server. It is a laboratory that lives on the chain.
What you can do today
🔎 Search & homology — molecular search by PDB ID, UniProt accession, NFT id, title, sequence or motif; full BLAST (blastp/n/x, tblastn, tblastx) over every sequence, identical to NCBI BLAST+ on the test set; PROSITE-style motif scans across sequences and 3D structures; profile HMM search reproducing the hmmsearch pipeline.
🧬 Structure — TM-align superposition of any chain against any other (or your own file); structure search over every indexed chain in seconds via the GSA structural alphabet; pre-computed experiment-vs-prediction comparisons for every UniProt accession present as both.
🔬 Full-atom analysis in the research workbench — DSSP secondary structure and H-bonds, accessibility, half-sphere exposure, contact maps, base pairs with pseudoknots, chain interfaces with buried surface, salt bridges; SS-pattern search (β-hairpins, helix-turn-helix); 3D templates for catalytic triads and metal sites.
💊 Pockets & druggability — cavities with volume, buriedness, hydropathy, charge and a druggability score, searchable across every structure; a ligand index of every cofactor, drug, ion and sugar with its binding-site residues.
🧪 pH environments — structure-based pKa for every ionizable group; charge, pI and stability of a protein in the stomach, intestine, blood, cytosol, endosome or lysosome, with membrane proteins getting a pH on each side.
⚗️ Proteomics — digestion by 24 enzymes, proteotypic peptides across the archive, masses, fragments, isotope patterns, MGF spectrum identification with target-decoy FDR, crosslink checks, HDX/LiP painting, a virtual 2D gel.
🌳 Families, evolution & variants — multiple alignment at MUSCLE-level accuracy, Jensen-Shannon conservation on the structure, NJ trees, mean-field DCA coevolution vs contacts, CD-HIT clustering, disorder/coiled-coil/TM annotation, substitution scans and ΔΔG from GL1F models.
📊 Datasets & on-chain ML — turn any search into a dataset (JSON/CSV/TSV) with documented features, or straight into GL1F model inputs; train off chain, publish the model as an NFT, run it on GenesisL1 on any record.
📚 Literature — PubMed search with up to 2,000 records clustered into a topic map in your browser (Broccoli), every structure linked to its literature.
✅ Proofs — every sequence in every result can be re-derived from the chain at a pinned block and from IPFS, with the calls to replay on your own node. Every hit names the record and the SHA-256 of what it describes. Deterministic answers, reference parity, held-out evaluation.
🤖 Agent-native — every tool above is an MCP tool and an API endpoint. An agent can identify a molecule, BLAST it, find its structural neighbours, analyse its pockets, digest it, align its family, scan its variants, read its literature, build a dataset, run a model and prove the sequences, end to end.
Where this is going
This is the opening move. The horizon is expanding constantly: the full human reference genome and pilot genomes are coming into chain state through GL1-seq, with 1000+ public genomes to follow, alongside Swiss-Prot, RefSeq proteins, UniRef50, paired antibody repertoires and IPD-IMGT/HLA. Peptide design (PEPTL), confidential IP (CIPNFT), scientific DAOs (COLLAB) and DeSci finance (DESCIFI) are being built around the same core.
Our aim is simple and ambitious: hundreds of thousands of researchers working on decentralized infrastructure, with tools and services for open science expanding at a pace the field has not seen before.
This is an invitation
Research on chain. Build on chain. Point your agents at the MCP server, call the API, fork the explorer, publish a model, mint your structures. Everything you compute here is provable, reproducible and belongs to no single server.
→ gl1x.com/bio · Docs: gl1x.com/docs/bioinformatics · API: gl1x.com/docs/api · MCP: gl1x.com/docs/mcp
Welcome to the laboratory.
GenesisL1

Eseck retweeted
This is how you bring REAL utility and adoption to blockchain. genesisl1:native
#GenesisL1 is building something much bigger than another crypto ecosystem.
🧬 A free bioinformatics lab where scientists, researchers, and AI agents can analyze proteins, explore drug discovery, study mutations, and build AI models.
Why does this matter?
Because people don’t need to care about crypto to use it.
🔹 Researchers get powerful scientific tools for free.
🔹 AI agents can automate complex research.
🔹 Developers can build and monetize AI models and services.
🔹 More users and applications can create real demand for GenesisL1 infrastructure.
Free tools attract users. Useful products keep them. Models and services create economic opportunities.
That’s how an ecosystem can grow beyond speculation.
Real science. Real utility. Real potential for adoption.
And this is just the beginning. 🔥
$L1 🌱
Dear BioAI, MedAI, SynBio and biohacking community,
We are very happy to present the very first on-chain bioinformatics laboratory, as a part of the broad GenesisL1 decentralized science architecture:
gl1x.com/bio — Bioinformatics Onchain
Free. No account. Open to humans, programs and AI agents.
What it is
GenesisL1 carries hundreds of thousands of protein and nucleic acid structures published as MolNFT records, stored in contract state or anchored on chain with CID-verified IPFS content. GL1X treats that archive as a scientific database and runs the standard methods of sequence and structure bioinformatics over it, in its own code, with no external services, and each method validated against its reference program.
This is not a wrapper around someone else's server. It is a laboratory that lives on the chain.
What you can do today
🔎 Search & homology — molecular search by PDB ID, UniProt accession, NFT id, title, sequence or motif; full BLAST (blastp/n/x, tblastn, tblastx) over every sequence, identical to NCBI BLAST+ on the test set; PROSITE-style motif scans across sequences and 3D structures; profile HMM search reproducing the hmmsearch pipeline.
🧬 Structure — TM-align superposition of any chain against any other (or your own file); structure search over every indexed chain in seconds via the GSA structural alphabet; pre-computed experiment-vs-prediction comparisons for every UniProt accession present as both.
🔬 Full-atom analysis in the research workbench — DSSP secondary structure and H-bonds, accessibility, half-sphere exposure, contact maps, base pairs with pseudoknots, chain interfaces with buried surface, salt bridges; SS-pattern search (β-hairpins, helix-turn-helix); 3D templates for catalytic triads and metal sites.
💊 Pockets & druggability — cavities with volume, buriedness, hydropathy, charge and a druggability score, searchable across every structure; a ligand index of every cofactor, drug, ion and sugar with its binding-site residues.
🧪 pH environments — structure-based pKa for every ionizable group; charge, pI and stability of a protein in the stomach, intestine, blood, cytosol, endosome or lysosome, with membrane proteins getting a pH on each side.
⚗️ Proteomics — digestion by 24 enzymes, proteotypic peptides across the archive, masses, fragments, isotope patterns, MGF spectrum identification with target-decoy FDR, crosslink checks, HDX/LiP painting, a virtual 2D gel.
🌳 Families, evolution & variants — multiple alignment at MUSCLE-level accuracy, Jensen-Shannon conservation on the structure, NJ trees, mean-field DCA coevolution vs contacts, CD-HIT clustering, disorder/coiled-coil/TM annotation, substitution scans and ΔΔG from GL1F models.
📊 Datasets & on-chain ML — turn any search into a dataset (JSON/CSV/TSV) with documented features, or straight into GL1F model inputs; train off chain, publish the model as an NFT, run it on GenesisL1 on any record.
📚 Literature — PubMed search with up to 2,000 records clustered into a topic map in your browser (Broccoli), every structure linked to its literature.
✅ Proofs — every sequence in every result can be re-derived from the chain at a pinned block and from IPFS, with the calls to replay on your own node. Every hit names the record and the SHA-256 of what it describes. Deterministic answers, reference parity, held-out evaluation.
🤖 Agent-native — every tool above is an MCP tool and an API endpoint. An agent can identify a molecule, BLAST it, find its structural neighbours, analyse its pockets, digest it, align its family, scan its variants, read its literature, build a dataset, run a model and prove the sequences, end to end.
Where this is going
This is the opening move. The horizon is expanding constantly: the full human reference genome and pilot genomes are coming into chain state through GL1-seq, with 1000+ public genomes to follow, alongside Swiss-Prot, RefSeq proteins, UniRef50, paired antibody repertoires and IPD-IMGT/HLA. Peptide design (PEPTL), confidential IP (CIPNFT), scientific DAOs (COLLAB) and DeSci finance (DESCIFI) are being built around the same core.
Our aim is simple and ambitious: hundreds of thousands of researchers working on decentralized infrastructure, with tools and services for open science expanding at a pace the field has not seen before.
This is an invitation
Research on chain. Build on chain. Point your agents at the MCP server, call the API, fork the explorer, publish a model, mint your structures. Everything you compute here is provable, reproducible and belongs to no single server.
→ gl1x.com/bio · Docs: gl1x.com/docs/bioinformatics · API: gl1x.com/docs/api · MCP: gl1x.com/docs/mcp
Welcome to the laboratory.
GenesisL1
Eseck retweeted
In the past 2 days there have been a few hundreds of new $L1 holders.
There are a lot of people that don't know how to buy wL1 on Base, how to bridge it to GenesisL1 native token and how to stake those tokens.
This video will help you do that in under 5 minutes.
Make sure to share it so other can follow all the steps here.
Eseck retweeted
FirstBlock Validator delivered something nice for the GenesisL1 community. genesisl1:native
Make sure to follow and support them along the way. 🤝

Everyone says whales are accumulating $L1.
Unmask checked the chain:
Whales net bought 58.9% of what they traded in 7 days.
974,893 wL1 bought vs 576,996 sold.
74% of the L1 bought in the last 24h is still held.
Don't trust, verify 🔍 unmaskcrypto.io
#GenesisL1

Eseck retweeted
genesisl1:native is up 50% while the rest of the market is bleeding.
This is not a coincidence.
The biotech narrative is just warming up for the next crypto cycle.
And I have a feeling a few VCs might already be quietly accumulating genesisl1:native.
I've been watching wallets accumulate almost daily for several weeks now. No idea who's behind them, but the pattern is interesting. BUYING EVERY DAY.
GenesisL1 could be the most interesting project to watch in this emerging Web3 biotech narrative.
We are talking AI, Genomics, Drug discovery, Verifiable scientific infrastructure.
Learn GenesisL1.

this might be my last normal tweet before biotech goes vertical
i'm not a whistleblower. I don't work at Lilly, Novo or any of the big labs
but there is a massive shift happening in human biology right now.
it's sitting in press releases and almost nobody reads them
the last 6 months alone:
- a once-daily pill roughly doubled median survival in metastatic pancreatic cancer (13.2 vs 6.6 months)
- a one-time gene editing infusion cut hereditary angioedema attacks 87%, and 62% of patients stayed attack-free and off all other prevention for 6 months
- a one-time gene edit for cholesterol dropped LDL up to 62%, and it held for over a year
- a personalized mrna vaccine beat keytruda alone in a 1,137 patient melanoma phase 3
- retatrutide hit ~28% weight loss in a phase 3
- an ai-designed drug entered phase 3
- a pill that regrows hair passed its second phase 3
- an immunotherapy that could let some rectal cancer patients skip surgery, chemo and radiation just got fda approved
- a man lived 271 days off dialysis on a pig kidney
- human cells were caught passing chromosome-sized chunks of DNA to their neighbors, and it changes how the neighbors behave
we are on the verge of an era where the human body is a software problem and the update cycle gets shorter everyday
stick around, it's going to get weird
bio/acc
Eseck retweeted
GenesisL1 as the number #1 gainer in the last 24h on Base! genesisl1:native
Probably nothing..
Do yourself some good and do a little research here, you’ll thank us later.
You can also stake your $L1 to FirstTensor Validator (link down below).

Top gainers Base coins last 24H
What project are you betting big on?👇
$wL1 @genesis_L1
$MYC @MYC_TOKEN
$POD @dphnAI
$SLC @silencioNetwork
$DGUY @StonksDGUY
$PEPE @0x52BasedPepe
$Fren Pet @frenpetonbase
$aeon @aeonframework
$RWA @RWA_Inc_
$Ratspeak @ratspeakorg

Eseck retweeted
𝗚𝗲𝗻𝗼𝗺𝗲𝘀 𝗮𝗿𝗲 𝘀𝗼𝘂𝗿𝗰𝗲 𝗰𝗼𝗱𝗲. 𝗜𝘁'𝘀 𝘁𝗶𝗺𝗲 𝘄𝗲 𝗺𝗮𝗻𝗮𝗴𝗲𝗱 𝘁𝗵𝗲𝗺 𝗹𝗶𝗸𝗲 𝗶𝘁.
(The git moment for genomics)
This month The Bioinformatics Company unveils 𝗚𝗟𝟭-𝘀𝗲𝗾 — and the preprint behind it. One protocol that treats DNA, RNA and protein sequences the way git treats code: content-addressed, versioned, diffable, auditable.
Two layers. The separation is the point.
𝗟𝗮𝘆𝗲𝗿 𝟭 — 𝗣𝘂𝗯𝗹𝗶𝗰 𝗿𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲, 𝗼𝗻 𝗰𝗵𝗮𝗶𝗻
The 𝗰𝗼𝗺𝗽𝗹𝗲𝘁𝗲 𝗵𝘂𝗺𝗮𝗻 𝗿𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝗴𝗲𝗻𝗼𝗺𝗲 (𝗚𝗥𝗖𝗵𝟯𝟴) — every base, in full, in chain state on GenesisL1. Not a hash. Not a pointer. The sequence itself, in GL1-seq's native ~2-bit encoding, 4× denser than FASTA. One canonical sequence, verifiable by anyone: the main branch the world commits against.
Every other genome is a diff. A full human genome as a diff is 𝟭𝟬–𝟮𝟬 𝗠𝗕 — and thousands of genomes on chain become routine.
At launch: the 𝗰𝗼𝗺𝗽𝗹𝗲𝘁𝗲 𝗵𝘂𝗺𝗮𝗻 𝗿𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝗴𝗲𝗻𝗼𝗺𝗲 (𝗚𝗥𝗖𝗵𝟯𝟴) + 𝟭𝟮 𝗽𝗶𝗹𝗼𝘁 𝗴𝗲𝗻𝗼𝗺𝗲𝘀. Next: 𝟭,𝟬𝟬𝟬+ public genomes, then Swiss-Prot, RefSeq, UniRef50, IMGT/HLA and antibody repertoires.
Not theory. GenesisL1 already holds 𝟭𝗠+ PDB and AlphaFold structures in chain state (MolNFT). Sequences are next.
𝗟𝗮𝘆𝗲𝗿 𝟮 — 𝗣𝗿𝗶𝘃𝗮𝘁𝗲 𝗱𝗮𝘁𝗮, 𝗶𝗻 𝗮 𝗰𝗼𝗺𝗽𝗹𝗶𝗮𝗻𝘁 𝗲𝗻𝘃𝗶𝗿𝗼𝗻𝗺𝗲𝗻𝘁
Patient and participant genomes 𝗻𝗲𝘃𝗲𝗿 𝘁𝗼𝘂𝗰𝗵 𝘁𝗵𝗲 𝗰𝗵𝗮𝗶𝗻. They remain in the institution's private, compliant environment — under its own governance, access controls and jurisdiction. The chain records only cryptographic commitments — a fingerprint, never the sequence. Provenance and change history, verifiable by anyone, with zero data leaving the institution.
𝗪𝗵𝗮𝘁 𝗶𝘁 𝗱𝗲𝗹𝗶𝘃𝗲𝗿𝘀
🔹 𝗟𝗼𝘀𝘀𝗹𝗲𝘀𝘀 𝗯𝘆 𝗰𝗼𝗻𝘀𝘁𝗿𝘂𝗰𝘁𝗶𝗼𝗻 — bit-exact reconstruction from reference + commits. 100% fidelity.
🔹 >𝟰× 𝗳𝗮𝘀𝘁𝗲𝗿, >𝟰× 𝗰𝗵𝗲𝗮𝗽𝗲𝗿 — touch the delta, never the full sequence.
🔹 𝗣𝗿𝗼𝘃𝗲𝗻𝗮𝗻𝗰𝗲 𝗮𝗻𝗱 𝗮𝘂𝗱𝗶𝘁 𝗯𝘂𝗶𝗹𝘁 𝗶𝗻 — who, what, derived from what. Reproducibility becomes a property of the data.
🔹 𝗗𝗲𝘁𝗲𝗿𝗺𝗶𝗻𝗶𝘀𝘁𝗶𝗰 𝗲𝘃𝗲𝗿𝘆𝘄𝗵𝗲𝗿𝗲 — identical results on-chain (EVM) and off-chain, in Python, JavaScript, Go, Rust and C++. No protocol upgrade required.
🔹 𝗡𝗮𝘁𝗶𝘃𝗲 𝘁𝗼 𝗵𝘂𝗺𝗮𝗻𝘀 𝗮𝗻𝗱 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁𝘀 — one format, one interface. Agents branch, analyze and commit with full attribution; humans audit every step.
For biobanks, sequencing cores, national genome projects, pharma and regulators: one canonical reference everyone shares, plus a tamper-evident audit trail for private data — 𝘄𝗶𝘁𝗵𝗼𝘂𝘁 𝗺𝗼𝘃𝗶𝗻𝗴 𝗮 𝘀𝗶𝗻𝗴𝗹𝗲 𝗽𝗮𝘁𝗶𝗲𝗻𝘁 𝗴𝗲𝗻𝗼𝗺𝗲.
Preprint, benchmarks and code this month — follow for the release.
#Genomics #Bioinformatics #DeSci #DataProvenance #AIAgents #GenesisL1
🤖 Made with AI

Eseck retweeted
Hello,
We are very happy to share GL1X.com/bio — a decentralized, on-chain bioinformatics laboratory embedded in the blockchain explorer.
Our aim is hundreds of thousands of researchers on GenesisL1’s decentralized infrastructure.
teapawt.net/genesis_L1/status/2112…
Thank you!
Your AI agents just got an in silico bio lab on chain. It lives on GenesisL1.
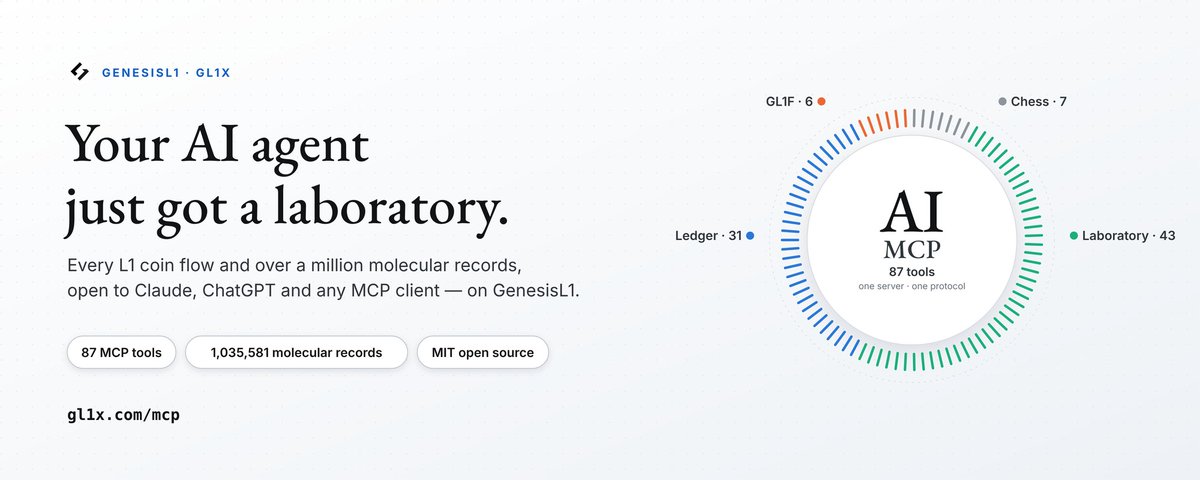
GL1X.com delivers explorer with science: 1M+ molecular records on chain and tools to study them, beside every L1 coin flow. For Claude, ChatGPT, any MCP client.
teapawt.net/genesis_L1/status/2112…


Eseck retweeted
Let me sound crazy again.
Just like I did with $TAO many years ago, back when it wasn’t even listed on a single exchange.
- Genesis genesisl1:native will enter top10 in the next bull run.
- Science and biotech become the BIGGEST narratives, delivering major breakthroughs in drug discovery, cancer research, neurodegenerative diseases and potentially even therapies targeting biological aging.
- The entire human reference genome and thousands of public human genomes live on GenesisL1. Versioned like Git repositories, with verifiable provenance, on-chain random access and smart-contract verification. What sounds crazy today becomes normal scientific infrastructure with Genesis genesisl1:native.
- Thousands of laboratories, universities and biotech companies use GenesisL1. Not to speculate on crypto, but to register genomic datasets, track research versions, verify computational results, protect intellectual property and collaborate across institutions.
- AI agents become actual scientific researchers’ assistants. Imagine Claude or other AI systems accessing millions of molecular records, comparing protein structures, analyzing sequences, building datasets and calling specialized models through Genesis infrastructure. GL1X is already an early glimpse of this.
- Institutions use GenesisL1 without even knowing they’re using crypto. Laboratories pay in stablecoins while the underlying infrastructure converts the required fees into $L1. Real network demand comes from actual scientific activity, not just speculation.
Learn GenesisL1.

Eseck retweeted
The AI world is moving into the right direction and will help hundreds if not billions of people in the coming years directly or indirectly.
That’s why #GenesisL1 is so important into this space! genesisl1:native
this might be my last normal tweet before biotech goes vertical
i'm not a whistleblower. I don't work at Lilly, Novo or any of the big labs
but there is a massive shift happening in human biology right now.
it's sitting in press releases and almost nobody reads them
the last 6 months alone:
- a once-daily pill roughly doubled median survival in metastatic pancreatic cancer (13.2 vs 6.6 months)
- a one-time gene editing infusion cut hereditary angioedema attacks 87%, and 62% of patients stayed attack-free and off all other prevention for 6 months
- a one-time gene edit for cholesterol dropped LDL up to 62%, and it held for over a year
- a personalized mrna vaccine beat keytruda alone in a 1,137 patient melanoma phase 3
- retatrutide hit ~28% weight loss in a phase 3
- an ai-designed drug entered phase 3
- a pill that regrows hair passed its second phase 3
- an immunotherapy that could let some rectal cancer patients skip surgery, chemo and radiation just got fda approved
- a man lived 271 days off dialysis on a pig kidney
- human cells were caught passing chromosome-sized chunks of DNA to their neighbors, and it changes how the neighbors behave
we are on the verge of an era where the human body is a software problem and the update cycle gets shorter everyday
stick around, it's going to get weird
bio/acc

Eseck retweeted
This is HUGE.
And this is exactly why I keep telling people to pay attention to @genesis_L1.
Imagine AI agents having access to over 100 MILLION biological sequences, the entire human reference genome, and tools to search protein structures, compare 3D folds, analyze sequences and much more.
Well… that’s the scale GenesisL1 is aiming for.
Its blockchain explorer, GL1X, already gives AI agents access to over 1 MILLION molecular records and 43 bioinformatics tools.
Also planning to add 100 MILLION+ sequences and the entire human genome on-chain.
Let that sink in. genesisl1:native

“If we can predict the [protein's] shape, we can design a drug that recognizes the harmful form and leaves the healthy one alone.”
A Hopkins-led team backed by up to $52M from @ARPA_H will build an AI model to decode how proteins misfold in Parkinson’s, cancer, and other diseases. bit.ly/4zMyCdb

Eseck retweeted
Feels like a new narrative is starting to take shape.
Science!
AI-driven drug discovery is going to be HUGE.
As AI agents become increasingly involved in scientific research, they'll need more than intelligence.
They'll need access to scientific data, computational tools, reproducible results and verifiable provenance.
This is where @genesis_L1 gets very interesting.
Its GL1X explorer gives AI agents access to over 1 MILLION molecular records anchored on GenesisL1 and 43 bioinformatics tools.
Protein structures. Sequence analysis. Molecular comparisons. Scientific literature.
This could eventually become one of the most powerful narratives in crypto.
Drug discovery. Biotechnology. Longevity. Open science.
Think about the amount of value that could be created in these industries.
Learn GenesisL1. genesisl1:native
Don't be lazy.


Eseck retweeted
This blockchain explorer is absolutely MIND-BLOWING. 🤯
Seriously. Take a look at the GL1X explorer. genesisl1:native
This is not your typical blockchain explorer where you check transactions, wallets and validators.
This is a blockchain explorer combined with a working BIOINFORMATICS LAB.
Let that sink in.
Over 1 MILLION molecular records living on-chain.
Protein structures. Molecular data. AI models. Scientific research.
And here’s where things get CRAZY.
Connect Claude or ChatGPT through MCP and your AI agent gets access to 87 tools, including 43 for bioinformatics.
Your agent can explore molecular structures, compare proteins, analyze peptides, search scientific literature and build datasets for AI models.
All through a blockchain explorer.
No API key. No sign-up.
And the entire thing is OPEN SOURCE.
WTF???
Now think about something.
If this is what a BLOCKCHAIN EXPLORER looks like on GenesisL1…
Can you even imagine what the entire infrastructure could become?
And that’s exactly what I’ve been trying to explain for months.
GenesisL1 is not just another blockchain trying to find a use case.
It’s an infrastructure being built around science, AI, verifiable data, computation, intellectual property and machine payments.
This explorer alone gives you an ideea of how much bigger this vision is than the typical crypto narrative.
I believe most people have absolutely no idea what they’re looking at when they first discover GenesisL1.

Eseck retweeted
We are upgrading the genesisl1:native onchain #Biotech insilico laboratory a few versions every week with amazing new features and improvements gl1x.com/molnft. Today, GenesisL1 stores >1M molecular records. A year from now: >100M sequences & the entire Human Genome onchain. #DeSci

Eseck retweeted
Imagine giving an AI agent access to an entire blockchain AND a scientific laboratory.
Now look at GL1X built on genesisl1:native
1M+ molecular records. Bioinformatics. On-chain AI. 87 tools for AI agents.
#GenesisL1 isn't just putting AI on-chain. It's making the chain usable by AI.