

18 / software engineering student / ai workflows / open to work
Joined November 2021
- Tweets2.3K
- Following183
- Followers354
- Likes7.9K


Pinned Tweet
It's Probably the Smartest Way to Stop Wasting $200/Month on AI Agents in 2026...
In this article, I'll show you how to build your own autonomous AI agent swarm using open-source tools:
no bullshit. Elon Musk said it best: "anyone not running a swarm of agents by the end of 2026 will look like someone who refused to use email in 1998"
this is what that looks like in real life, in one screen recording:
one prompt. a swarm of claude and codex agents self-organizing inside tmux. the leader splits the tasks, spawns workers in isolated git worktrees, passes messages through a CLI inbox, and merges the entire build while you just watch
meanwhile 90% of people reading this are still babysitting AI the same fucking way they used chatgpt in 2023. one terminal tab. one prompt at a time. manually copying context between windows like an unpaid intern
zero docker, zero redis, zero YAML hell. it runs purely on tmux and git worktrees with one pip install, and even comes with 1-command templates for autonomous ML research and 7-agent hedge fund teams. whoever switches to swarms this month will outship entire engineering teams by january. the ones who do not will still be slow-typing into a single chat window like it is 2023
grab the open-source repo here (5.6k+ stars): github.com/HKUDS/ClawTeam
if you are building an agent swarm stack, also check out these repos that pair with it:
→ github.com/ruvnet/ruflo (78k+ stars, multi-agent orchestration across claude, grok, and codex)
→ github.com/superagent-ai/gro… (terminal coding agent with live X search and telegram remote control)
→ github.com/novix-science/aut… (autonomous ML experiment loop that ClawTeam runs across GPUs)
bookmark this before monday morning hits and you waste another week doing manual copy-paste
the gap between people running single chats and people running autonomous swarms is about to become the only gap that matters. do not land on the wrong side of it
how many agents are you running at once right now, or are you still stuck in one chat window?

It's Probably the Smartest Way to Stop Wasting $200/Month on AI Agents in 2026...
In this article, I'll show you how to build your own autonomous AI agent swarm using open-source tools:
11
27
856
no bullshit. i found an open-source Grok Bot alternative that lets you run an entire team of AI agents from one interface - using the coding agents and subscriptions you already have.
most people are still juggling separate Claude Code, Codex, and Grok sessions, switching between terminals, browser tabs, and different AI tools just to get one project done.
OpenMausBot takes a completely different approach.
it's an open-source, local-first AI agent workspace inspired by Grok Bot. instead of one assistant trapped in one chat window, you get an entire roster of bots, each with its own personality, memory, model, computer, and connected apps.
how it works under the hood:
→ runs Claude Code, Codex, and Grok through their local CLI installations
→ lets you create multiple independent AI bots, each with its own model, personality, and conversation memory
→ gives every bot access to its own cloud Linux desktop, isolated local VM, or supported host computer
→ connects 500+ apps through Composio, including GitHub, Gmail, Slack, Notion, and Linear
→ uses a local harness server to manage agent processes, stream events, and coordinate tool execution
→ asks for your approval before executing sensitive shell commands or editing files
→ supports phone access through a paired mobile browser or app, so you can interact with your agents away from your computer
→ includes voice features, spoken responses, and conversational calls on supported platforms
→ exposes an MCP server so external AI clients can inspect and control your bot workspace
the interesting part is the architecture.
you're not locked into another proprietary AI subscription or a single model provider.
github repo:
github.com/milind-soni/OpenM…
you bring your own agents, your own logins, and your own models.
each bot becomes a separate worker with its own context, computer, tools, and conversation history.
one install command:
npm install -g openmausbot
then:
openmausbot
no need to rebuild your entire AI workflow around another bloated IDE.
one workspace
→ multiple AI agents
→ Claude + Codex + Grok CLI
→ individual bot memory
→ virtual computers
→ 500+ connected apps
→ MCP integration
→ optional phone access
this is what an open-source Grok Bot alternative actually looks like: a personal AI workforce running on infrastructure you control.
where do you draw the line between AI automation and human control?
fayz333 retweeted
It's Probably the Smartest Way to Stop Wasting $200/Month on AI Agents in 2026...
In this article, I'll show you how to build your own autonomous AI agent swarm using open-source tools:
no bullshit. i replaced my $200/month coding subscriptions with an open-source terminal agent that i can literally control from my phone via telegram voice notes
elon musk keeps saying the real edge for AI agents is live access to real-time data instead of static training cutoffs
most coding agents are still trapped inside bloated IDEs, disconnected from live X/web data, and dead the second you walk away from your keyboard. this open-source CLI fixes all of it in one install command
how it works under the hood:
→ runs natively in your terminal on xAI's grok API (grok-4.3 and multi-agent models)
→ searches live X posts and the web mid-build so it never hallucinates outdated docs
→ spins up parallel sub-agents by default to explore, code, and control your desktop UI
→ pairs with telegram so you can DM voice notes from your phone and watch it ship code on your machine
→ runs --verify in an isolated sandbox to boot your app, test it in a browser, and save video proof
→ schedules recurring background tasks via daemon mode using batch API pricing
honestly the telegram voice bridge is what makes it feel unfair. you send a 10-second voice memo while walking outside, grok transcribes it, edits the repo, runs tests, and replies with proof
1 install command
→ live X + web search
→ parallel sub-agents
→ telegram remote control
→ verified builds
the devs winning in 2026 are not babysitting chat windows inside slow editors. they are running headless, terminal-native agents from anywhere
i dropped the full open-source github repo (3.5k+ stars) and 1-line install below ↓ free, steal it
bookmark this before monday morning hits and you get stuck babysitting another slow IDE agent
what are you coding with right now: claude code, cursor, or terminal CLI agents?

Grok Bot could be the first team you build instead of hire
Six bots can run 200+ agents, hold their own 5 a.m. standup and hand you one board in the morning
In this article, I show you how
16
38
1,260
batshit crazy. i stopped paying $200/month in AI subscriptions, ran one terminal command, and turned grok bot into an uncapped multi-provider agent that runs even with $0 in API keys
elon musk keeps repeating the same thing on X:"the future is running swarms of agents in parallel, not babysitting one prompt at a time"
the problem is you cannot run parallel agents when hosted backends throttle you every 10 minutes. mine routes straight through a local proxy on localhost:8788 with automatic failover
how it works under the hood:
→ you run one command: npm run setup
→ it patches grok bot's host bundle and spins up 3 silent daemons on localhost
→ every chat, tab-complete, and agent call gets intercepted as binary connect-rpc
→ the proxy translates it into standard openai streams on the fly
→ routes to openrouter, opencode free tiers, local models, or kilo (200 req/hr with zero API keys)
→ if one provider stalls or hits a limit, the circuit breaker fails over to the next one in milliseconds
honestly the background host watcher is what makes it unfair. every time grok bot updates itself, the daemon auto-repatches the bundle so your setup never breaks
1 command → 0 hosted fees → 5 fallback providers → 0 rate-limit crashes → runs forever across updates
builders shipping fast in 2026 own their inference layer instead of renting throttled wrappers
i left the full open-source github repo and 1-command setup below ↓ free, steal it
bookmark this before monday morning hits and a rate limit kills your build again
what are you routing your agents through right now: openrouter, local models, or still paying monthly subscriptions?


A free GitHub tool now lets an AI open an app nobody gave you the source code for and explain how it works, line by line. People are already pointing it at Grok Bot itself: 540 files rebuilt into readable code.
YOU DON'T HAVE TO UNDERSTAND CODE TO SEE WHY THIS MATTERS. EVERY APP USED TO BE A LOCKED BOX. THE LOCK JUST GOT A LOT THINNER
The video shows this repo's page on GitHub, scrolled down through the README. The swarm of cursors is a visual effect I added on top.
Here is the simple version.
Every app has a recipe: its source code. Companies keep it private. All you ever get is the finished cake.
A tool called REA, short for Reverse Engineer Anything, lets an AI agent taste the cake and write the recipe back. You ask Claude Code or Codex, the agent calls REA, and REA digs into the app and reports what it found, with the file and line where each finding came from.
It's free and MIT licensed. Setup is one command, and it shows you a plan and asks before it changes anything. The repo has passed 100,000 stars.
Now the part that made me stop.
REA's authors say it works with agents like Claude Code, Codex, Cursor and Gemini CLI. And people didn't wait long to test it on the most talked-about agent app around.
One project describes itself like this:
"reconstructs the installed Grok Bot 0.66.0 desktop application"
It says all 540 JavaScript files of the app now have a readable TypeScript version, and it names REA as the tool it used. Another repo is an analysis archive of Grok Bot's inner workings, with 484 route declarations and 167 public methods mapped, and it says it checked its findings with REA.
Read that as a normal person: someone took a finished, closed app and got an AI to draw a map of how it's built.
Here is the link to the tool: github.com/morluto/rea
And the two Grok Bot examples: github.com/olllayor/grokbot-… github.com/oceanz0312/grok-b…
How does it avoid making things up? It makes the agent label every finding as seen, inferred or unknown. That matters, because agents love to state a guess as if it were a fact.
My take: the gap that's about to matter is between people who treat apps as black boxes and people who hand the box to an AI and read the blueprint. The first group takes the company's word for how things work. The second checks.
What I haven't verified: I haven't run REA. The Grok Bot numbers (540 files, 484 routes, 167 methods) come from those repos' own READMEs, and both are unofficial projects.
Careful: REA is not a sandbox, and a lookalike repo with a similar name exists. Install only from the link above or as rea-agents on npm.
Only take apart software you own or are allowed to study.
The video is a screen recording with a cursor effect. The "agents / layers" counter belongs to the effect.
So is an app you can't see inside something you should trust, or something you should check?


14
23
723
Elon Musk after seeing XERJ’s own test: a model with no per-token bill that’s 320–500× cheaper than RAG on Claude Opus 5.5.
🤝 Paid partnership

I've built a new AI model that is not allowed to generate text. Instead, it produces a verifiable program that answers your prompt using the original reference.
XERJ Reader-1 is a neurosymbolic model for working with data. It points to the exact words in your document, writes a small program over them, and exact code computes the answer:
• 20-90x faster
• 10-1,000x cheaper (output tokens free)
• every answer is a program you can replay
The shortest path to automating data work.
4
18
516
Grok Bot costs up to $300 a month. One free GitHub list already tracks 63 skills, plugins, MCP servers and self-hosted alternatives around it, and the free rival it's compared with has 391k stars.
THE PEOPLE RENTING A GENIUS EMPLOYEE AND THE PEOPLE OWNING THE WHOLE STACK ARE ABOUT TO BE IN TWO DIFFERENT WORLDS. THIS ONE REPO IS THE MAP
The video shows this repo's page on GitHub, scrolled down through its README. The swarm of cursors is a visual effect I added on top.
The repo is awesome-grok-bot, an unofficial, community-maintained directory. Its header calls it:
"A curated, verified directory of 63 Grok Bot skills, plugins, MCP servers and self-hosted alternatives."
Here is what's inside.
13 skills. Reusable setups and workflow packs. The names alone tell you where this is going: botteams, grokbot-for-gtm, overnight, even a werewolf-gamemaster.
Plugins and MCP servers. 10 community ones, plus 22 from the official marketplace.
16 self-hosted alternatives, runtimes and bridges. This is the part that should make you stop. Tools that run outside the vendor's cloud, or connect a Bot to other places, like Discord or your terminal.
2 guides. For people who need an on-ramp.
Then the list does something most lists don't. It puts the price next to the alternatives.
Grok Bot is a closed product. It's not sold standalone and has no free tier. The list puts the plans at $120 to $300 a month. OpenClaw, listed as the free, open-source, self-hosted option where you bring your own model, sits at 391k stars. Hermes Agent, also free and model-agnostic, is at 251k.
So the market splits into two camps: pay monthly for the polished version, or own a free stack you can swap parts of.
The "Pick of the Week" shows which way the wind blows. It's HyperGrok, described as:
"the first entry here that treats a Bot as staff rather than as a tool."
Seven specialist roles, wired into a group chat. It starts in research mode with no wallet attached.
Here is the link: github.com/ZeroPointRepo/awe…
And a few of the self-hosted ones from inside it: github.com/ishandutta2007/op… github.com/wolfqing/OpenGrok… github.com/davefmurray/grok-… github.com/ScriptedAlchemy/g…
My take: the gap that's about to matter isn't between people who use AI and people who don't. It's between people who rent one agent and people who own the stack around it. The first group pays monthly. The second group swaps parts.
What I haven't verified: I haven't run any of this, and I couldn't read the repo reliably from here. One cached view of the page showed an older version of the list with only 19 entries and almost no stars, while the README I read showed 63, so counts may differ from what you see. For that reason I didn't lead with stars. The ecosystem is brand new and the repos move fast.
The prices and the OpenClaw and Hermes star counts come from the list itself, from a snapshot dated October 4, and they change. The list also says usage limits aren't published.
The list calls itself "a curated list, not an audit," and warns that some entries ask for real credentials. Read before you paste any key. The four extra links are completed from owner and project names in the list, so check that each one opens. Running agents can cost money for model usage. The video is a screen recording with a cursor effect. The label at the bottom ("agents", "layers") belongs to the effect, not to this repo.
So is the future of agents a monthly subscription, or a free stack you assemble yourself?


Stop asking AI about binaries one chat at a time. Someone built a full reverse engineering lab for your agents: 100+ MCP tools, 180+ guides, Ghidra, Frida, x64dbg and Rizin all wired in, in one free repo.
THE GAP ISN'T BETWEEN PEOPLE WHO USE AI AND PEOPLE WHO DON'T. IT'S BETWEEN PEOPLE WHO CHAT WITH IT AND PEOPLE WHO GIVE IT A LAB
The video shows this repo's page on GitHub, scrolled from the top down through the README. The swarm of cursors is a visual effect I added on top.
The project is called Open ReverseLab. Here is how its own description reads:
"Open-source AI reverse-engineering agent platform and MCP server for Ghidra, Frida, x64dbg and Rizin — automated PE/APK/binary analysis, CTF and malware research, with 100+ MCP tools and a 194-article runnable knowledge base."
Read that again. It isn't a prompt. It isn't a tip. It's a workplace you hand to Claude Code or Codex.
Here is what that workplace looks like.
Four boards, one for each kind of job. Web and CTF challenges. Android apps. Windows executables. And a general board for crypto, protocols and firmware.
Tools the agent can call itself. Names in the repo include triage_pe, ghidra_headless_analyze, sample_full_workup, android_frida_* and http_probe, plus a router that picks the right guide for the problem. The agent isn't guessing which tool exists. They're registered.
A reading order for the agent. Before it touches anything, the repo tells the agent what to read first: CLAUDE.md, then AGENTS.md, then AI-USAGE.md, then the guide for that board. The lab briefs the agent before it starts.
A quarantine step for artifacts. Samples go through a workflow instead of landing anywhere. That's what makes this a lab and not a pile of scripts.
A page on running agents unattended. The docs even cover setting agents up for 24-hour CTF runs.
Getting in is short. On Windows you run START_HERE.bat. On macOS and Linux you run ./START_HERE.sh. It checks for Python, uv and Git. It's built for Claude Code, Codex and other MCP-compatible agents. License: GPL-3.0.
Here is the link: github.com/LING71671/open-re…
Think about what that does to the old way of learning this. Reverse engineering used to mean a stack of tools, a pile of tabs and years of habits in your head. Here the habits live in the repo, and the agent reads them.
My take: the person who asks an AI about a binary and the person who hands an AI a lab will not end up in the same place. The first gets an answer. The second gets a workflow that repeats. Don't land on the wrong side of that.
What I haven't verified: I haven't run Open ReverseLab, and I couldn't open its GitHub page from here. The description above comes from the repo's listing, and third-party pages disagree on the details: article counts range from 180+ to 197, and star counts range from roughly 500 to 1,400 depending on the tracker, which is why I didn't lead with stars.
This is a young repo, so check the README for what it really includes today. "100+ tools" is the repo's own claim. The repo is free, but the model usage behind Claude Code or Codex can cost money. Only analyze software you own or are allowed to test.
The label at the bottom of the video ("agents", "layers") belongs to the cursor effect, not to this repo. The video is a screen recording with that effect added.
So are you going to keep chatting with your AI, or give it a lab?


Someone put a whole game studio inside Claude Code: 49 AI agents, 72 skills, 37k stars, and the repo picked up 4.3k of them in just 7 days.
ONE PERSON, ONE CLAUDE CODE SESSION, AND A FULL STUDIO ORG CHART OF AI AGENTS. THE ONLY QUESTION LEFT IS WHO MAKES THE DECISIONS
The video shows this repo's page on GitHub, scrolled from the file list down through the README. The swarm of cursors is a visual effect I added on top.
The project is called Claude Code Game Studios. Its own description says:
"Turn Claude Code into a full game dev studio — 49 AI agents, 72 workflow skills, and a complete coordination system mirroring real studio hierarchy."
It's MIT licensed, so you can use it, change it and build on it.
Here is what's inside.
The team. The 49 agents are organized the way a real studio is: directors on top, department leads under them, specialists at the bottom. Roles in the repo include a creative director, a technical director, a producer, an art director, a QA lead and a release manager. There are also agent sets for the engines people actually use: Godot 4, Unity and Unreal Engine 5.
The skills. 72 workflow skills work as commands you type inside Claude Code. Examples: /start for guided setup, /brainstorm, /dev-story, /code-review and /release-checklist.
The guardrails. The repo ships path-scoped coding standards for gameplay, engine, AI, UI, network and asset files, plus scripts that check commits, pushes and asset changes. The agents work inside rules, not just on vibes.
The workflow. It runs from brainstorm all the way to launch: design, stories, implementation, QA, release. Templates for game design documents, architecture decision records and sprint plans come with it.
And here is the part that matters. The repo says you, the developer, keep making every decision. The agents ask questions, offer options and catch mistakes. You approve.
Setup is short: clone the repo, open Claude Code in the project folder, and run /start.
The numbers: about 37k stars and 4.9k forks. The repo was created on February 12, 2026, so that's roughly nine months. About 4.3k of those stars came in the last 7 days.
Here is the link: github.com/Donchitos/Claude-…
Think about the size of the idea. A studio isn't one skill. It's a pipeline of roles that argue with each other, and this repo tries to copy the arguing, not just the typing.
My take: the interesting part isn't that AI can write game code. It's that the repo copies how a studio makes decisions. If it works, the scarce skill won't be programming. It will be knowing which of 49 suggestions to approve.
What I haven't verified: I haven't run this repo or opened its page myself. The counts of 49 agents and 72 skills are the repo's own claims, and the summaries I found disagree on the exact breakdown, so treat them as claims until you've counted. The star, fork and growth numbers come from a tracker page dated November 9 and change by the hour. The repo is free, but Claude Code usage itself can cost money. The label at the bottom of the video ("agents", "layers") belongs to the cursor effect, not to this repo. The video is a screen recording with that effect added, not a demo of the agents running.
So can one person plus 49 agents ship a real game, or just a very well-organized pile of prototypes?
22
48
1,345
this is the quietest industry shift of the decade. nobody is tweeting about it yet because the top 1% of engineers are still hoarding the alpha. but the people who learn to run 50 to 500 claude agents in parallel this quarter are about to walk into 2027 doing in a weekend what entire mid-sized companies still bill $500k for. elon musk keeps dropping the same line in every interview this year: the real moat in 2027 is not who has the smartest AI, it is who can run 500 of them at the same time without losing track
one open-source github repo just quietly turned that idea into a product. 113k stars. 18.7k forks. 7,220 commits. and it is running agents like an actual company
the project is called paperclip. MIT licensed. their own github tagline: "the open-source app everyone uses to manage agents at work"
the problem is not that AI agents are weak anymore. the problem is that you have 20 claude code tabs open and cannot remember what any of them are doing. paperclip turns that chaos into an org chart. CEO agent on top. managers under it. workers under them. budgets. goals. accountability. one board you can actually look at and make decisions from
the quickstart takes 5 minutes. create a company. hire a CEO agent. approve its first strategy. watch tasks land on the board. then go to sleep while the company you just built operates itself
113k stars is not a trend. it is the first signal of a shift in what engineers are paid for. the skill that used to pay you was doing the task. the skill that is about to pay 10x is designing the structure that does the task for you
the people still running one chat, one tab, one question at a time will be the exact same people who, in 2017, refused to learn git because "i can just send zips"
repo link: github.com/paperclipai/paper…
i wrote the full breakdown of how paperclip works under the hood, how to set up your first 10-agent company tonight, the exact hiring order that works, and the 3 mistakes that burn your whole setup in week one. the article is below
bookmark this before your competitors do
10
24
596
This is f*cking wild. Anthropic's CEO says AI could disrupt half of all entry-level white-collar jobs within 1 to 5 years, and the first jobs he names are junior law, junior finance and junior consulting.
THE FIRST JOBS AI TAKES ARE THE ONES PEOPLE START A CAREER WITH. THE WAY OUT IS A HARNESS, AND 14 REPOS TO BUILD IT ARE FREE
Dario Amodei was asked what a kid finishing high school should do right now. He didn't soften it:
"AI will also eliminate jobs, and probably a large number of them."
His list of first jobs in the line of fire is short: entry-level law, entry-level finance, entry-level consulting. That's the work most people use to get their first foot in the door.
And he says this shift is different. Farms, factories, the internet: each one gave people time to catch up. This one cuts deeper and moves faster.
His advice sounds simple: learn to use AI. But using it is now the minimum.
Look at the ladder most people are climbing:
Chatting → Prompting → Agents → Harness → Loops → You run the AI
Most people are stuck on the first two steps. The ones who get ahead build a harness, a setup that runs the AI for them. You stop being the person doing the task and become the person managing the thing that does it.
Here are 14 free repos that cover the whole climb.
Ready-made Claude plugins for legal, finance, sales, HR and data: github.com/anthropics/knowle…
Analyst-grade agents for models, memos and research notes: github.com/anthropics/financ…
Skills for working with Excel, Word, PowerPoint and PDF: github.com/anthropics/skills
An agent that does financial research on its own: github.com/virattt/dexter
An agent that researches any topic in depth: github.com/assafelovic/gpt-r…
Ask your spreadsheets and databases questions in plain English: github.com/sinaptik-ai/panda…
Agents that work as a team, each with its own role: github.com/crewAIInc/crewAI
A harness with everything built in: github.com/langchain-ai/deep…
Anthropic's SDK for building your own agents: github.com/anthropics/claude…
A memory layer so your agents remember context: github.com/mem0ai/mem0
A loop that keeps the agent working until the job is done: github.com/snarktank/ralph
An agent that clicks through websites and fills in forms for you: github.com/browser-use/brows…
Drag-and-drop workflows to automate busywork: github.com/n8n-io/n8n
18 free lessons on building agents: github.com/microsoft/ai-agen…
My take: AI won't take your seat. Someone who learned to run it will. The new entry-level skill isn't doing the task, it's building the thing that does the task.
What I haven't verified: I haven't opened these repos, so check each one before you rely on it. The 1 to 5 year, half-of-entry-level-jobs estimate is a forecast Amodei made publicly, not a certainty, and the quote above comes from the clip as it was shared, not from a transcript I checked. The repos are free to use, but running them can still cost money for model usage. The video is an illustration, not a recording.
So will AI take the junior seat, or will the juniors who build a harness take the manager's?

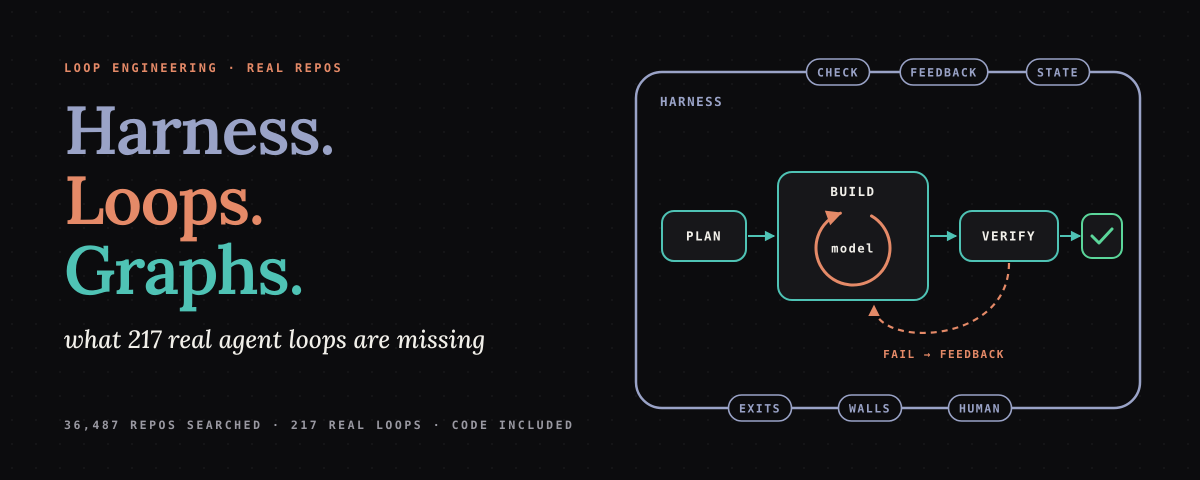
This is getting dangerous: one free GitHub repo now holds 93 runnable AI engineering projects, and it just picked up about 2,700 stars in 7 days.
THE EXCUSE FOR NOT LEARNING AI ENGINEERING JUST DISAPPEARED. 93 RUNNABLE PROJECTS ARE SITTING IN ONE FREE REPO
The repo is called AI Engineering Hub. The description says: "In-depth tutorials on LLMs, RAGs and real-world AI agent applications."
It's MIT licensed, so you can use it, change it and build on it for free.
Here is what's inside. The projects are split into three levels:
→ 22 beginner projects → 48 intermediate projects → 23 advanced projects
That's 93 in total, and it comes with a roadmap that tells you what to build in what order.
The topics are the ones every AI engineer is expected to know: RAG, AI agents, MCP, voice agents, OCR, fine-tuning, evaluation and observability, and running models fully on your own machine.
Some of the projects you'll find: Agentic RAG, a Multi-Agent Deep Researcher, an MCP Voice Agent, GitHub RAG, and an Evaluation and Observability project built with Opik.
The stack is the one people actually use at work: LlamaIndex, Ollama, CrewAI, Milvus, Qdrant and Groq, among others.
The repo was created on October 21, 2024. It's now at roughly 41,000 stars, and about 2,700 of them came in the last 7 days. Its best single day was around 1,100 stars, on November 1.
Here is the link: github.com/patchy631/ai-engi…
Think about what that changes. A few years ago, learning this meant paying for a course, or piecing it together from scattered blog posts that were already out of date.
Now the whole path is in one place, with working code, free.
My take: the bottleneck is no longer finding good tutorials. It's finishing projects. When 93 runnable examples are free, the only thing that proves you can do the work is what you actually ship.
A word of caution: star counts differ between tracking sites, anywhere from about 38,000 to 41,000 depending on the tracker and the day. I couldn't open the repo itself from here, so the project counts and the stack list come from write-ups of it, and the repo changes often. Check the README before you plan around any single number. The video is an illustration, not a recording.
So does finishing 93 projects make you an AI engineer, or just someone who's very good at following tutorials?

Damn, I still can't believe it: 20 free GitHub repos now add up to a full reverse engineering studio that an AI agent can run for you.
A FULL REVERSE ENGINEERING STUDIO NOW COSTS ZERO. THE REAL SKILL IS KNOWING WHEN THE AGENT IS WRONG
A few years ago this took a lab, a license budget and months of practice. Now it's twenty repos and one agent.
The tools fall into five groups. Here is every one of them.
[01] Analysis core: where the agent plugs in
REA is a single MCP server that connects the agent to everything else. github.com/morluto/rea
Ghidra is a free decompiler. github.com/NationalSecurityA…
GhidraMCP lets your agent drive Ghidra. github.com/LaurieWired/Ghidr…
ida-pro-mcp does the same for IDA Pro. github.com/mrexodia/ida-pro-…
[02] Mobile and apps
jadx turns an Android APK back into Java. github.com/skylot/jadx
Apktool takes an APK apart and puts it back together. github.com/iBotPeaches/Apkto…
Frida hooks into an app while it runs. github.com/frida/frida
ILSpy decompiles .NET. github.com/icsharpcode/ILSpy
[03] Binaries and low level
radare2 is a reverse engineering framework that lives in your terminal. github.com/radareorg/radare2
x64dbg is a debugger for Windows. github.com/x64dbg/x64dbg
ImHex is a hex editor with its own pattern language. github.com/WerWolv/ImHex
angr is a symbolic execution engine. github.com/angr/angr
[04] Network and execution
mitmproxy sits in the middle and reads the traffic. github.com/mitmproxy/mitmpro…
dnSpy debugs and edits .NET apps. github.com/dnSpyEx/dnSpy
rizin is a fork of radare2. github.com/rizinorg/rizin
raddebugger is the debugger from Epic Games. github.com/EpicGamesExt/radd…
[05] Rebuild and verify
awesome-ai-reverse-engineering is a list of 122 repos, each one rated. github.com/zhuyansen/awesome…
awesome-reverse-engineering is a hand-picked list from the creator of REA. github.com/morluto/awesome-r…
REA flows are ready-made investigation prompts that ship with REA.
The clean-room loop means you write a SPEC.md, then run oracles and checks until the rebuild matches.
The whole pipeline fits on one line:
binary -> REA -> SPEC.md -> rebuild -> oracle -> retry
"Save this, point it at any app and watch it explain itself."
Here is why that last loop matters. The agent can open a binary, describe what it does and write a rebuild. But "it looks the same" proves nothing. The oracle is what counts: run the original and the copy on identical inputs and compare the outputs. A rebuild can compile, run and look right while behaving differently in the one case nobody tested.
My take: the tools are free now. The thing you can't skip is a check that doesn't depend on the model's word.
Before you start: keep a backup, record how the original behaves, change one thing at a time, and mark each claim as seen, inferred or unknown. Only take apart software you own or have the right to study.
What I haven't verified: I haven't run this stack. Some GitHub paths were cut off in the list I worked from, so I completed those from the project names, and I couldn't open the pages from here to confirm them. Check each link before you rely on it. The REA connection, the 122-repo rating and the ready-made prompts are described the way the list describes them.
So when an agent says the rebuild matches, do you trust the agent, or do you trust the check?
REA is most dangerous thing on the internet right now...
It lets your AI agent reverse engineer any app, down to the binary
If you use it correctly, you can rebuild any feature you pay for, for FREE
In this article, I show you how:
10
45
1,612
Damn, I still can't believe it: 13 free GitHub repos turn a plain folder of notes into a second brain that an AI agent can actually use.
A FOLDER OF NOTES IS NOT A SECOND BRAIN UNTIL AN AGENT CAN SEARCH IT AND REMEMBER IT
Most people save everything and use almost none of it. The notes pile up, and the agent starts from zero every single chat.
These 13 repos fix that, in five steps. Almost all of them run on your own computer.
Step 1: capture what you read
obsidian-clipper saves any web page as Markdown. It's the official web clipper from Obsidian. github.com/obsidianmd/obsidi…
markitdown turns PDF, Word, PowerPoint, Excel and audio files into Markdown. github.com/microsoft/markitd…
yt-dlp pulls subtitles out of a video without downloading the video itself. github.com/yt-dlp/yt-dlp
paperless-ngx gives you OCR and full-text search across all your scans and PDFs. github.com/paperless-ngx/pap…
Step 2: give it structure
obsidian-dataview turns your vault into a database you can query. github.com/blacksmithgu/obsi…
obsidian-git keeps a version history and automatic backups of every note. github.com/Vinzent03/obsidia…
Step 3: make it searchable
qmd is local search over your notes. It combines keywords, vectors and re-ranking, and it comes with an MCP server, so an agent can plug straight in. github.com/tobi/qmd
meilisearch searches as you type, forgives typos, and has a hybrid semantic mode. github.com/meilisearch/meili…
Step 4: give the agent a memory
letta builds stateful agents that learn over time. github.com/letta-ai/letta
langmem stores facts, behavior and past interactions as long-term agent memory. github.com/langchain-ai/lang…
MemOS is a memory layer for agents, saved as a graph you can browse and edit. github.com/MemTensor/MemOS
Step 5: make it yours
quartz publishes your Markdown notes as a website. github.com/jackyzha0/quartz
syncthing syncs your vault across devices, peer to peer and encrypted. github.com/syncthing/syncthi…
Look at the shape of it. First you capture. Then you structure. Then you search. Then the agent remembers. The order is the whole point.
"A pile of notes only becomes a second brain when an agent can search it and remember it."
My take: the winners won't be the people who save the most. They'll be the people whose agent can find the right note in two seconds and never starts from scratch.
What I haven't verified: I haven't installed or tested these 13 repos. The descriptions above come from the repos' own summaries, and I haven't independently confirmed how well each tool works, how they fit together, or that every one runs fully offline. Start with one or two steps, not all 13 at once.
So where does it break first for you: getting notes in, or getting the right note back out?
REA is most dangerous thing on the internet right now...
It lets your AI agent reverse engineer any app, down to the binary
If you use it correctly, you can rebuild any feature you pay for, for FREE
In this article, I show you how:
11
27
719
Damn, I still can't believe it: you drop one PDF into a Grok Bot group chat, and a bot rewrites 10 to 15 of your wiki pages on its own, while a third bot exists only to doubt them.
YOUR AI SECOND BRAIN WILL LIE TO YOU. THE FIX IS A BOT WHOSE ONLY JOB IS DOUBT
Everyone is building a memory for their AI. Almost nobody is building the part that checks it.
That's the real risk. A memory that grows by itself also gets things wrong by itself, and it does it in a confident voice.
"A second brain can sound sure while remembering the wrong thing."
Here is how the setup works on Grok Bot: three bots in one group chat, each with its own memory. That's exactly what the video shows, step by step.
Reader collects. It takes every link, PDF and voice note you drop and never edits any of it. In the video, source-042.pdf gets locked as read-only, with 0 mutations.
Librarian writes. It rewrites every wiki page the new source touches, usually 10 to 15 pages. In the video you can watch the pages get patched one by one, 12 of 12.
Checker doubts. It wakes up on a nightly routine and hunts contradictions, stale claims and pages that nothing links to.
Then the part that matters. In the video, a new source arrives and disagrees with an old page. The checker doesn't fix it quietly. It tags you and leaves the old page untouched.
Three rules make it trustworthy:
→ A new source contradicts an old page: the checker tags you instead of quietly overwriting it. → A page goes 30 days without a fresh source: it gets marked unconfirmed. → You ask a question: the answer is filed back as a page, so the brain grows from use, not only from reading.
And every page has to show three things:
the claim the source it came from the date it was last confirmed
If a page can't show those, it isn't knowledge. It's a guess.
Paste this into Grok Bot to start:
"Build me a second brain with three bots in one group chat. Keep my sources untouched in raw/, maintain wiki/ yourself, file good answers back as pages and run a nightly check for contradictions. Show me the structure first. Do not create anything until I confirm"
The last sentence matters most. Make it show you the structure before it builds anything.
Start with one topic you actually work on, not your whole life. A small brain you trust beats a big brain you don't.
The value of a second brain is not how much it remembers. It's how loudly it admits what it can't confirm.
A note on the video: it's an illustration of the idea, not a recording of a real Grok Bot run, and the numbers in it are simulated. The 10 to 15 pages per source, the nightly check and the 30-day rule come from the description of the pattern, and I haven't tested how the prompt behaves with long sources.
So which fails first in a self-writing wiki: the writing, or the trust in what it wrote?


Damn, I still can't believe it: 7 free GitHub repos take you from a raw binary to an AI agent that reverse engineers it for you.
A FREE REVERSE ENGINEERING DEGREE IS SITTING ON GITHUB, AND THE ORDER IS THE WHOLE TRICK
Most people open one of these tools, get lost in the assembly, and quit.
The trick is the sequence. Each repo builds on the one before it. Seven steps, zero tuition.
Layer 1: learn to read a binary
Ghidra, the NSA's reverse engineering framework. This is where everyone starts. github.com/NationalSecurityA…
radare2, the same skill but in the terminal. A UNIX-style toolset for the command line. github.com/radareorg/radare2
Layer 2: let a model do the reading
LLM4Decompile, an LLM that turns binary code back into readable C. The 9B v2 model is reported at 64.9% re-executability on its own benchmark. github.com/albertan017/LLM4D…
r2ai, an LLM inside radare2. This is the moment the AI starts reading the binary next to you. github.com/radareorg/r2ai
Layer 3: let the agent drive the tool
ida-pro-mcp, which connects IDA Pro to language models through MCP. github.com/mrexodia/ida-pro-…
reverse-engineering-assistant, the same idea for Ghidra, as an MCP server. github.com/cyberkaida/revers…
Layer 4: agents that go after anything
REA, which covers 35 target types: native binaries, APKs, firmware, websites, Electron apps. The pitch is "every finding backed by evidence." github.com/morluto/rea
Look at the shape of it. Humans learn the tool. Then a model reads the code. Then an agent operates the tool by itself. Then one agent goes after dozens of target types.
My take: reverse engineering is turning from a rare craft into something you can delegate. The skill that matters now is knowing which evidence to trust.
Only I can say this: [Describe your own first time opening a binary or an APK, and what you actually found. Replace with your own story if it isn't true.]
What I haven't verified: I haven't run any of these repos. The star totals, the 35-target-type count and the 64.9% figure come from the repos' own descriptions and haven't been independently confirmed. Benchmark numbers on the creators' own tests don't predict results on your binary. Only analyze software you own or are authorized to test.
So where does this go: do these agents make reverse engineers 10x faster, or do they just make it easier for everyone to trust wrong output faster?
REA is most dangerous thing on the internet right now...
It lets your AI agent reverse engineer any app, down to the binary
If you use it correctly, you can rebuild any feature you pay for, for FREE
In this article, I show you how:
14
42
1,332
Damn, I still can't believe it: one AI agent plus 20 free GitHub repos can now take apart an app you own, explain how it works, and build it again. Here's the whole stack.
THIS IS GETTING DANGEROUS: AN AGENT WITH 20 FREE REPOS DOES THE WORK OF A REVERSE ENGINEERING LAB. THE HARD PART ISN'T OPENING THE APP. IT'S PROVING THE COPY BEHAVES LIKE THE ORIGINAL.
The video shows the setup running: twenty tools around one terminal. Here's every repo, in five groups.
[01] The core: where the agent plugs in
REA: one MCP that connects the agent to everything below. github.com/morluto/reaGhidra: a free decompiler. github.com/NationalSecurityA…: gives your agent the controls for Ghidra. github.com/LaurieWired/Ghidr…: the same idea for IDA Pro. github.com/mrexodia/ida-pro-…
[02] Phones and desktop apps
jadx: turns an Android APK back into Java. github.com/skylot/jadxApktoo…: takes an APK apart and puts it back together. github.com/iBotPeaches/Apkto…: hooks into an app while it's running. github.com/frida/fridaILSpy: decompiles .NET. github.com/icsharpcode/ILSpy
[03] Binaries and the low level
radare2: a reverse engineering framework in your terminal. github.com/radareorg/radare2…: a debugger for Windows. github.com/x64dbg/x64dbgImHe…: a hex editor with its own pattern language. github.com/WerWolv/ImHexangr: a symbolic execution engine. github.com/angr/angr
[04] Traffic and runtime
mitmproxy: sits in the middle and reads the traffic. github.com/mitmproxy/mitmpro…: debug and edit .NET apps. github.com/dnSpyEx/dnSpyrizi…: the fork of radare2. github.com/rizinorg/rizinrad…: the debugger from Epic Games. github.com/EpicGamesExt/radd…
[05] Rebuild and check
awesome-ai-reverse-engineering: a list of 122 repos, each one graded. github.com/zhuyansen/awesome…: a curated list from the same person behind REA. github.com/morluto/awesome-r… workflows: ready-made investigation prompts that come with REA. clean-room loop: write a SPEC.md, then run oracles and checks until the rebuild matches.
The whole flow in one line:
binary -> REA -> SPEC.md -> rebuild -> oracle -> retry
Count the steps. Four of them are the agent working. The last two are what you can trust. The agent opens the binary, writes what it does into SPEC.md, builds a new version from that spec. Then the oracle decides: run the original and the rebuild on the same inputs and compare the outputs. Without that, "it matches" is just the agent's opinion, and a rebuild can compile, run and look identical while behaving differently in a spot nobody tested.
My take: the 20 repos are the cheap part. The check outside the model is what makes a rebuild worth keeping.
Before you open anything: back it up, record what the original does three times, change one thing, measure, keep or revert. Mark every claim as seen, inferred or unknown. And only take apart what you own or have the right to study.
Only I can say this: the first program I'd point this at is one I depend on and have never understood. (Replace with your own story if it isn't true.)
What I haven't verified: I haven't run this stack. Some GitHub paths were cut off in the list I worked from, so I completed them from the project names, and I couldn't open the pages from here to confirm. Check every link before you rely on it. The REA bridge, the graded list and the ready-made prompts are described as the list presents them.
When an agent says the rebuild matches, do you trust the agent, or do you trust the check?

