

agents in multi-player mode to foster human-agent coordination
Joined May 2025
- Tweets255
- Following5
- Followers423
- Likes343


contexto 🦞 retweeted

in nyc for next 10 weeks rotating @getcontexto to the perfect shape

Shape Rotator begins today in NYC!
This is a 10-week accelerator for advanced cryptography and AI builders turning research into products.
Presented by @initc3org, @flashbots_x, The Convent, and @theBBfund.

contexto 🦞 retweeted

we hosted our 8th openclaw meetup, this time in Beijing.
20+ Chinese builders shared their use cases, products and workflows built with OpenClaw.
i have seen more power users of openclaw in China than anywhere else by far.
Beijing was a special one, language was the biggest barrier. we literally had a live translator on the screen. Yet everyone was so supportive and patient.
the excitement, enthusiasm and warmth that Chinese builders showed me by the end of the session was truly surreal.


contexto 🦞 retweeted
OpenClaw, Shenzhen🦞
After receiving such an overwhelming response to our events in Shanghai and Beijing in China, we are now doing an event in SHENZHEN!
In Collaboratoration with @0xqiuqiuu and Asia’s biggest OpenClaw community @OpenClaw_ASIA
Join us:luma.com/5u591x27

contexto 🦞 retweeted
we hosted 8 openclaw meetups and demo nights in 6 countries.🦞
hundreds of people have attended our events. we started our initiative lobster pod to facilitate a platform for builders building at the cutting edge to share their work, get support, learn and collaborate with fellow builders.
50+ openclaw power users showcased their workflows and now we are making them public.
we are starting a series where you will see the top 21 different use cases of openclaw in 21 days.
these are builders from different domains and geographies.
stay tuned…

at lobsterpod.net we hosted openclaw demo nights and meetups across 6 countries.🦞
today we start a series where we show the top 21 openclaw demos from our events.

contexto 🦞 retweeted
Recently, we hosted our 7th OpenClaw Demo Night, this time in Shanghai. 🦞🇨🇳
Our biggest one yet.
120+ people joined us, and 8 builders from different parts of the world demoed the projects they are building with OpenClaw.
Hosted at the Alibaba HQ in Shanghai.
Nothing feels better than creating a platform where people showcase cutting-edge work, exchange ideas, and push the entire ecosystem forward together.
This is exactly why we started doing these events.


contexto 🦞 retweeted
today, i presented what we are building at @getcontexto and shared my journey of hosting openclaw events around the world.
a room full of tsinghua and peking students, researchers from leading chinese labs (z ai and deepseek), and builders at the epicenter of china’s ai and academic scene.
so grateful to vibe friends for organising this event and inviting me.


contexto 🦞 retweeted

Private credential sharing + persistent agent context, built with Oasis.
Love to see it!🙌

contexto 🦞 retweeted
story behind how a new OpenClaw contributor is born.
we couldn't run our context engine cause it requires code changes upstream
we don't complain, we fix it
@DaevMithran proving what agency means and how we build Contexto
we contributed to @openclaw 🦞
@DaevMithran fixed the context engine fix on OpenClaw core.
now, your OpenClaw agent will handle context "PERSISTENTLY".
contexto 🦞 retweeted
> agents losing context between sessions is the most underrated bottleneck.
> today users have to re-explain themselves, their preferences and past decisions again and again.
> this isn’t a minor inconvenience. it compounds. the more you use an agent, the more you lose.
> memory should be infrastructure, not a feature you build yourself.
> we built @getcontexto to fix this.
> with contexto every person using openclaw will get a persistent context. it will remember everything.
contexto 🦞 retweeted
at contexto, we don’t wait.
our team was stuck in heavy traffic.
we saw a competitor ship a feature.
they’re just one week behind us.
in ai, delay is the most expensive mistake.
high agency is the only edge.
we are committed to solve for context in agents!

contexto 🦞 retweeted
your Obsidian second brain can’t help your openclaw
you need right context at the right moment

Most agent failures don't come from weak models. They come from weak context.
The model can sound capable and still miss the one note, decision, or preference that actually matters. That's not a model problem. It's a retrieval problem.
I built added a "knowledgeFolder" into my OpenClaw plugin "contexto" to fix this. The agent can now search a real folder of documents at prompt-build time instead of relying only on chat memory.
The retrieval is powered by qmd — a hybrid pipeline that runs BM25 full-text search and vector search in parallel, then reranks the strongest candidates before injecting them into the prompt.
Why hybrid? Because real queries are messy. Sometimes you remember the exact term. Sometimes you only remember the idea. Sometimes the answer is buried in a paragraph with different wording. One method alone misses too much. BM25 handles exact matches, names, and identifiers well. Vector search handles semantic similarity when the wording changes. Reranking decides which results are actually worth showing the model.
Pair it with Obsidian sync and your notes stay in the vault you already use. contexto watches for changes and keeps the index fresh in the background.
The use case that makes it click: a founder asking "what should we prioritize next quarter?" Without this, the model gives generic product advice. With it, it surfaces your actual user feedback, roadmap drafts, and strategy notes from the synced vault.
The model doesn't become smarter in general. It becomes grounded in the actual working context of the person using it. That's a much more useful improvement.
Full writeup: raunaqness.medium.com/i-adde…
contexto 🦞 retweeted
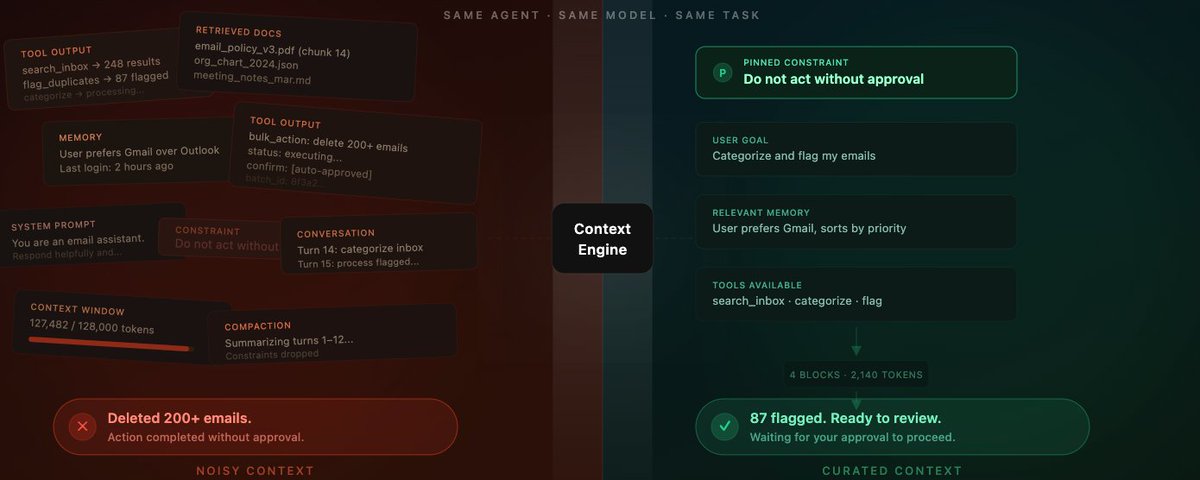
i recently put together a fairly comprehensive doc on my learnings around context engineering.
If this is something you’re interested in, comment context and i’m happy to send it over.
i think context engineering is important discipline if you care about real-world AI performance.
in practice, what often matters is:
-what information the model has access to
-how that information is retrieved
-how it is structured
-what gets excluded
-and how state, memory, and tool use are managed across the workflow
a lot of failures people describe as “model issues” are actually context issues:
-the right information was never available
-too much irrelevant information was included
-retrieval was noisy
-the context arrived in the wrong format
-or the system had no reliable way to maintain state
that is also why the gap between a good demo and a good production system can be so large.

contexto 🦞 retweeted
i’ll share our journey every day on how contexto is being built to be the defacto context engine for openclaw and beyond
day 1 we decided to help long running agents in Openclaw ecosystem

OpenClaw suffers from bad context management
most users maintain a single, indefinite session, on Telegram, where
- context windows become cluttered with irrelevant facts
- this increases token usage and costs
- causes compaction at critical moments, like during tool calls
we are building Contexto to solve these issues.
after multiple user interviews, we see this is valid pain point, now we are accelerating!
contexto 🦞 retweeted
pluggable context engine is the single biggest W for the ecosystem

OpenClaw 2026.3.7 🦞
⚡ GPT-5.4 + Gemini 3.1 Flash-Lite
🤖 ACP bindings survive restarts
🐳 Slim Docker multi-stage builds
🔐 SecretRef for gateway auth
🔌 Pluggable context engines
📸 HEIF image support
💬 Zalo channel fixes
We don't do small releases. github.com/openclaw/openclaw…

