

making compilers grin, building distributed systems, previous @ihc__official, research @iiit_hyderabad
Brooklyn, NY
Joined July 2021
- Tweets9.4K
- Following828
- Followers717
- Likes124K


tushar retweeted

Thanks for the shoutout🫣 If you’re not following The Consensus, it’s the trending independent publication for software internals, check it out!

Worth a read: @keleesssss writes about bug finding considered harmful?
Also: @Dropbox acquired @TigrisData. And @openrouter is hiring a Software Engineer on the Platform team remotely in the US.
theconsensus.dev/g/2026/11/0…

tushar retweeted

X now loads posts and profiles 8-13x faster on slow connections, thanks to streaming server-rendered HTML and zero JS before the first post.
The fastest JS is the JS nobody waits for. Congrats @yagiznizipli and team!

The web rewrite is working.
On a slow connection, the old X web took more than 22 seconds to show the first post on a profile. The new X web does it in 2.7 seconds. Here's how we did it, and how we're rolling it out one country at a time.
blog.x.com/en/engineering/re…

tushar retweeted

Video for my @rust_nyc talk, "Code Matters: Reflections on Rust in the LLM Age", is now up:
youtube.com/watch?v=5D7QPOIZ…


tushar retweeted
It's absolutely crazy that Europe feels 10 years behind in AI even though AI itself is only 3 years old.


tushar retweeted
We seriously should not keep saying this. Pretty soon some "formally verified" software is going to have bugs, and people are going to start questioning what value formal verification really has.

tushar retweeted

It cannot be overstated how much your quality of life decreases when it gets dark at 5pm instead of 7pm
tushar retweeted

When it comes to hiring, it’s easier to tame a reckless hustler than it is to instill that dawg in someone


tushar retweeted
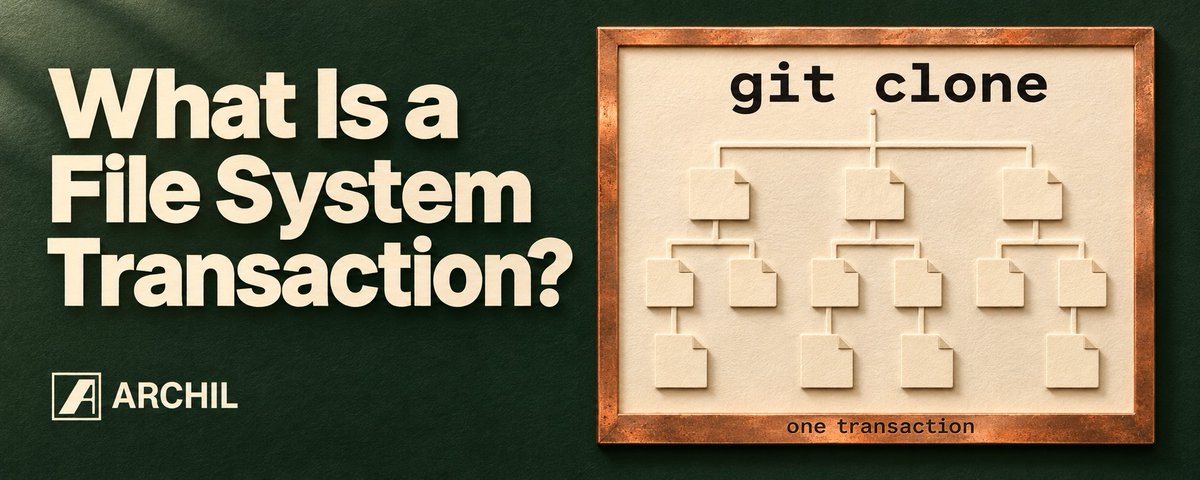
Is caching cope?
Both yes and no.
But I do believe that the answer to (distributed) caching should be 'demand a better database' much more often than it is.
Let's break it down a bit.

tushar retweeted

formal verification all the rage now but you're probably sleeping on deterministic simulation testing
there is too much software and too many failure modes that can't be very nicely modeled with formal methods
so you want deterministic simulation testing which is basically fuzzing on steroids
chai built a custom linux hypervisor and made it deterministic so it could performantly do snapshots and time travel rollbacks for deterministic simulation testing
and it could do crazy things like reduce bugs to their most minimal reproduction etc
so basically 1 dude in a cave with a box of scraps rebuilt antithesis and made it a 10x better product to use

Today I'm announcing Workers IO to solve the slowest part of engineering, verification!
AI agents can now write years’ worth of code in days, but it still takes significant engineering effort to verify what’s being built.
It’s impossible to predict all scenarios that could lead to a failure and that’s why most expensive failures are found in production.
Workers IO runs millions of simulated production scenarios on your entire system, including dependencies. These simulations run inside a deterministic hypervisor which injects faults like network delays, disk errors, clock skew, and process failures to verify how your system handles these conditions.
Deterministic execution allows us to systematically explore the state space of the system and perfectly reproduce failures.
We are already helping customers do years worth of production hardening in days and build confidence in what they’re shipping.
If you are working on systems that you can never afford to break, DM me and we can help you battle test them!



tushar retweeted

with current token prices i wouldn't really say "cost of software is going to zero"
our token cost is double our payroll which means even though we're 25 it's like we're 75
and i feel like our output is similar to a team of 75 pre-ai. we're just able to do it without all the downsides of a larger team
this is still a good thing. we couldn't hire 50 more people. so much overhead and impossible to retain a high bar
tushar retweeted

Picking a good inference provider is difficult.
Picking the best inference provider for an open model is surprisingly hard: The reason: no single provider does it all. On OpenRouter, GLM 5.3’s GPQA score ranges from 78% to 89% (quite a large gap, despite the caveats†), and the trends in GPQA is not strongly correlated with other tasks, so it varies by workload.
Why discuss this now?
Recently, Jon Barron and colleagues showed that standard softmax implementations hide two silent bugs: Softmax Collapse, where the target gradient rounds to zero, and Softmax Cancellation, where identical logits still produce a gradient. Widely speaking, inference has the same problem, except it's harder to get something agreed to be a 'correct' outcome.
In my experience, providers on alternative chips tend to have worse silent framework bugs, though these issues are apparent on NVIDIA inference frameworks as well.
MoE models are especially fragile: the router bias and router output need fp32, etc. (there's a long list of half-patched issues). As deployment engines grow more complex, these bugs get almost exponentially harder to catch.
(Note†: SGLang or vLLM in their default configurations should give the best accuracy. The issue come from what providers add, like some custom quantization, speculative decoding, and custom kernels, or even simply forgetting to update to the latest versions of the frameworks that improve accuracy. And consider the case where you have no open reference at all (i.e they take care of both post-training and inference, so you don't own your own canon copy of the model, where you wouldn't know if there's some error in the stack silently reducing your quality).

tushar retweeted

India needs a ministry of compute.
Like ministry of oil, we need laser-focus from the top to build compute necessary for participating in the future economy.
Otherwise, we will repeat in a decade what we’re doing now: spending expensive forex for importing what we don’t have.


