

cofounder @markovrobotics
San Francisco, CA
Joined September 2019
- Tweets198
- Following666
- Followers1.8K
- Likes17.4K





Greg Tarr retweeted

.@markovrobotics is teaching robots to tackle complex manipulation tasks with fewer than ten hours of robot data. Their bet: video already contains most of the physical reality a robot needs to act.
They use Modal for video processing, world model training, and remote inference.
Greg Tarr retweeted

World models are very precise on out-of-distribution tasks!
Here’s an example of non-compliant arms running at low Hz, picking up a fake $100 bill. The policy was never trained on this or any remotely similar objects
Zero-shot generalization is the only way to physical AGI
Play a video game and get a job. Winners get to work with real robots!

We made this game to hire cracked teleoperators (upto $100k and equity)
Play here: telebench.vercel.app/
Here is our friend Charis's run:
ltx ftw

LTX-2.5 is changing how we train robots. Years of hand-built training data, replaced by a world model that already understands physical space. Trained on LTX. @ltx_io

Greg Tarr retweeted

0-shot pick and place on unseen objects with less than an hour of teleoperation data
Excited to start sharing what we've been working on @markovrobotics
Toward general dexterity
We are training robot policies that learn a rich and coherent physical representation of the world by conditioning on multimodal observations
Here’s a small glimpse of what we’ve been building:
Task: Pick the ramen cup and place it in the box
Given the current world state, the model generates a multimodal trajectory; here we show the decoded video and the corresponding actions executed on the humanoid


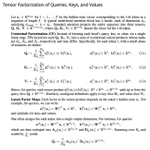
As promised here's a TPA implementation in PyTorch w/ KV cache: github.com/Greg-Tarr/tpa-pyt…
Didn't reference the authors' code so it might deviate a bit. Next step is to add a kernel to compute attn scores without materializing a ⊗ b in memory

TPA (arxiv.org/pdf/2501.06425) is another banger paper. It has better (10x) KV cache compression than MLA ~and~ it's RoPE compatible. Haven't read the repo yet as I want to do a blind implementation tomorrow but I hear the authors are working on a kernel that computes attn scores without materializing QKV (directly from their factorized forms).

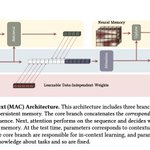
Titans (arxiv/2501.00663) is an all-round great paper. It reads almost like a blog post: probes prior research, asks pertinent questions, and naturally leads to a few elegant architectures that perform really well!
I'd have missed it if not for gh/lucidrains as I haven't seen anyone mentioning it here.

.@CompanyAI
<witty hook>
<generate/transform/turn> your <data> into <more/less/other data> in <short time>.
Just launched on <YC / Product Hunt > and raised $<WTF>m!
Built in <days> with <@OpenAI/@StableDiffusion> for now.
Join the waitlist now!
<link>
<product.gif>