

Founder & CEO @DecomputeAI , Ex - Investment Partner @Microsoft & @Samsung, SWE AI Leader @Apple, AI @stanford
Cupertino, CA
Joined June 2009
- Tweets1.3K
- Following773
- Followers2.8K
- Likes2.2K



Pinned Tweet
BlackBird, you beauty! Comparison side to side: BlackBird vs Perplexity, where BlackBird is completely local and uses much smaller model.
Still in Beta but you can request access here:
lnkd.in/gXBTtWnX
Follow @DecomputeAI for more updates.


By mid-2027, I expect consolidation among undifferentiated inference providers with unhedged compute costs, even as token demand grows. I’d underwrite revenue and compute cost per paid GPU-hour together, not token growth in isolation.

Zooming out, GPUs are still renting ahead of a standard 6-year depreciation schedule
Rental price vs. schedule:
- H200: +143%
- B200: +111%
- RTX PRO 6000: +73%
- H100: +54%
- A100: +9%
Most of the gap opened up after April, when token demand took off
Charts of the Week: a16z.news/p/charts-of-the-we…


I recall being told by a VC, while pitching Decompute, that compute is not a problem anymore, and it has been already solved. 😅

NVIDIA can sell compute into robotics before humanoids deliver attractive labor economics. I’d separate that opportunity from the much harder business of making a robot pay for itself on a customer’s floor.

We’re excited to announce the official release of NVIDIA Isaac Lab 3.0. 🎉
Isaac Lab 3.0 brings a new modular and lightweight architecture along with major new capabilities across the robot learning workflow: multi-physics and multi-rendering support, training at scale, and streamlined deployment on real hardware.
With Newton integration, the new OVRTX renderer, RL post-training, and LEAPP deployment, there’s a lot to explore.
Here’s a look at what’s new 🧵
(1/7)
I’d value a robotaxi operation on productive vehicle-hours, not the autonomy stack alone. A self-driving car that spends most time being maintained earns nothing while idle. Imagine a fleet operator that improves utilization across driving systems could capture meaningful value.

🚗 Hertz $HTZ is heating up! Short interest reportedly hits 72% as borrowing fees surge from the mid-teens to triple digits. Shares have jumped 23% in five days, fueling speculation of a potential short squeeze.
📈 Trading between $1.78–$2.18, Hertz faces a critical catalyst ahead: its Nov. 5 earnings report. An $80M investment in Oro Mobility adds another key factor as short sellers face rising borrowing costs. Will bulls squeeze higher? ⚡

Hina Dixit retweeted
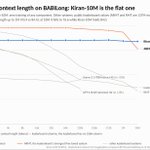
Introducing Kiran-10M: 84.0% average accuracy on BABILong qa1–qa5 at 10M tokens — and 85.6% at 0k. Same frozen 4B-class open-weights LLM, same memory, every length in between inside 84.0–86.4. Ours is the flat one. 1/7

If inference is 10% of a robot’s operating cost, making it 30% cheaper saves 3% overall. I’d put research dollars into reducing interventions when human support dominates the bill. The operating cost breakdown should shape the model roadmap. 1/2
Interpretability belongs in the infrastructure budget. This paper uses causal analysis to identify which connections drive robot actions, cutting MolmoBot’s inference compute ~33% with similar simulated performance. 2/2
Paper: arxiv.org/abs/2610.20750

Margaret was an icon and inspiration! 💔

We’ve lost an icon. Margaret Hamilton, a computer science pioneer best known for her work at MIT leading development of the flight software for the Apollo missions to the moon, has died at 90. Read about her legacy via MIT News: news.mit.edu/2026/margaret-h…

ALT Margaret Hamilton is reclined inside a NASA spacecraft module, surrounded by control panels and switches.
AI memory that doesn't decay, doesn't hallucinate its sources, and runs on hardware you already own. Introducing Kiran-10M that can convert any model architecture to beat RAG and baselines on longest context possible with just $30 compute cost! No need to burn tokens anymore. 👀

Introducing Kiran-10M: 84.0% average accuracy on BABILong qa1–qa5 at 10M tokens — and 85.6% at 0k. Same frozen 4B-class open-weights LLM, same memory, every length in between inside 84.0–86.4. Ours is the flat one. 1/7
Not claiming today: the exact base checkpoint, speed/memory/hardware figures, anything about the mechanism beyond the diagram. Patented; technical report to follow. 6/7
Thank you for covering BF1, Chad! Appreciate it! 🫡
kimbodo.com/how-recent-ai-re…
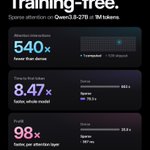
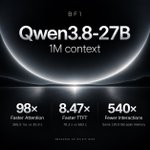
Thank you for reviewing BF1, James! Checkout our results for Qwen3.8-27B at 1M context as well.
james.trappett.org/blog/bf1-…
