
Yuichi Tateno / id:secondlife (セコン) / @hotchpotch - A software engineer in Japan, currently into information retrieval. I don’t check X DMs. Please email me.
Joined October 2007
- Tweets17K
- Following456
- Followers4.8K
- Likes11.2K




search-tech.connpass.com/eve…
10/29(金) の Search Engineering Tech Talk 2026 Autumn で、超小型マルチリンガルな密ベクトル検索モデル、bekko-embedding (not static) についてお話しする予定です! まだ空き枠あるようなので、興味がある方は是非〜〜 #searchtechjp

I released bekko-static-embedding-v1 🚀, a multilingual static embedding model with state-of-the-art retrieval among static embeddings.
No Transformer layers, no GPU: just token lookup + mean pooling. 40 languages, fast on CPU.
huggingface.co/blog/hotchpot…

Jev のような Decision モデル saihai (采配) と、日本語 Decision モデルのベンチマークを作成しました。日本語に強い LLM-jp-4.1-8B を基盤にしているので、日本語タスクでの活躍が期待されます🚀 GGUF も公開しているので、llama.cpp などでの利用もしやすいです!
secon.dev/entry/2026/10/15/1…

また試験的に、小型 Decision モデルの saihai-v1-310m も作ってみました。ruri-v3-reranker-310m をさらにFTしています。このモデルでも用途やタスクによっては十分に使えそうです。
huggingface.co/hotchpotch/sa…

I built an ultra-small System One decision model. Here’s the 17M version running on an RTX 5090 GPU:
🚀 ~2.5M input tokens/sec
⚡ ~4,200 decisions/sec
✅ Yes/No, Choice, and Score tasks
Measured during inference on a single GPU.
You can try reproducing this on an RTX 5090 with the same script:
🛠️ Script:
github.com/hotchpotch/bekko-…
📝 How the models work:
huggingface.co/blog/hotchpot…
🤗 17M model:
huggingface.co/hotchpotch/be…

I wanted a way to evaluate my own System One Decision Model, so I built S1MB (System One Mosaic Benchmark), with 100+ evaluation tasks 📊
Jev’s generalization really stood out when I ran the comparisons.
huggingface.co/spaces/hotchp…

I built an ultra-small System One Decision Model inspired by Jev that runs right in your browser (size: 29MB) 🚀
Generalization still has a long way to go, but it works reasonably well on familiar tasks. Feel free to give it a try!
huggingface.co/spaces/hotchp…

I’ve also published a technical write-up on how I built this model, along with the training code and dataset. Take a look if you’re interested!
huggingface.co/blog/hotchpot…

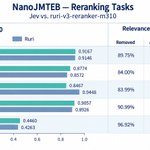
I benchmarked jev-reranker on five NanoJMTEB tasks against ruri-v3-reranker-m310, a strong Japanese reranker.
Jev trails clearly on JaCWIR but edges ahead on the other four tasks in nDCG@10. At a 0.2 threshold, it also filters out 84-97% of retrieved documents!
🤖 Made with AI

Built jev-reranker, a Python library for RAG document scoring, sorting, and threshold filtering with Jev.
On NanoHotpotQA
- 92.38% fewer candidates (100 → 7.62 docs/query)
- nDCG@10: 0.975
Performance comparison and filtering example.

Wrote a quick walkthrough covering the API, relevance filtering, and evaluation results
- huggingface.co/blog/hotchpot…
GitHub / installation
- github.com/hotchpotch/jev-re…

I’ve always found it difficult to clearly explain how multi-vector models (ColBERT-style late interaction) work, but this animation makes it so easy to understand! Sentence Transformers v6.0 also makes ColBERT models much easier to use. Thank you!

mLateOn sets a new SoTA for multilingual ColBERT-style retrieval, leading all 11 evaluated late-interaction models. With only 115M active parameters, it delivers retrieval quality in the same tier as leading 4B and 8B dense embedding models! huggingface.co/blog/hotchpot…

@antoine_chaffin I ran mLateOn through HAKARI-Bench and was really impressed. It competes with 4B and 8B dense models, with especially strong results for short queries and long documents. I also really appreciate the open training data, code, and weights. Thank you!
超小型な多言語テキスト検索モデルの bekko-embedding を公開しました🚀 アクティブパラメータが8M, 25M と小型ながらサイズ数倍〜十数倍規模のモデル並みの検索性能です。とりわけ CPU でベクトル作って検索したいぞ〜のようなユースケースにぴったりだと思います!
secon.dev/entry/2026/07/29/0…

またbekkoの野良論文も公開しています。ruri(2026年のruri 論文、めちゃくちゃ参考になりました @hpp_ricecake さん、毎度ありがとうございます!) やその他、先行研究の論文をなぞっだけなのでは…という感じですが、興味ある方はご覧ください。日本語PDF版はこちらに👇
storage.googleapis.com/secon…
ブラウザー上でも直接モデルをロードして、ベクトル検索を試せます!(ファイルサイズはまぁまぁあるので、回線によっては初回ダウンロードに時間がかかりますが・・・)
huggingface.co/spaces/hotchp…
