
I do competitive shit in uncompetitive places. CSQ - Chartered Street Quant
Joined June 2021
- Tweets608
- Following438
- Followers4.4K
- Likes347




Pinned Tweet
Starting a new series of threads on designing an MFT strategy, almost everything will be shared publicly.
As usual, the goal is to not fuck up too much.
I will explain the issue I currently have and hope I can get some feedback on whether or not I'm doing the right thing.
- I have HFT strategies making decent $ on uncompetitive exchanges.
- It's great for now, but it may not last: I'm exposed to strong counterparty risk and the capacity is low.
I have some cash to park in a strategy, and I think the best ROI I can get is from custom-made active strategies.
I need a strategy that can handle a capacity of 100k–500k, which leaves a lot of room for trading small-capacity alphas.
I already did a few tests, and I can get decent MM-style execution on Tier 1/2 DEXs.
I now want to design a system that will output weights that my MM will target, slowly trading towards my desired exposures.
The current plan is to create factor-style features (both time-series and cross-sectional) targeting 1h forward returns, blend them in a smart or street quant way, and trade continuously towards the optimal exposures, updating them every minute or so.
Does this sound like a good idea, and any advice on this?
The next posts will be on the approach for feature research and universe selection.
@ScottPh77711570 @therobotjames @macrocephalopod
I would like to trade in some CEXs but due to tax / safety issues I won’t KYC on those exchanges.
Is there a way through a service giving access to sub accounts to trade on those markets?
Or do I have to go through setting up an offshore company to do it?
Part 3 of the MFT series: features and the next steps I have to figure out.
- Handling turnover to compare features (some features turn over a lot some don't)
- Going from raw feature to prediction
As always, I love the feedback thanks!

MFT series
I got pretty busy over the last few days with my other job, but I'm preparing the post on feature research.
I'm thinking hard about an issue right now and wanted to share it: evaluating feature predictiveness.
I do it as follows:
1. Compute the feature using data up to time t.
2. Compute forward returns for each asset from t + 30s to t + 1h 30s.
3. Divide the forward returns by the volatility measured from t + 30s to t + 24h.
4. Group the volatility-adjusted forward returns into 10 bins by feature value and plot the average for each bin.
The recent change I made was to adjust returns using forward volatility instead of past volatility, because of possible contamination.
That said, I'm worried the forward volatility window could cause some fuck-ups: it overlaps with the return window, so large moves inflate their own denominator.
I might just switch to a longer window, like a rolling 20-day volatility, which should be more stable and less sensitive to any single period.
Would really appreciate feedback on this
I need help from my street quants.
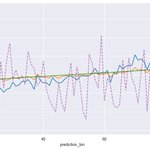
When I create features, I plot quantiles of the feature value vs forward returns, I often get this kind of results: linear positive relation in the middle, and reversion at the tails of the feature.
I added an example, of feature= 10 days returns / 10 days std. the three lines are just the same feature but on 3 terciles of the universe by ADV.
In the end, I want to use a linear model so it won’t pickup this behavior.
1. I could use a non-linear model (will probably overfit)
2. I could apply a transform to the feature such that larger values of the features gets lower.
3. I could ignore this issue
Still not figured out what the best solution is, any advice ?

Part 2 of the series where I design an MFT system: building the dataset and computing forward returns.
As always, I’m looking forward to your feedback and comments!
Writing these helps me think first and then dig into the data, which is a good way of doing it imo. You should think really hard about how you’re doing things and what it implies before you start going crazy with features and testing.
One tip I use for this process: I go outside with just something to take notes on and think about how I’m going to do things.
I first focused on building a clean dataset from public sources. I used Binance and Bybit data from 2023 to August 2025 for the training set.
Here’s what I’ve collected:
Binance
- Hourly klines for perpetuals
- AggTrades for perpetuals and spot
- Funding rates
- Depth snapshots at 0.2% and 1% market impact
Bybit
- Mid snapshots every 30s
For now, my universe is all the tickers on those exchanges. Depending on the feature analysis, I’ll decide whether to create sub-universes for the whole portfolio or per feature. Feature behavior varies across assets, e.g. trend works better on liquid stuff, reversion on illiquid stuff… Selecting the right universe is as important as the feature itself, and I think it’s often overlooked.
It’s also worth noting that anything under $1M ADV needs to be included carefully: there isn’t a continuous flow of trades during the day, so rebalancing positions in an MM fashion comes with its own problems.
I’ll use the Bybit mid snapshots to compute returns for the analysis. Using candles is a fuck-up because the close price is the last trade, not a price you can execute at. That’s a big fuck-up if you’re looking at short-horizon intraday returns, especially on assets with wide spreads: you’ll find effects that aren’t tradeable.
I use a 30s embargo between the last timestamp of a feature and the price used to compute forward returns. This is important to avoid too-good-to-be-true results from latency issues and from contamination by the market impact of trade-based features.
The next step, and it’s a big one, is creating features and figuring out whether I can use them based on their ability to predict returns (across time or cross-sectionally), their turnover, which part of the universe they work on…
I’ll start with the basics: trend, momo, carry and size. Then there are many transforms to explore on trades and order books.
If you have feature ideas and want them tested, just post them below. That could be interesting!
The next post will be on the protocol I use for testing features (by protocol I mean which plots I will be eye fucking, that’s how science is done).

How fast are the Binance feeds for MMs and how expensive is it to rent it to someone ?
I think I heard 10ms and 1k/month
Health maxxing is going out of control. I think lifting weights and eating well is the 80/20 on this.
It's a good hobby to track your health, but people are starting to look at their Whoop like it's PNL.

Hey @BullbitDEXHQ
Let me withdraw my funds or I will open source the strategy I used to pick up your internal MM and hell is going to rain on your exchange.
Looking to chat with people working on small capacity alphas. Currently in the trenches on the shittiest perp Dexs on earth.
Hit me up if you wanna chat/collab
beaver quant retweeted
For my friends who are still using UV and might be a little weary about recent compromises to PyPi packages, stick this in your pyproject.toml.
You can let all of those pip users find and report the compromises...

10% discount on vHYPE if you’re willing to take the risk of getting stuck with it.
The risk is that the team doesn’t wind down, or no new stakers come in, so you end up stuck with it.
I’m happy to hold these until they shut down or some fresh HYPE comes in. Bought some at 0.85.


big L for jupyter notebooks again:
same script is taking 14min to run in notebooks vs 2.5min in a .py file
Test in prod

It’s something I’ve seen countless times. I can’t even remember how many well-beyond-intelligent people I’ve encouraged to just do the thing instead of overthinking it.
The most common issue is that highly educated (especially mathematically minded) people feel the need to verify every assumption, run every possible test (even the ones that add zero value), and then execute everything far too slowly.
Don’t overthink it. Just do the job — especially when taking action is quicker and easier than checking every detail.