
Kafka, Scala, JVM, distributed systems, performance, machine learning, Haskell, @ConfluentInc.
San Francisco Bay Area, CA
Joined December 2008
- Tweets12.1K
- Following513
- Followers4.7K
- Likes4.3K



Ismael Juma retweeted

The #rust compiler is getting tons of improvements this year yoyo-code.com/2026-is-exciti…
Ismael Juma retweeted

JEP 544 (openjdk.org/jeps/544), the remaining part of Leyden has landed in JDK mainline. So now we can do this! This source launcher involves javac compilation, that is the bulk of the work here.

Ismael Juma retweeted

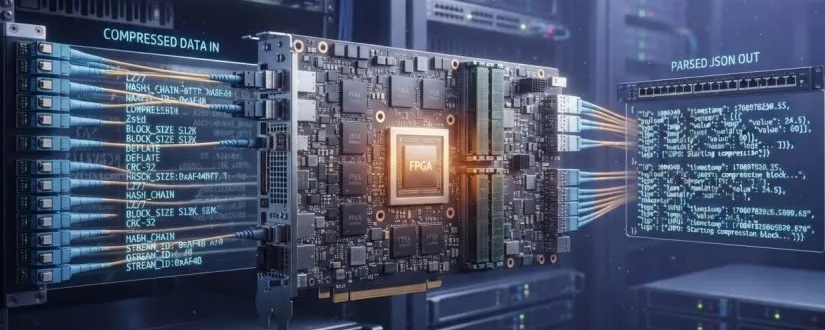
You can consume compressed JSON documents in a multithreaded manner if you use zstd for compression. This allows crazy speeds. See my article.


Ismael Juma retweeted

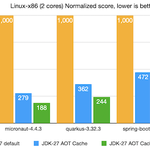
Performance Improvements in JDK 27
inside.java/2026/09/28/perfo…

Ismael Juma retweeted

Meta Releases OpenZL 0.3 With Decompression Speed 144% Faster Than Zstd
Wow!
phoronix.com/news/OpenZL-0.3…

Ismael Juma retweeted

OpenZL v0.3.0 is released :
github.com/facebook/openzl/r…
It has a faster LZ engine, close to LZ4 speeds, featuring a novel Huffman backend (PivCo), and a neural network that builds compression graphs on the fly, resulting in much higher compression ratios for numeric sources.

Ismael Juma retweeted
✅ JDK 27 shipped yesterday with Shenandoah Late Barrier Expansion (JDK-8366041), gets us 0..20% throughput bump.
🔄 JDK 28 would hopefully ship in Mar 2027 with Shenandoah Hotpatching (JDK-8384415), gets us another 0..5% throughput bump.
🤘 JDK 29 in Sep 2027 would be awesome.
Ismael Juma retweeted

If you like the compact 64-bit object headers of HotSpot in Java 27, you will love the 32-bit object headers in @GraalVM native image that are the default since Java 25 😉!

"We here propose to finalize Structured Concurrency in JDK 28, without further change" openjdk.org/jeps/543
Ismael Juma retweeted

The Rust team is calling this the largest single change to the compiler since its initial release. It just landed on nightly. 🦀
After nearly 4 years of work, the next-generation trait solver is close to stabilization. It completely replaces how rustc proves where-clauses, normalizes associated types, and reasons about generics : the deep internals most Rust code depends on without ever seeing directly.
Why it matters, concretely:
→ More than 200 known GitHub issues fixed by this change alone
→ Unblocks Type Alias Impl Trait and Return Type Notation, both stuck behind this for years
→ Opens the door to fixing remaining type system unsoundnesses
→ Fixes real bugs found in production crates like bevy and minijinja
The performance story is the most interesting part. The new solver was, in some cases, quadratically or exponentially slower than the old one. The team benchmarked the top 20,000 crates on crates.io and spent the last few weeks specifically hunting down the worst outliers.
The results are already dramatic in places: datafusion now compiles over 8x faster. A chess engine implemented entirely in Rust's type system, which used to hang the old solver completely, now compiles in about a minute.
Still nightly-only, still finding edge cases and rough error messages. But four years of foundational compiler work, tested against real-world code at genuine scale, heading toward stabilization in the coming months.
🔗 blog.rust-lang.org/2026/08/2…
#RustLang #CompilerEngineering #TypeSystems

Ismael Juma retweeted
> Co-authored-by: Aleksey Shipilev <[email protected]>
Happy to be a part of it. Now onto stabilizing the whole thing in time for JDK 28 and 29 (prospective LTS) to be released. This and lots of other goodness should make JDK 29 a very compelling migration target. Prepare now!


"At the reported irregular widths, the explicit vector kernel reaches approximately 4.7 times the throughput of the generic scalar decoder. Against the regular width-8 widening loop, the advantage falls to approximately 1.3 to 1.65 times"

on the JVM, optimizing a hot kernel is not only about writing faster code. It also requires understanding the machine code HotSpot derives from the scalar implementation.
a great blog post on this using Parquet bit-unpacking as a concrete case
cdelmonte.dev/deep-dives/unp…

The following time to peak performance analysis on constrained containers uncovered an interesting AOT Code Compilation peak perf bug.
redhatperf.github.io/post/wh…

"Goetz added JEP 401 will still likely be in preview in the next LTS release of the JDK. "Hoping for it to exit preview for 29 seems … optimistic."
share.google/hUxe4oXCK4MonhI…

